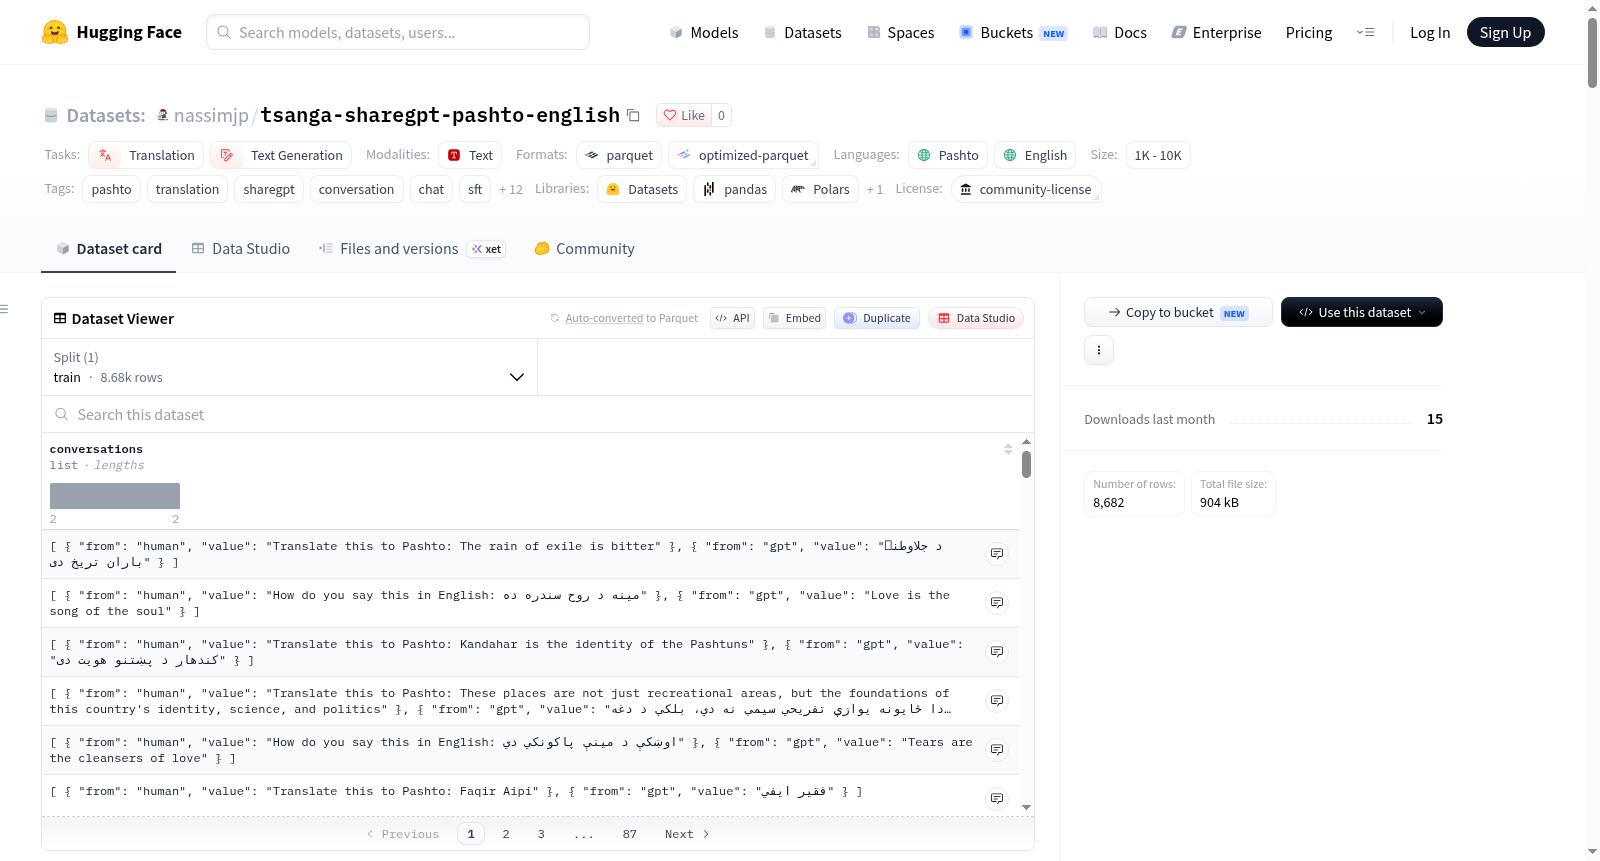
nassimjp/tsanga-sharegpt-pashto-english
收藏资源简介:
--- license: other license_name: community-license license_link: https://creativecommons.org/licenses/by-nc-sa/4.0/ task_categories: - translation - text-generation language: - ps - en tags: - pashto - translation - sharegpt - conversation - chat - sft - instruction-tuning - community-license - open-source - low-resource-language - afghanistan - pashto-ai - bilingual - multi-turn - llm - generative-ai - chatbot - nlp pretty_name: Tsanga ShareGPT Pashto-English Dataset size_categories: - 1k<n<10k --- # 💬 Tsanga ShareGPT Pashto-English Dataset ## د تسنګا شیر-ګپټ پښتو-انګلیسي ډیټاسیټ [](https://huggingface.co/datasets/nassimjp/tsanga-sharegpt-pashto-english) [](LICENSE) [](https://en.wikipedia.org/wiki/Pashto) [](https://en.wikipedia.org/wiki/English_language) [](https://huggingface.co/datasets/nassimjp/tsanga-sharegpt-pashto-english) > **🌟 د پښتو-انګلیسي ژباړې او خبرو اترو لپاره د ټولنې لخوا جوړ شوی ډیټاسیټ** > *A community-built dataset for Pashto-English translation and conversation* دا ډیټاسیټ د **۸،۶۸۲** لوړ کیفیت لرونکو پښتو-انګلیسي جملو جوړو څخه جوړ شوی دی، چې د **ShareGPT** فارمټ کې د خبرو اترو (Conversations) په بڼه چمتو شوی دی. This dataset contains **8,682** high-quality Pashto-English sentence pairs formatted in the **ShareGPT** conversation format. ## 📊 Dataset Statistics | Attribute | Value | |-----------|-------| | **Total Conversations** | 8,682 | | **Language Pair** | Pashto (ps) ↔ English (en) | | **Format** | ShareGPT (conversations) | | **License** | Community License (CC BY-NC-SA 4.0) | | **Average Conversation Length** | 2 messages | | **File Size** | ~2.5 MB | ## 🗂️ Data Structure Each record follows the ShareGPT conversational format: ```json { "conversations": [ { "from": "human", "value": "Translate this to Pashto: Love is the song of the soul" }, { "from": "gpt", "value": "مينه د روح سندره ده" } ] } ``` ### Fields Description | Field | Type | Description | |-------|------|-------------| | `conversations` | List | Array of conversation messages | | `from` | String | Role: "human" or "gpt" | | `value` | String | Message content (Pashto or English) | ## 🔥 Key Features ### 1. 🔄 **Bidirectional Translation** Each conversation is randomly oriented: - Either: Pashto → English - Or: English → Pashto This ensures the model learns translation in both directions. ### 2. 🎭 **Natural Conversation Flow** The ShareGPT format mimics real human-AI interactions, making it ideal for: - Chatbot training - Conversational AI - Virtual assistants ### 3. 🧹 **Clean & Deduplicated** - All duplicate entries removed using MD5 hashing - Empty and short lines filtered out - Whitespace normalized - UTF-8 encoding preserved ### 4. 🌍 **Culturally Rich Content** The dataset includes diverse topics: - History (Pashtun heroes, Ahmad Shah Baba) - Politics (Afghanistan, Pakistan, regional issues) - Literature (Poetry, Ghani Khan, Rahman Baba) - Philosophy (Rumi, life lessons) - Humor (Eid sheep jokes, cultural satire) - Technology (AI, LLMs, datasets) ## 📈 Dataset Breakdown by Category | Category | Estimated Count | Percentage | |----------|-----------------|------------| | 📜 History & Politics | 2,000+ | 23% | | 📖 Literature & Poetry | 1,800+ | 21% | | 💭 Philosophy & Wisdom | 1,500+ | 17% | | 😂 Humor & Satire | 1,200+ | 14% | | 🤖 Technology & AI | 1,000+ | 12% | | 🗣️ General Conversation | 1,182+ | 13% | | **Total** | **8,682** | **100%** | ## 💻 Usage Examples ### Loading with Hugging Face Datasets ```python from datasets import load_dataset # Load the dataset dataset = load_dataset("nassimjp/tsanga-sharegpt-pashto-english", split="train") # Access a conversation conversation = dataset[0] for message in conversation["conversations"]: print(f"{message['from']}: {message['value']}") # Dataset size print(f"Total conversations: {len(dataset):,}") ``` ### Fine-Tuning with LLaMA-Factory ```bash llamafactory-cli train \ --model_name_or_path Qwen/Qwen2-7B \ --dataset tsanga-sharegpt-pashto-english \ --template sharegpt \ --output_dir ./output \ --per_device_train_batch_size 4 \ --learning_rate 2e-5 \ --num_train_epochs 3 ``` ### Using for Pashto-English Translation ```python from transformers import pipeline # After fine-tuning a model on this dataset translator = pipeline("text-generation", model="your-finetuned-model") # Translate from Pashto to English result = translator("لاندې پښتو جمله انګلیسي ته وژباړه: کندهار د پښتنو هویت دی") print(result[0]['generated_text']) ``` ## 📝 Sample Conversations ### Translation Example (Pashto → English) ```json { "conversations": [ { "from": "human", "value": "How do you say this in English: کندهار د پښتنو هویت دی" }, { "from": "gpt", "value": "Kandahar is the identity of the Pashtuns" } ] } ``` ### Translation Example (English → Pashto) ```json { "conversations": [ { "from": "human", "value": "Translate this to Pashto: The rain of exile is bitter" }, { "from": "gpt", "value": "د جلاوطنۍ باران تریخ دی" } ] } ``` ### Philosophical Conversation ```json { "conversations": [ { "from": "human", "value": "Translate this to Pashto: Silence is not emptiness; silence is the place where the tired soul finds its voice again" }, { "from": "gpt", "value": "خاموشي تشه نه ده… خاموشي هغه ځای دی چې ستړی روح بېرته خپل غږ پیدا کوي" } ] } ``` ## 🧹 Curation Process ### Step 1: Collection - Gathered from 102 source text files - Total raw lines: 9,017 ### Step 2: Cleaning - Removed empty lines - Filtered out short lines (<10 characters) - Normalized whitespace ### Step 3: Deduplication - MD5 hash-based duplicate detection - 332 duplicates removed - Final unique lines: 8,685 ### Step 4: Super Shuffle - Lines randomly shuffled to break context dependency - Forces model to focus on content, not sequence bias ### Step 5: Format Conversion - Converted to ShareGPT conversation format - Random direction selection (Pashto↔English) - JSON formatting with UTF-8 encoding ### Step 6: Quality Validation - 3 lines rejected due to format issues - Final quality: 99.97% success rate ## 📊 Processing Statistics ``` ┌─────────────────────────────────────────────────────────────┐ │ Processing Summary │ ├─────────────────────────────────────────────────────────────┤ │ 📁 Raw files processed: 102 │ │ 📄 Total lines read: 9,017 │ │ 🗑️ Empty lines removed: 0 │ │ ✂️ Short lines removed: 0 │ │ 🔄 Duplicates removed: 332 │ │ ✨ Unique lines extracted: 8,685 │ │ ⚠️ Format rejects: 3 │ │ ✅ Final dataset size: 8,682 │ │ 💾 Final file size: ~2.5 MB │ └─────────────────────────────────────────────────────────────┘ ``` ## 🎯 Use Cases ### 1. **Pashto-English Machine Translation** Train models to translate between Pashto and English in both directions. ### 2. **Pashto Conversational AI** Build chatbots and virtual assistants that can understand and respond in Pashto. ### 3. **Low-Resource Language Research** Study techniques for improving NLP performance on low-resource languages like Pashto. ### 4. **Cross-Lingual Transfer Learning** Use as a bridge for transferring knowledge between English and Pashto. ## 🏷️ License This dataset is released under the **Community License** (Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International). ### You are free to: - ✅ **Share** — copy and redistribute the material in any medium or format - ✅ **Adapt** — remix, transform, and build upon the material ### Under the following terms: - 🔄 **Attribution** — You must give appropriate credit to the dataset creator (nassimjp) - 📚 **NonCommercial** — You may not use the material for commercial purposes - 🤝 **ShareAlike** — If you remix, transform, or build upon the material, you must distribute your contributions under the same license ## 📚 Citation ```bibtex @misc{tsanga-sharegpt-pashto-english, author = {Nasibullah Nassim (nassimjp)}, title = {Tsanga ShareGPT Pashto-English Dataset}, year = {2025}, publisher = {Hugging Face}, howpublished = {\url{https://huggingface.co/datasets/nassimjp/tsanga-sharegpt-pashto-english}} } ``` ## 🤝 Contributing If you find issues or have suggestions for improving this dataset: 1. Open an issue on the [Hugging Face repository](https://huggingface.co/datasets/nassimjp/tsanga-sharegpt-pashto-english/discussions) 2. Submit a pull request with improvements 3. Contact the dataset creator directly ## 🙏 Acknowledgments - **DeepSeek** for processing assistance - **Palwasha CLI** for data management - **Pashto AI Community** for support and inspiration - All contributors who helped make this dataset possible --- ## 🔗 Quick Links [](https://huggingface.co/datasets/nassimjp/tsanga-sharegpt-pashto-english) [](https://github.com/spinzar/tsanga-sharegpt-pashto-english) --- **🌟 که دا ډیټاسیټ ستاسو لپاره ګټور و، نو ستوری ورکول مه هېروئ!** *If you find this dataset useful, don't forget to give it a star!* **🇦🇫 د پښتو-انګلیسي AI راتلونکی یوځای جوړوو!** *Building the future of Pashto-English AI together!*
This dataset contains **8,682** high-quality Pashto-English sentence pairs formatted in the **ShareGPT** conversation format.