oumayma03/darija_bible
收藏资源简介:
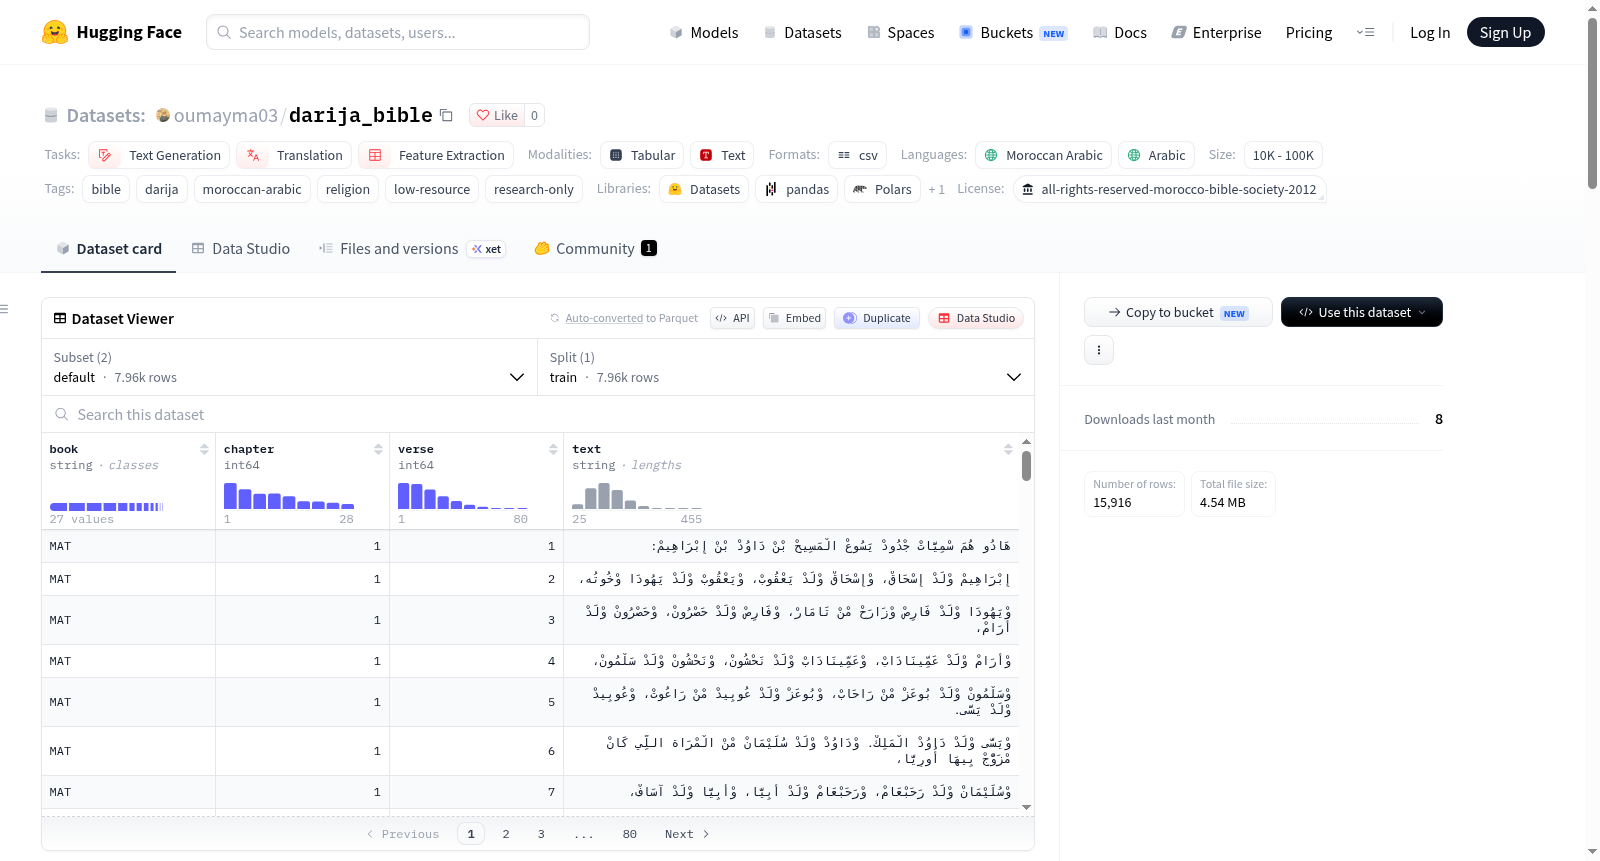
--- license: other license_name: all-rights-reserved-morocco-bible-society-2012 license_link: https://www.bible.com/fr/versions/558 language: - ary - ar pretty_name: Darija Bible (MSTD) size_categories: - 1K<n<10K task_categories: - text-generation - translation - feature-extraction tags: - bible - darija - moroccan-arabic - religion - low-resource - research-only configs: - config_name: default data_files: - split: train path: data/bible_MSTD_ALL.csv - config_name: by_book data_files: - split: MAT path: books/MAT.csv - split: MRK path: books/MRK.csv - split: LUK path: books/LUK.csv - split: JHN path: books/JHN.csv - split: ACT path: books/ACT.csv - split: ROM path: books/ROM.csv - split: b1CO path: books/1CO.csv - split: b2CO path: books/2CO.csv - split: GAL path: books/GAL.csv - split: EPH path: books/EPH.csv - split: PHP path: books/PHP.csv - split: COL path: books/COL.csv - split: b1TH path: books/1TH.csv - split: b2TH path: books/2TH.csv - split: b1TI path: books/1TI.csv - split: b2TI path: books/2TI.csv - split: TIT path: books/TIT.csv - split: PHM path: books/PHM.csv - split: HEB path: books/HEB.csv - split: JAS path: books/JAS.csv - split: b1PE path: books/1PE.csv - split: b2PE path: books/2PE.csv - split: b1JN path: books/1JN.csv - split: b2JN path: books/2JN.csv - split: b3JN path: books/3JN.csv - split: JUD path: books/JUD.csv - split: REV path: books/REV.csv --- # Darija Bible — Moroccan Standard Translation (MSTD) The full **New Testament** translated into **Moroccan Darija** (الترجمة المغربية القياسية, *MSTD*). Moroccan Darija is a **low-resource** spoken Arabic variety. This dataset is published here as a research artifact for language modeling, fine-tuning, machine translation between Darija and other languages, and evaluation of multilingual / Arabic-dialect models. --- ## ⚠️ Copyright notice — please read before using **This dataset reproduces a copyrighted translation.** It is published here in good faith as a research/personal-use artifact, but the underlying text is **not** under any open license. - **Original work:** *الترجمة المغربية القياسية* (Moroccan Standard Translation, *MSTD*) — New Testament. - **Copyright holder:** © 2012 **Morocco Bible Society** / دار الكتاب المقدس بالمغرب. **All rights reserved.** - **Source page:** [YouVersion / bible.com, version 558](https://www.bible.com/fr/versions/558). - **How the data was obtained:** scraped from the public HTML pages of bible.com. - **License of this redistribution:** **none granted.** Posting here does not transfer or imply any rights. You should treat the text as fully copyrighted and consult the original publisher before any non-research use. ### Acceptable use (in the maintainer's understanding, *not* legal advice) - Personal study, academic research, and quantitative/NLP experiments on the text. - Reporting aggregate statistics, training tokenizers, evaluating language models, etc. ### Probably **not** acceptable without explicit permission from the Morocco Bible Society - Re-publishing the text in another product, app, book, website, or downstream dataset. - Commercial use of any kind. - Distributing model checkpoints whose primary purpose is to reproduce this translation verbatim. ### Takedown / rights-holder request If you are the Morocco Bible Society, YouVersion, or any other party with rights to this translation and you would like this dataset **made private or removed**, please open a **Discussion** on this dataset page or contact the dataset owner directly. The dataset will be taken down promptly upon request. --- ## Contents - **27 books** (the entire New Testament — the MSTD translation does not cover the Old Testament). - **7,958 verses**. - One row per verse. ### Files | Path | Description | |------|-------------| | `data/bible_MSTD_ALL.csv` | Combined corpus, all 27 books (default config) | | `books/<USFM>.csv` | One file per book (used by the `by_book` config) | ### Schema | Column | Type | Example | |--------|------|---------| | `book` | string (USFM code) | `MAT`, `JHN`, `1CO` | | `chapter` | string | `"1"`, `"28"` | | `verse` | string | `"1"`, `"23"` | | `text` | string | verse text in Moroccan Darija (Arabic script) | ## Quick start ```python from datasets import load_dataset # Whole NT as a single train split ds = load_dataset("oumayma03/darija_bible") print(ds["train"][0]) # {'book': 'MAT', 'chapter': '1', 'verse': '1', 'text': 'هَادُو هُمَ ...'} # One split per book (book codes starting with a digit are prefixed 'b', e.g. b1CO) ds_by_book = load_dataset("oumayma03/darija_bible", "by_book") print(list(ds_by_book.keys())) # ['MAT', 'MRK', ..., 'b1CO', ...] print(ds_by_book["MAT"][0]) ``` ## Books included (USFM codes) `MAT`, `MRK`, `LUK`, `JHN`, `ACT`, `ROM`, `1CO`, `2CO`, `GAL`, `EPH`, `PHP`, `COL`, `1TH`, `2TH`, `1TI`, `2TI`, `TIT`, `PHM`, `HEB`, `JAS`, `1PE`, `2PE`, `1JN`, `2JN`, `3JN`, `JUD`, `REV`. ## Preprocessing - Cross-reference markers (e.g. `#لوقا 1:27`) embedded in the source HTML have been **stripped** so each row contains only the verse text. - Verses split across paragraph blocks (poetry, etc.) are reassembled into a single row. - Whitespace is normalized to single spaces. ## How to credit The translation itself should always be credited to the **Morocco Bible Society (2012)**: ```bibtex @misc{mstd_darija_nt_2012, title = {الترجمة المغربية القياسية — العهد الجديد}, shorttitle= {MSTD — Moroccan Standard Translation, New Testament}, author = {Morocco Bible Society}, year = {2012}, publisher = {دار الكتاب المقدس بالمغرب}, url = {https://www.bible.com/fr/versions/558}, note = {Copyright © 2012 Morocco Bible Society. All rights reserved.} } ```
The full New Testament translated into Moroccan Darija (Moroccan Standard Translation, MSTD). Moroccan Darija is a low-resource spoken Arabic variety. This dataset is published here as a research artifact for language modeling, fine-tuning, machine translation between Darija and other languages, and evaluation of multilingual / Arabic-dialect models. The dataset includes 27 books (the entire New Testament) with 7,958 verses, one row per verse. Files are provided in CSV format, including a combined corpus and separate files per book. Preprocessing involves stripping cross-reference markers, reassembling verses split across paragraph blocks, and normalizing whitespace.