StableSemantics
收藏资源简介:
StableSemantics是由卡内基梅隆大学创建的一个综合语言-视觉数据集,包含224,000个人工策划的提示、超过200万合成图像和1000万个对应于单个名词块的注意力图。该数据集利用人类生成的提示,生成视觉上引人入胜的稳定扩散图像,每条提示提供10个生成图像,并提取每个图像的交叉注意力图。数据集的创建过程涉及从用户提交的提示中筛选和转换为自然语言描述,然后使用Stable Diffusion XL模型生成图像,并记录文本到图像的交叉注意力图。StableSemantics旨在推动视觉语义理解的研究,为开发更复杂、有效的视觉模型提供基础,特别关注于解决语义概念与视觉外观之间的差异问题。
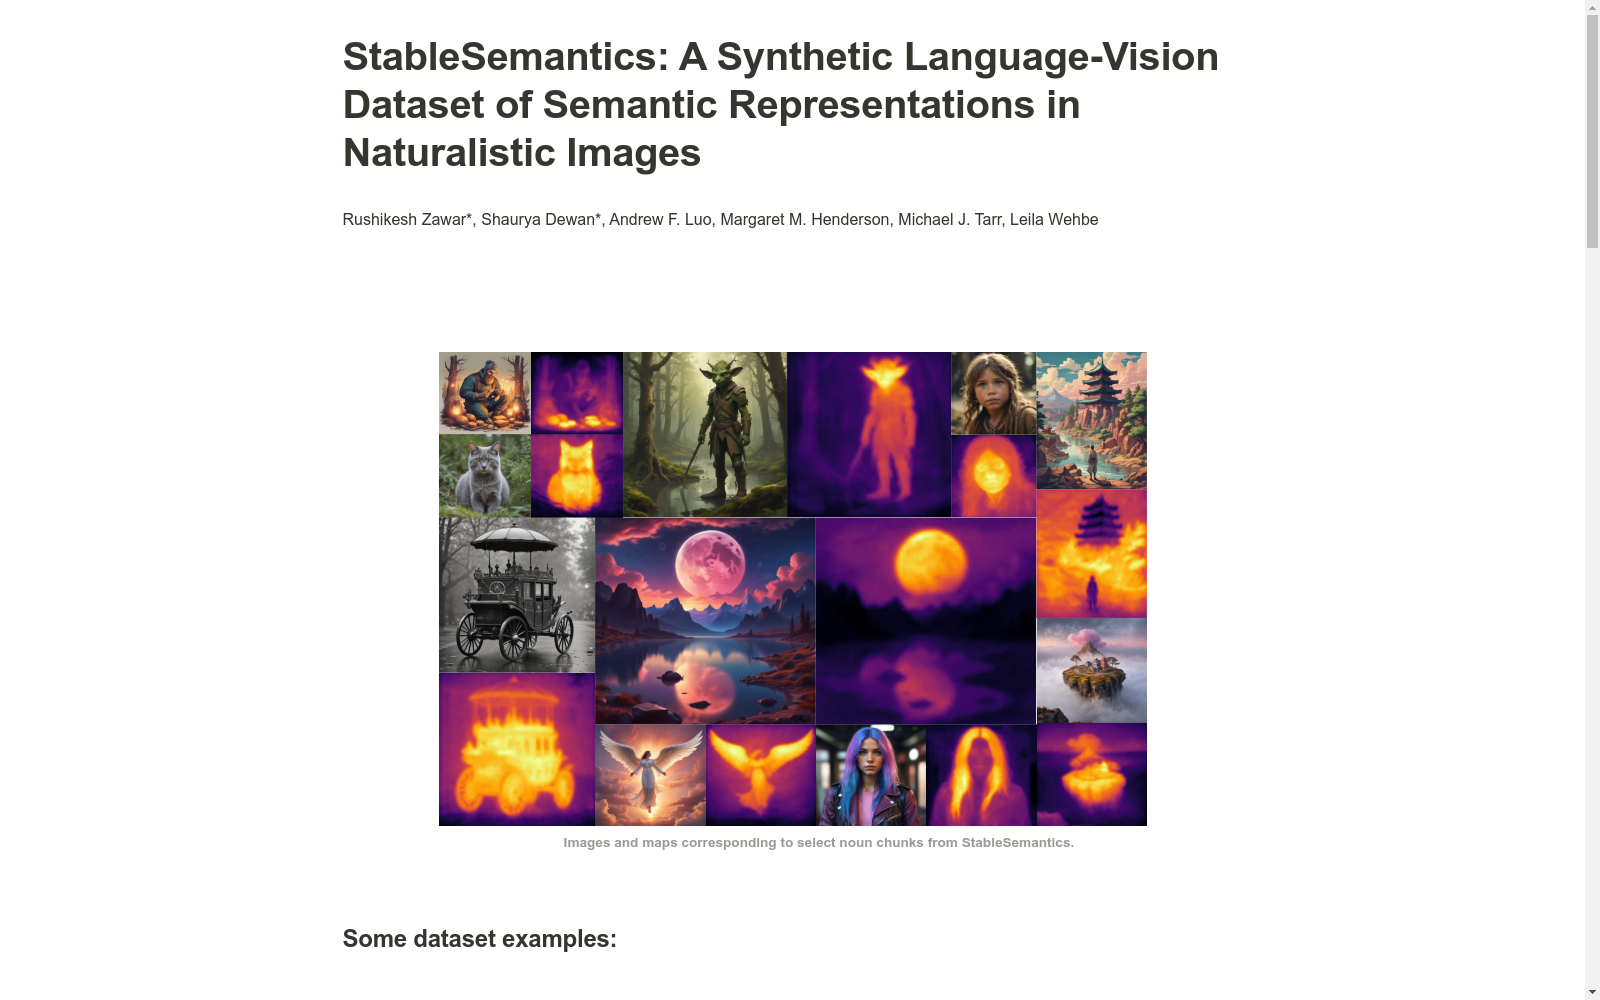
StableSemantics is a comprehensive language-vision dataset developed by Carnegie Mellon University. It contains 224,000 manually curated prompts, over 2 million synthetic images, and 10 million attention maps corresponding to individual noun chunks. This dataset utilizes human-generated prompts to produce visually compelling Stable Diffusion images, with 10 generated images per prompt, and extracts the cross-attention maps for each generated image. The dataset construction process involves filtering user-submitted prompts and converting them into natural language descriptions, then generating images via the Stable Diffusion XL model, and recording text-to-image cross-attention maps. StableSemantics aims to advance research in visual semantic understanding, providing a foundational resource for developing more sophisticated and effective visual models, with a particular focus on addressing the discrepancy between semantic concepts and their corresponding visual appearances.