
Open Australian Legal Corpus
收藏资源简介:
Open Australian Legal Corpus是由蒙纳士大学创建的澳大利亚法律语料库,专门用于法律引用预测任务。该数据集包含55,005个实例,涵盖18,677个独特的法律引用,主要来源于新南威尔士州的案例法。数据集的创建过程包括从案例文本中提取引用句及其上下文,并使用大型语言模型生成辅助描述。该数据集主要应用于法律领域的引用预测,旨在提高法律文本中引用预测的准确性,特别是在澳大利亚法律背景下。
The Open Australian Legal Corpus is an Australian legal corpus developed by Monash University, exclusively designed for legal citation prediction tasks. This dataset comprises 55,005 instances, encompassing 18,677 unique legal citations, primarily sourced from the case law of New South Wales. The dataset construction process involves extracting citation sentences and their contextual information from case texts, and leveraging large language models (LLMs) to generate auxiliary descriptions. This dataset is primarily applied to citation prediction tasks in the legal field, aiming to improve the accuracy of citation prediction in legal texts, especially within the context of Australian law.
Open Australian Legal Corpus
概述
Open Australian Legal Corpus 是首个也是唯一一个多司法管辖区的澳大利亚立法和司法文档开放语料库。该语料库包含229,122个文本,总计超过8000万行和14亿个标记,涵盖了澳大利亚联邦、新南威尔士州、昆士兰州、西澳大利亚州、南澳大利亚州、塔斯马尼亚州和诺福克岛的所有现行法规和条例,以及数千个法案和数十万个法院及法庭判决。
数据集信息
- 语言: 英语 (en)
- 许可证: 其他 (other)
- 大小: 100K<n<1M
- 源数据集:
- 联邦立法登记处
- 澳大利亚联邦法院
- 澳大利亚高等法院
- 新南威尔士州判例法
- 新南威尔士州立法
- 昆士兰州立法
- 西澳大利亚州立法
- 南澳大利亚州立法
- 塔斯马尼亚州立法
- 任务类别:
- 文本生成
- 填充掩码
- 文本检索
- 任务ID:
- 语言建模
- 掩码语言建模
- 文档检索
数据集结构
- 配置:
corpus - 数据文件:
corpus.jsonl - 特征:
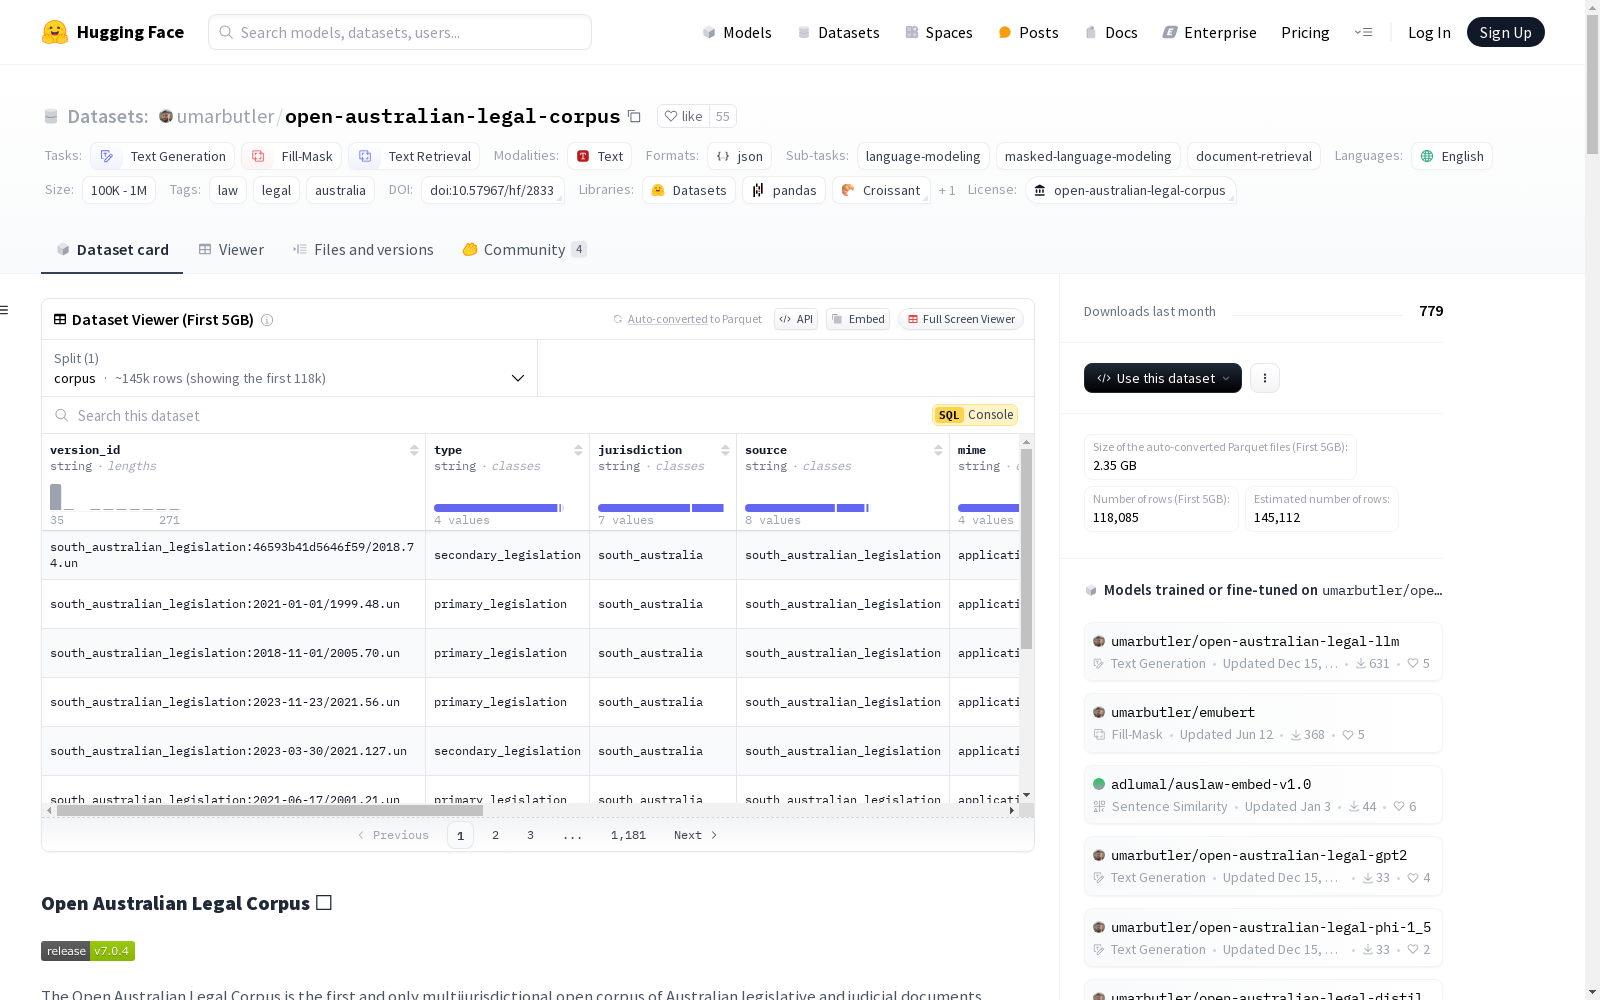
version_id: 字符串,文档最新版本的唯一标识符。type: 字符串,文档类型,可能的值包括primary_legislation,secondary_legislation,bill,decision。jurisdiction: 字符串,文档的司法管辖区,可能的值包括commonwealth,new_south_wales,queensland,western_australia,south_australia,tasmania,norfolk_island。source: 字符串,文档的来源,可能的值包括federal_register_of_legislation,federal_court_of_australia,high_court_of_australia,nsw_caselaw,nsw_legislation,queensland_legislation,western_australian_legislation,south_australian_legislation,tasmanian_legislation。mime: 字符串,文档文本的MIME类型。date: 字符串,文档的ISO 8601日期 (YYYY-MM-DD) 或null(如果日期不可用)。citation: 字符串,文档的标题,立法和法案的情况下,附有缩写的司法管辖区。url: 字符串,文档最新版本的超链接。when_scraped: 字符串,文档被抓取的ISO 8601时区感知时间戳 (YYYY-MM-DDTHH:MM:SS±HH:MM)。text: 字符串,文档最新版本的文本。
统计信息
- 文档总数: 229,122
- 总行数: 80,392,096
- 总标记数: 1,446,388,238
- 文档来源:
- HTML: 209,118 (91.27%)
- PDF: 15,794 (6.89%)
- Word文档: 2,509 (1.10%)
- RTF: 1,701 (0.74%)
文档类型和来源统计
| 来源 | 主要立法 | 次要立法 | 法案 | 判决 | 总计 |
|---|---|---|---|---|---|
| 联邦立法登记处 | 4,760 | 26,817 | 31,577 | ||
| 澳大利亚联邦法院 | 62,841 | 62,841 | |||
| 澳大利亚高等法院 | 9,454 | 9,454 | |||
| 新南威尔士州判例法 | 114,412 | 114,412 | |||
| 新南威尔士州立法 | 1,430 | 798 | 2,228 | ||
| 昆士兰州立法 | 573 | 432 | 2,285 | 3,290 | |
| 西澳大利亚州立法 | 813 | 750 | 1,563 | ||
| 南澳大利亚州立法 | 554 | 468 | 196 | 1,218 | |
| 塔斯马尼亚州立法 | 854 | 1,685 | 2,539 | ||
| 总计 | 8,984 | 30,950 | 2,481 | 186,707 | 229,122 |
许可证
该语料库及其所有文档均在开源许可证下分发,允许非商业和商业用途(详见 许可证)。
引用
如果您的研究使用了该语料库,请引用: bibtex @misc{butler-2024-open-australian-legal-corpus, author = {Butler, Umar}, year = {2024}, title = {Open Australian Legal Corpus}, publisher = {Hugging Face}, version = {7.0.4}, doi = {10.57967/hf/2833}, url = {https://huggingface.co/datasets/umarbutler/open-australian-legal-corpus} }
- 1Methods for Legal Citation Prediction in the Age of LLMs: An Australian Law Case Study蒙纳士大学 · 2024年


