story-summeval
收藏资源简介:
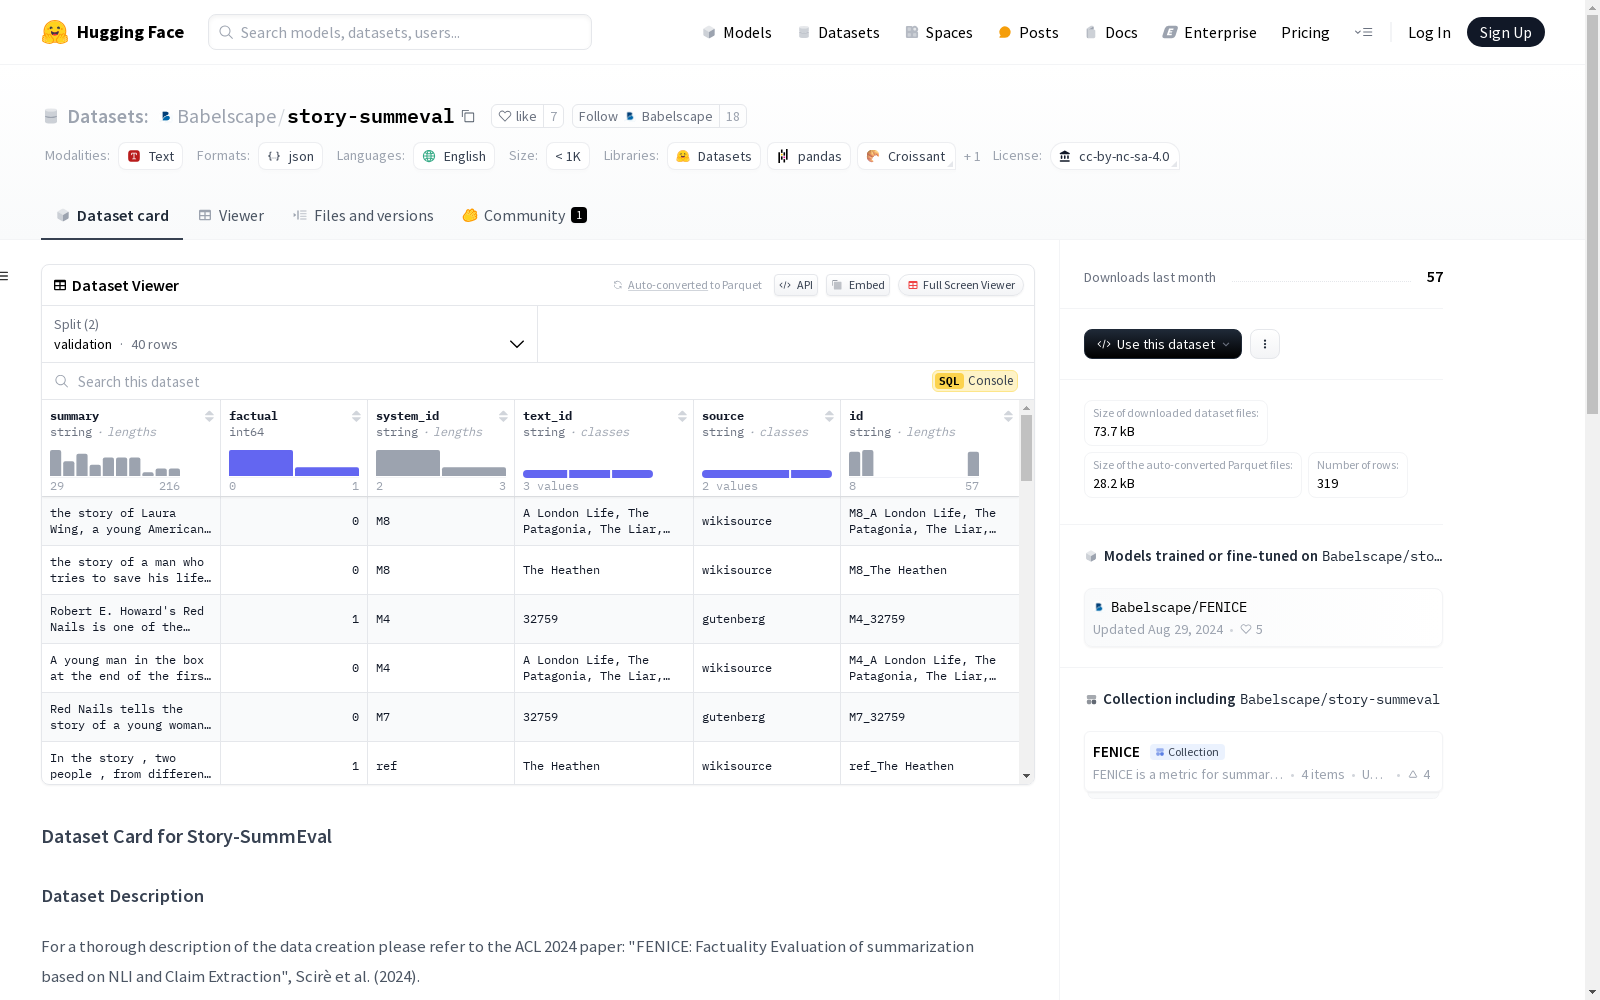
Story-SummEval数据集包含来自Gutenberg和Wikisource的故事摘要及其事实标签。这些摘要是通过多个模型生成的,数据集包含319个(摘要,标签)对。每个条目包括摘要、事实标签、原始故事文本的标识符和来源。故事文本可通过标识符在相应数据集中检索。
The Story-SummEval dataset comprises story summaries and their factual labels sourced from Gutenberg and Wikisource. These summaries are generated by multiple models, and the dataset contains 319 (summary, label) pairs in total. Each entry includes the summary, factual label, the identifier of the original story text, and its source. The original story text can be retrieved from the corresponding datasets via the identifier.
数据集卡片 for Story-SummEval
数据集描述
概述
该数据集包含来自Gutenberg和Wikisource的故事摘要及其事实标签。摘要由Scirè等人在2023年的论文《Echoes from Alexandria》中提供的多个模型生成。
组成
- (摘要, 标签)对的数量: 319
- 来源:
- Gutenberg
- Wikisource
数据集结构
每个条目包含以下内容:
summary: 故事的摘要。label: 摘要的事实标签。text_id: 原始故事文本的标识符。source: 故事文本的来源(gutenberg 或 wikisource)。
获取故事文本的方法:
- 如果来源是gutenberg,将
text_id值与manu/project_gutenberg数据集的en分区的id列匹配。 - 如果来源是wikisource,将
text_id值与wikimedia/wikisource数据集的20231201.en分区的title列匹配。
引用信息
bibtex @inproceedings{scire-etal-2024-fenice, title = "FENICE: Factuality Evaluation of summarization based on Natural language Inference and Claim Extraction", author = "Scirè, Alessandro and Karim, Ghonim and Navigli, Roberto", booktitle = "Findings of the Association for Computational Linguistics: ACL 2024", month = aug, year = "2024", address = "Bangkok, Thailand", publisher = "Association for Computational Linguistics", }