Urdu-Instruct
收藏资源简介:
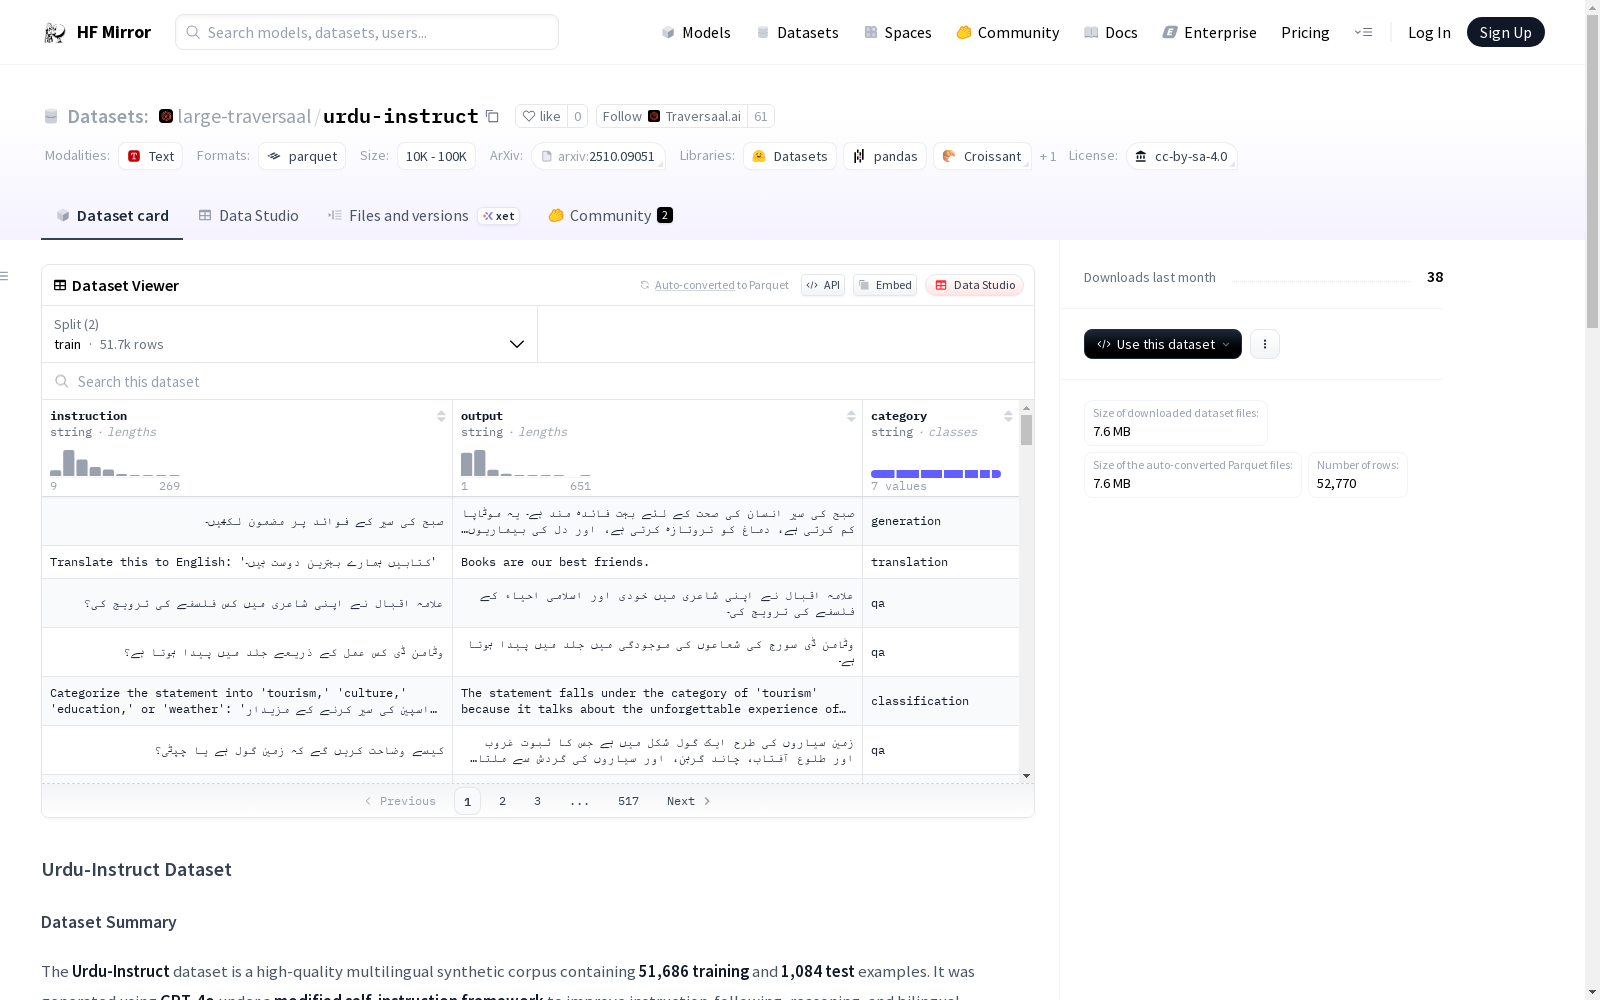
Urdu-Instruct数据集是一个高质量的多语言合成数据集,包含51686个示例,用于提高Alif-1.0-8B-Instruct模型在乌尔都语任务上的性能。该数据集使用改进的self-instruct技术生成,涵盖了文本生成、伦理和安全考虑、事实问答、逻辑推理、双语翻译、分类和情感分析等多个领域。每个任务都设计了独特的提示和种子值,以确保生成的指令具有文化多样性和任务特定性。此外,该数据集还引入了基于乌尔都语思维链的推理任务,以提高模型的逻辑推理能力。
The Urdu-Instruct dataset is a high-quality multilingual synthetic dataset containing 51,686 examples, designed to enhance the performance of the Alif-1.0-8B-Instruct model on Urdu-language tasks. This dataset is generated using an improved self-instruct technique, covering multiple domains including text generation, ethical and safety considerations, factual question answering, logical reasoning, bilingual translation, classification, and sentiment analysis. Each task is equipped with unique prompts and seed values to ensure the generated instructions possess cultural diversity and task specificity. Additionally, this dataset introduces Urdu-language Chain-of-Thought based reasoning tasks to further improve the model's logical reasoning capabilities.