1gb-test-neural-nopack
收藏资源简介:
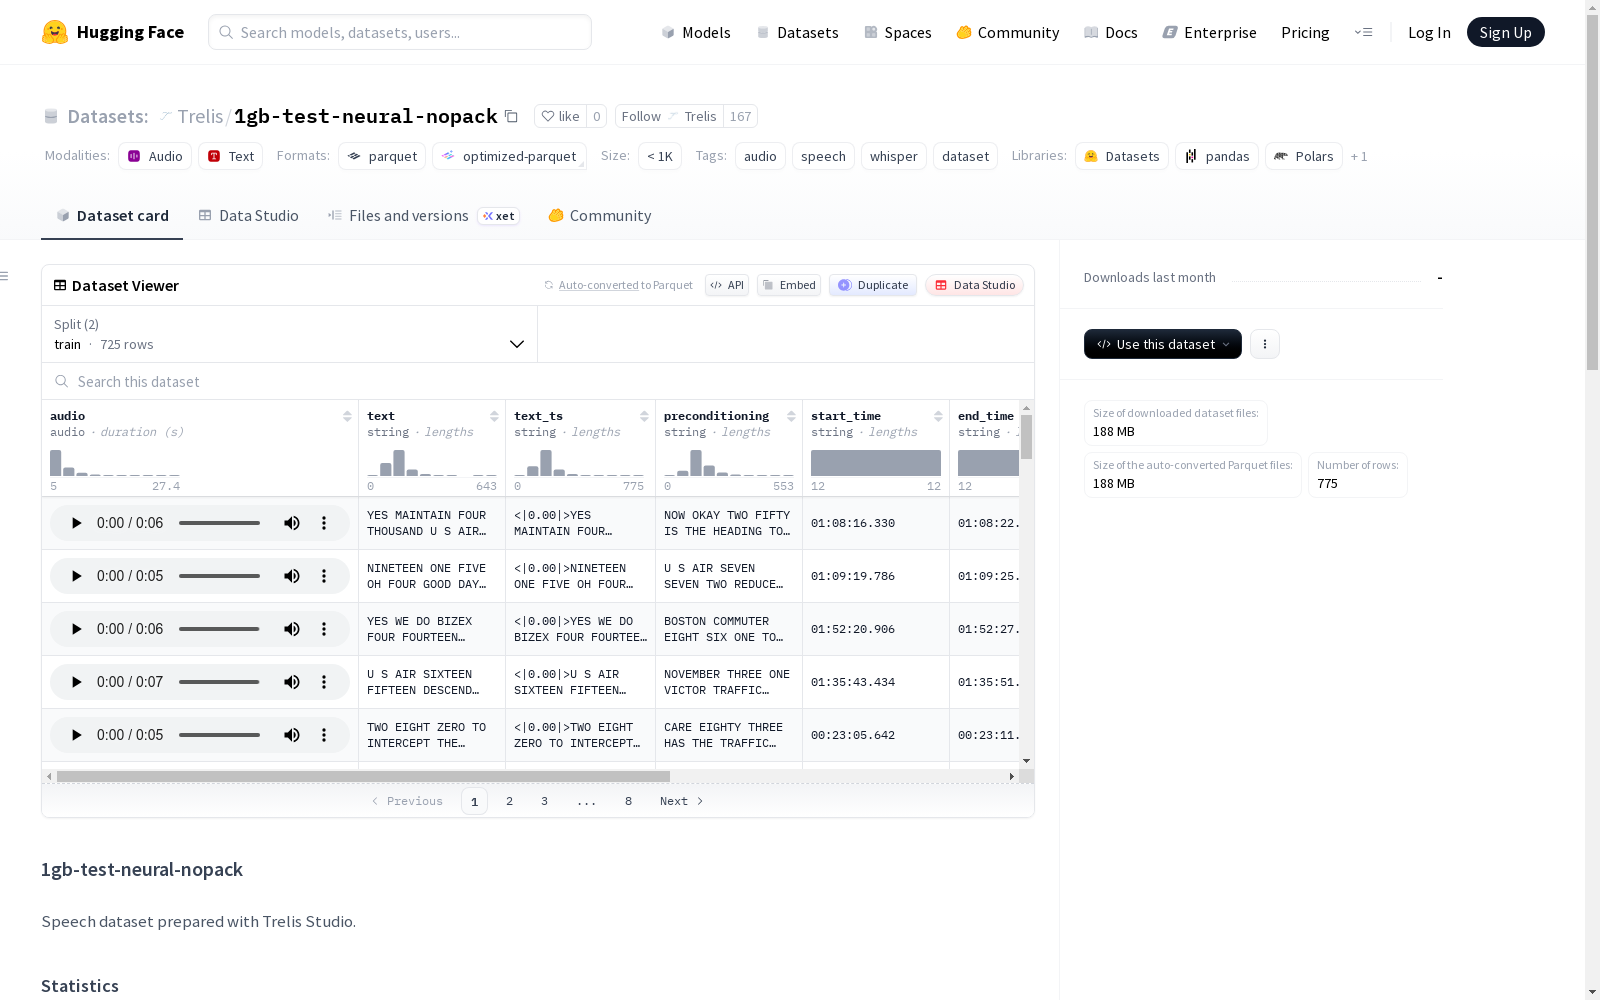
1gb-test-neural-nopack 是一个专门为 Whisper 模型训练准备的语音数据集,由 Trelis Studio 制作。该数据集包含 5 个源文件,共计 725 个训练样本和 50 个验证样本,总时长为 587.1 分钟。数据集中的每个样本包含以下字段:音频片段(16kHz,经过 VAD 处理去除静音)、纯文本转录(无时间戳)、带 Whisper 时间戳标记的转录、原始音频中的片段起止时间、语音持续时间(不包括静音)、词级时间戳以及源文件名。数据集经过 Silero VAD 处理,确保训练数据与推理行为匹配。特别适用于 Whisper 时间戳训练,建议采用两桶策略:50%使用纯文本转录,50%使用带时间戳标记的转录。
1gb-test-neural-nopack is a speech dataset dedicated to Whisper model training, developed by Trelis Studio. It contains 5 source files, with a total of 725 training samples and 50 validation samples, and a cumulative duration of 587.1 minutes. Each sample in the dataset includes the following fields: audio segment (16kHz, with silence removed via VAD processing), plain text transcription (without timestamps), transcription with Whisper timestamps, start and end timestamps of the segment in the original audio, speech duration (excluding silent segments), word-level timestamps, and source filename. The dataset is processed using Silero VAD to ensure alignment between training data and inference behavior. It is particularly suitable for Whisper timestamp training, and a two-bucket strategy is recommended: 50% using plain text transcriptions and 50% using transcriptions with Whisper timestamp markers.