en-ru-filtered-dict-20m-corpus
收藏资源简介:
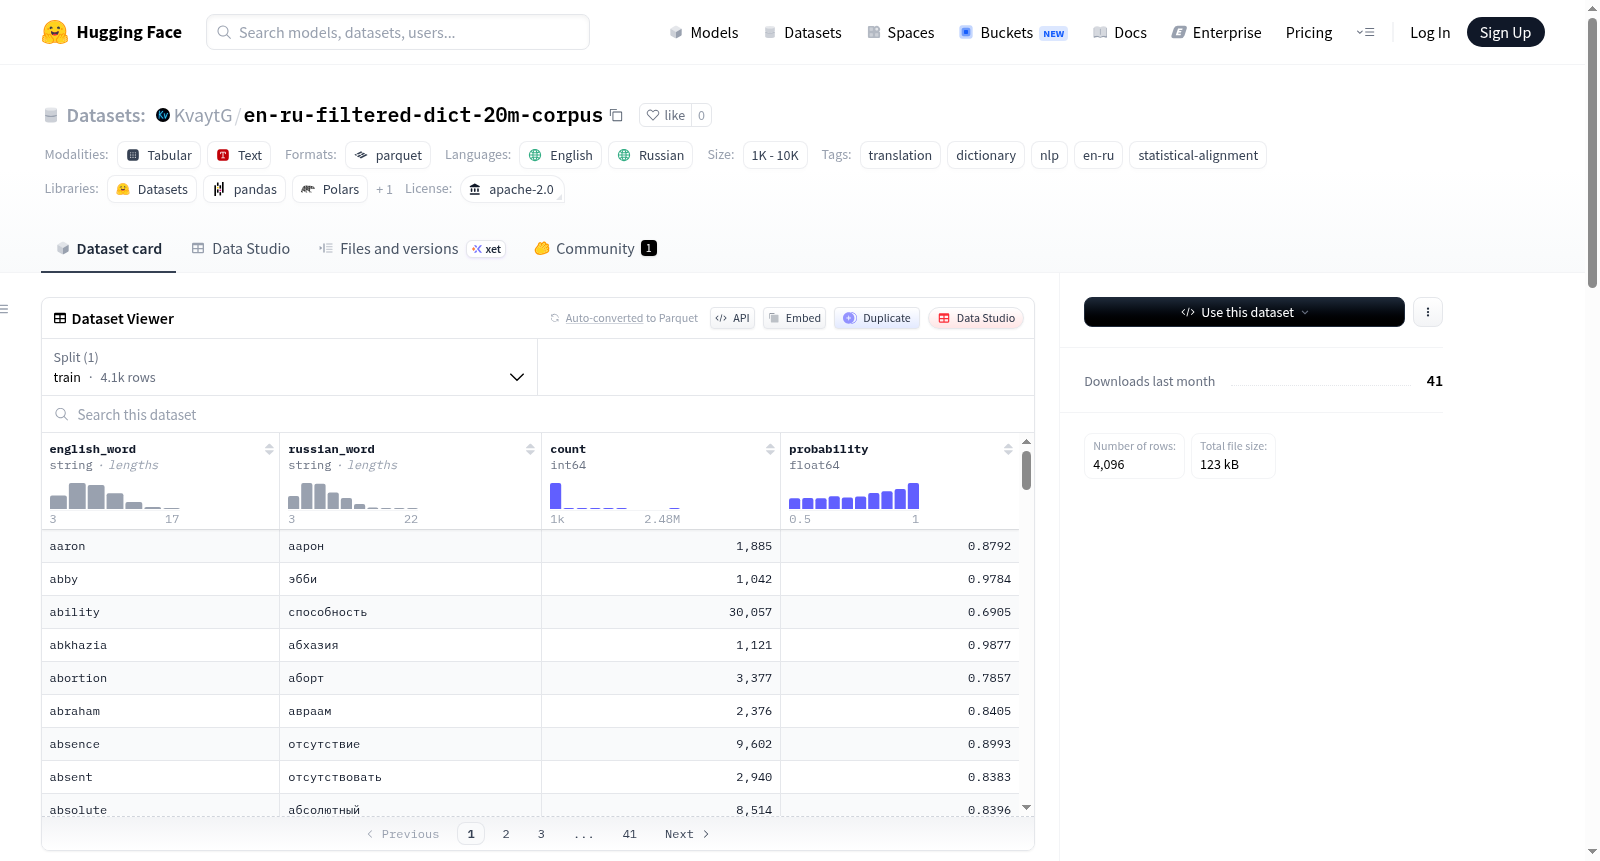
该数据集是 [en-ru-statistical-dict-20m-corpus](https://huggingface.co/datasets/KvaytG/en-ru-statistical-dict-20m-corpus) 的过滤版本,旨在为英俄翻译任务提供一个“无噪声”的核心词典,特别关注现代语料库中最常见的词汇。原始数据集来源于一个包含2000万句子的平行语料库,而本版本通过严格筛选,仅保留最可靠和频繁的词对。 筛选标准包括: 1. **高频词对**:仅保留源语料库中出现次数 `count >= 1000` 的词对。 2. **统计置信度**:仅包含翻译概率 `probability >= 0.5` 的词对。 数据集结构包含以下字段: - `english_word`:英语源词。 - `russian_word`:对应的俄语翻译。 - `count`:该词对在原始2000万句子语料库中的出现次数。 - `probability`:统计翻译概率(0.0到1.0)。 数据集规模为4,096个样本,适用于英俄翻译任务、词典构建和自然语言处理研究。数据集采用Apache License 2.0许可,主要用于研究和教育目的。
This dataset is a filtered version of [en-ru-statistical-dict-20m-corpus](https://huggingface.co/datasets/KvaytG/en-ru-statistical-dict-20m-corpus), developed to provide a noise-free core dictionary for English-Russian translation tasks, with a particular focus on the most prevalent vocabulary in modern corpora. The original dataset originates from a parallel corpus containing 20 million sentences, and this filtered version retains only the most reliable and frequent word pairs through strict screening criteria. The screening criteria are as follows: 1. **High-frequency Word Pairs**: Only retain word pairs with an occurrence count `count >= 1000` in the source corpus. 2. **Statistical Confidence**: Only include word pairs with a translation probability `probability >= 0.5`. The dataset contains the following fields: - `english_word`: The English source word. - `russian_word`: The corresponding Russian translation. - `count`: The number of occurrences of this word pair in the original 20-million-sentence parallel corpus. - `probability`: The statistical translation probability, ranging from 0.0 to 1.0. This dataset comprises 4,096 samples, which is suitable for English-Russian translation tasks, dictionary construction, and natural language processing (NLP) research. It is licensed under the Apache License 2.0, primarily intended for research and educational purposes.
en-ru-filtered-dict-20m-corpus 数据集概述
数据集基本信息
- 许可证: Apache License 2.0
- 语言: 英语 (en)、俄语 (ru)
- 标签: translation, dictionary, nlp, en-ru, statistical-alignment
- 数据规模: 1K<n<10K
- 训练集样本数量: 4096
数据集描述
本数据集是 en-ru-statistical-dict-20m-corpus 的过滤版本。原始数据集源自一个包含2000万句的平行语料库,而此版本专注于最可靠和频繁的单词对。
该版本的目标是为英俄翻译任务提供一个“无噪声”的核心词典,特别针对现代语料库中最常见的词汇。
过滤标准
为确保高质量,对原始统计数据应用了以下严格过滤器:
- 高频率: 仅保留源语料库中总
count >= 1000的单词对。 - 统计置信度: 仅包含
probability >= 0.5的对。
数据结构
数据集包含以下列:
english_word: 英语源词。russian_word: 对应的俄语翻译。count: 该词对在原始2000万句语料库中出现的次数。probability: 统计翻译概率 (0.0 至 1.0)。
使用方法
python from datasets import load_dataset dataset = load_dataset("KvaytG/en-ru-filtered-dict-20m-corpus", split="train")
法律声明
- 免责声明: 该数据集是 en-ru-parallel-20m 语料库经过高度过滤的统计衍生品。通过应用严格阈值 (count ≥ 1000, prob ≥ 0.5),我们提取了最稳定的词汇对齐。虽然源数据包含来自OPUS项目的聚合语料库,但此过滤版本代表一般的语言事实和统计概率,而非特定的受版权保护的序列。它主要供研究和教育目的使用。
引用
bibtex @misc{kvaytg_en_ru_filtered_dict_20m_corpus, author = {KvaytG}, title = {Filtered English-Russian Statistical Dictionary}, year = {2026}, publisher = {Hugging Face}, journal = {Hugging Face Datasets}, url = {https://huggingface.co/datasets/KvaytG/en-ru-filtered-dict-20m-corpus}, note = {Filtered version of en-ru-statistical-dict-20m-corpus (count ≥ 1000, prob ≥ 0.5)} }