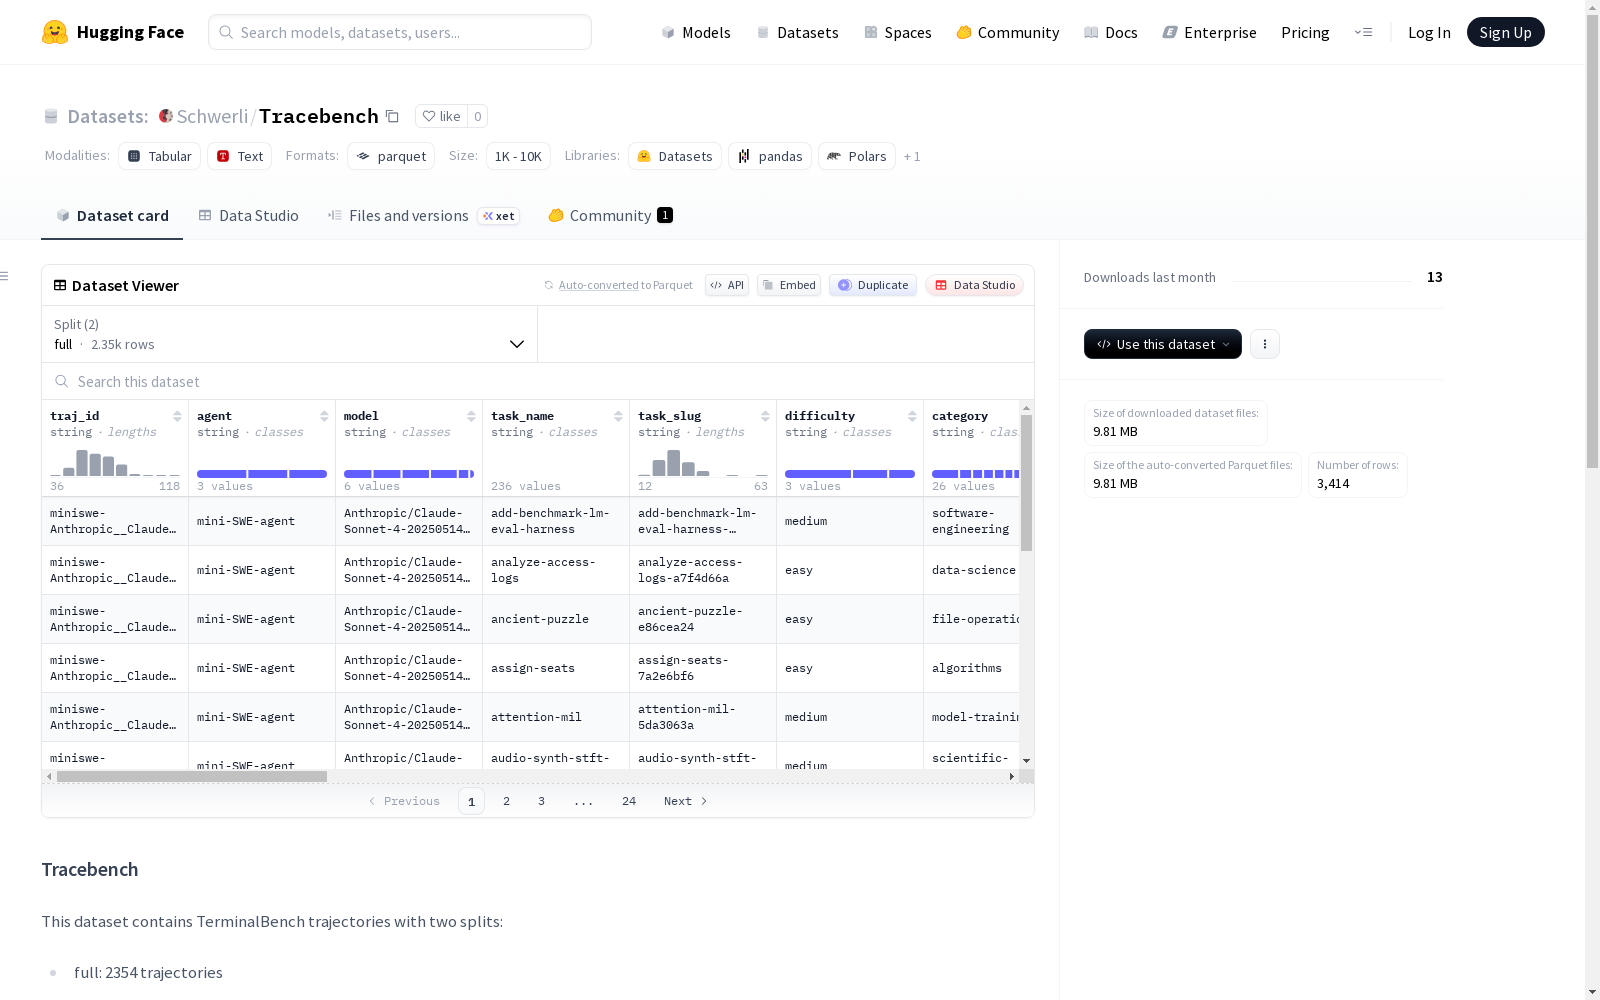
Tracebench
收藏资源简介:
该数据集包含TerminalBench轨迹数据,分为两部分:full(2354条轨迹)和verified(1060条轨迹,经过筛选,step_count>=20,有错误步骤,且错误阶段比例超过阈值)。清单文件包括incorrect_stages信息,记录了错误/无用步骤的分组情况,具体包含stage_id、incorrect_step_ids、unuseful_step_ids和steps的详细信息。数据集还引用了artifact文件,可通过提供的命令进行提取。
This dataset contains TerminalBench trajectory data, split into two subsets: full (2354 trajectories) and verified (1060 filtered trajectories with step_count ≥ 20, containing erroneous steps, and the proportion of erroneous stages exceeding the threshold). The accompanying manifest file includes the incorrect_stages information, which records the grouping of erroneous or unuseful steps, with detailed information including stage_id, incorrect_step_ids, unuseful_step_ids, and steps. The dataset also references artifact files, which can be extracted via the provided commands.
Tracebench 数据集概述
数据集基本信息
- 数据集名称:Tracebench
- 托管地址:https://huggingface.co/datasets/Schwerli/Tracebench
- 数据格式:Parquet / JSONL
数据内容与划分
该数据集包含 TerminalBench 轨迹数据,划分为两个子集:
- full(完整集):包含 2354 条轨迹。
- verified(已验证集):包含 1060 条轨迹。该子集经过筛选,筛选标准为:轨迹步数(step_count)大于等于 20,且包含错误步骤(has incorrect);同时根据内部错误阶段比例阈值进行选择(错误阶段定义为该阶段内错误步骤比例大于等于 50%)。
关键文件
- 数据文件:
bench_manifest.full.parquet/bench_manifest.full.jsonlbench_manifest.verified.parquet/bench_manifest.verified.jsonl
- 引用文件:
- 清单中
artifact_path引用的文件位于:bench_artifacts/full/*.tar.zst
- 清单中
数据结构说明
清单中包含 incorrect_stages 字段,用于按阶段对错误/无用步骤进行分组。
stage_id:[stage_start_idx, stage_end_idx],表示阶段的起始和结束索引(基于0的索引,指向轨迹步骤)。incorrect_step_ids/unuseful_step_ids:此阶段内的步骤ID(基于1)。steps:标记为错误/无用的每一步记录,每条记录包含:action_ref/observation_ref:包含{path, line_start, line_end, content}的对象,指向原始轨迹源文件。
注意:incorrect_error_stage_count 的计算方式与之前相同,仅使用错误步骤并遵循相同的每阶段阈值规则(无用步骤不影响此计数)。
数据加载方法
python from datasets import load_dataset
ds_full = load_dataset("Schwerli/Tracebench", split="full") ds_verified = load_dataset("Schwerli/Tracebench", split="verified")
引用文件提取方法
bash zstd -d -c bench_artifacts/full/<traj_id>.tar.zst | tar -xf -