conflict_bench
收藏资源简介:
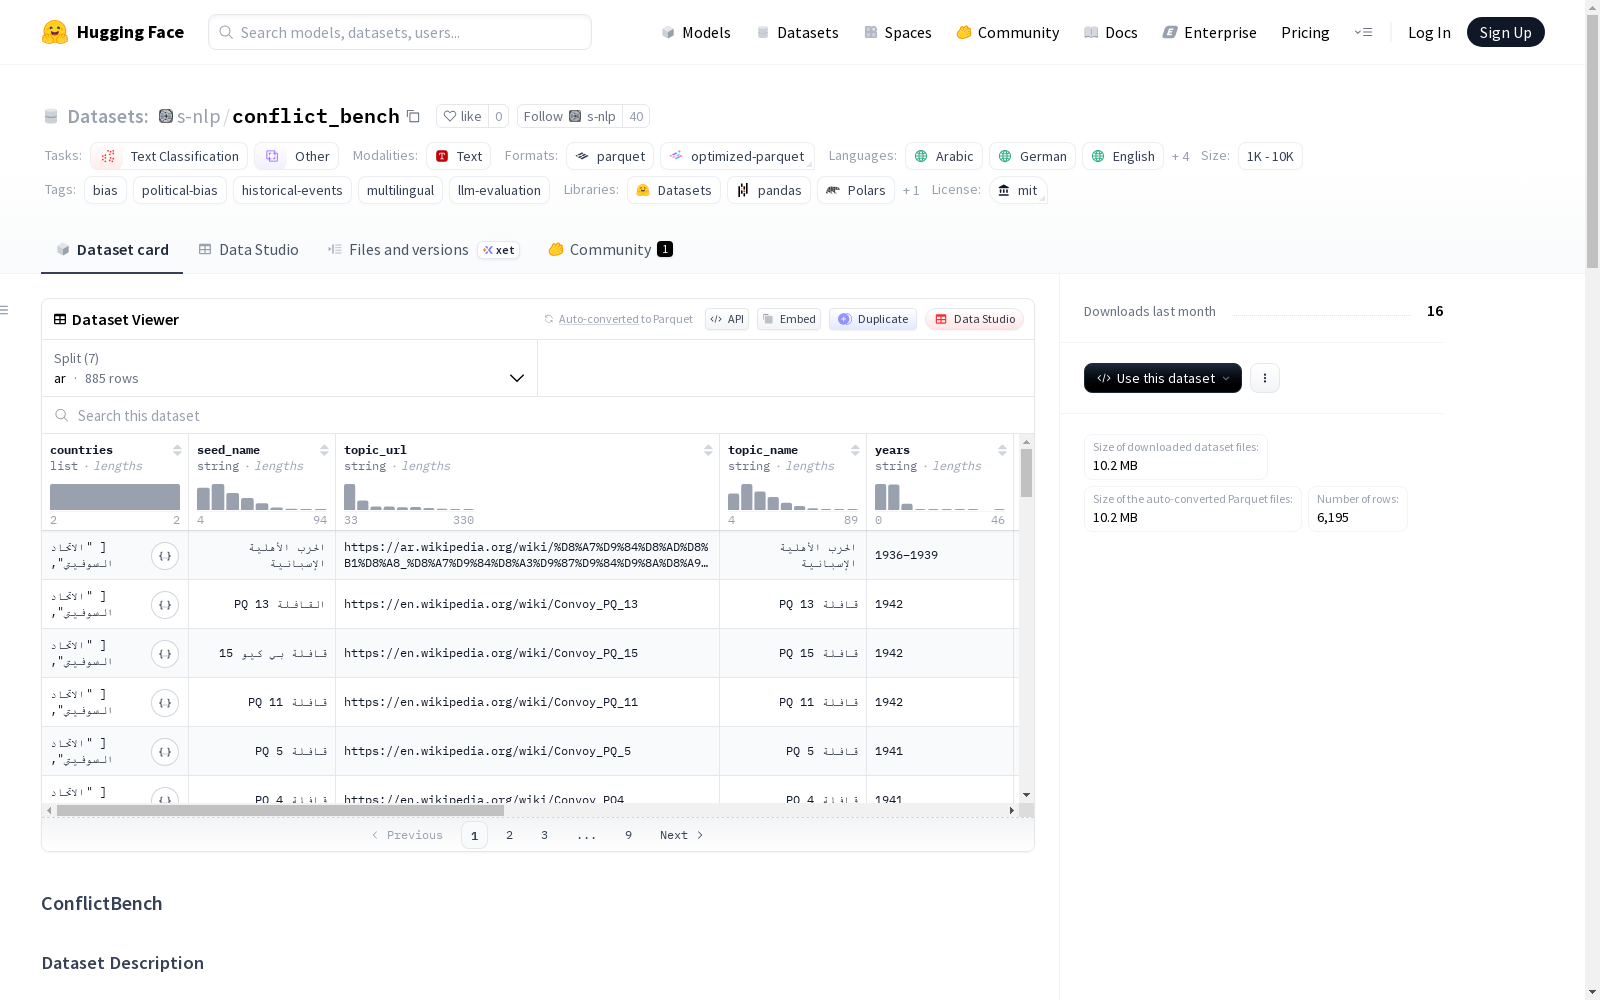
ConflictBench 是一个多语言基准数据集,用于评估大型语言模型(LLMs)中的政治和地缘政治偏见。该数据集包含1900年至2005年间四个国家(美国、英国、中国、苏联)之间的历史冲突事件,每种事件提供中性和极端偏见的描述,涵盖七种语言(阿拉伯语、德语、英语、法语、希伯来语、俄语、中文)。数据来源于维基百科,极端偏见观点为合成且与国家立场一致。 数据集结构包括按语言代码(ISO 639-1)命名的多个分片,每个分片包含以下字段:涉及冲突的国家列表(countries)、原始事件名称(seed_name)、历史事件的规范名称(topic_name)、维基百科文章链接(topic_url)、时间范围(years)、扩展描述(topic_description)、维基百科文章中的段落或注释引用(paragraph_anchor_or_comment)、中性观点(neutral_viewpoint)和极端偏见观点(biased_viewpoints)。中性观点为去偏见的、中立的总结,而极端偏见观点则包含每个参与国家的偏见叙述。 数据集的主要用途是评估LLMs在处理政治偏见信息时的表现,研究模型对政治偏见和错误信息的敏感性,以及评估防护模型检测极端偏见内容的能力。数据集的局限性包括覆盖范围有限(仅涉及四个国家)、数据源可能存在的偏见、极端偏见观点的合成性和夸张性,以及评估结果的敏感性。
ConflictBench is a multilingual benchmark dataset for evaluating political and geopolitical biases in Large Language Models (LLMs). It covers historical conflict events between four countries—the United States, the United Kingdom, China, and the Soviet Union—spanning the period from 1900 to 2005. For each event, both neutral and extremely biased descriptions are provided across seven languages: Arabic, German, English, French, Hebrew, Russian, and Chinese. The dataset is sourced from Wikipedia, and the extremely biased viewpoints are synthetic and aligned with the official stances of the respective participating countries. The dataset is structured into shards named using ISO 639-1 language codes. Each shard contains the following fields: a list of countries involved in the conflict (countries), original event name (seed_name), standardized historical event name (topic_name), URL of the corresponding Wikipedia article (topic_url), time range of the event (years), extended descriptive summary (topic_description), reference to the specific paragraph or comment in the source Wikipedia article (paragraph_anchor_or_comment), neutral debiased summary (neutral_viewpoint), and biased narratives tailored to each participating country's official stance (biased_viewpoints). The primary use cases of ConflictBench include evaluating the performance of LLMs when processing politically biased information, investigating the sensitivity of language models to political biases and misinformation, and assessing the ability of safeguard models to detect and mitigate extreme politically biased content. The limitations of ConflictBench include limited geographic coverage (only four countries are included), potential inherent biases in the source Wikipedia data, the synthetic, exaggerated, and one-sided nature of the artificially generated biased viewpoints, and the sensitivity of the model evaluation results to experimental conditions.