
FIRE
收藏资源简介:
FIRE数据集由北京理工大学、北京通用人工智能研究所等机构创建,包含1.1M条高质量的多轮反馈-细化对话,源自27个源数据集,覆盖视觉问答、图像描述、OCR推理等多个任务。数据集通过GPT-4V模拟学生和教师的对话生成,经过筛选确保对话质量。FIRE数据集的应用领域广泛,旨在通过用户反馈提升视觉语言模型在多任务中的响应精度和效率。
The FIRE dataset was created by institutions including Beijing Institute of Technology and Beijing General Artificial Intelligence Research Institute. It contains 1.1 million high-quality multi-turn feedback-refinement dialogues derived from 27 source datasets, covering multiple tasks such as visual question answering, image captioning and OCR reasoning. The dataset is generated by simulating student-teacher conversations via GPT-4V, and has been screened to ensure dialogue quality. The FIRE dataset has a wide range of application scenarios, aiming to improve the response accuracy and efficiency of visual-language models across diverse tasks through user feedback.
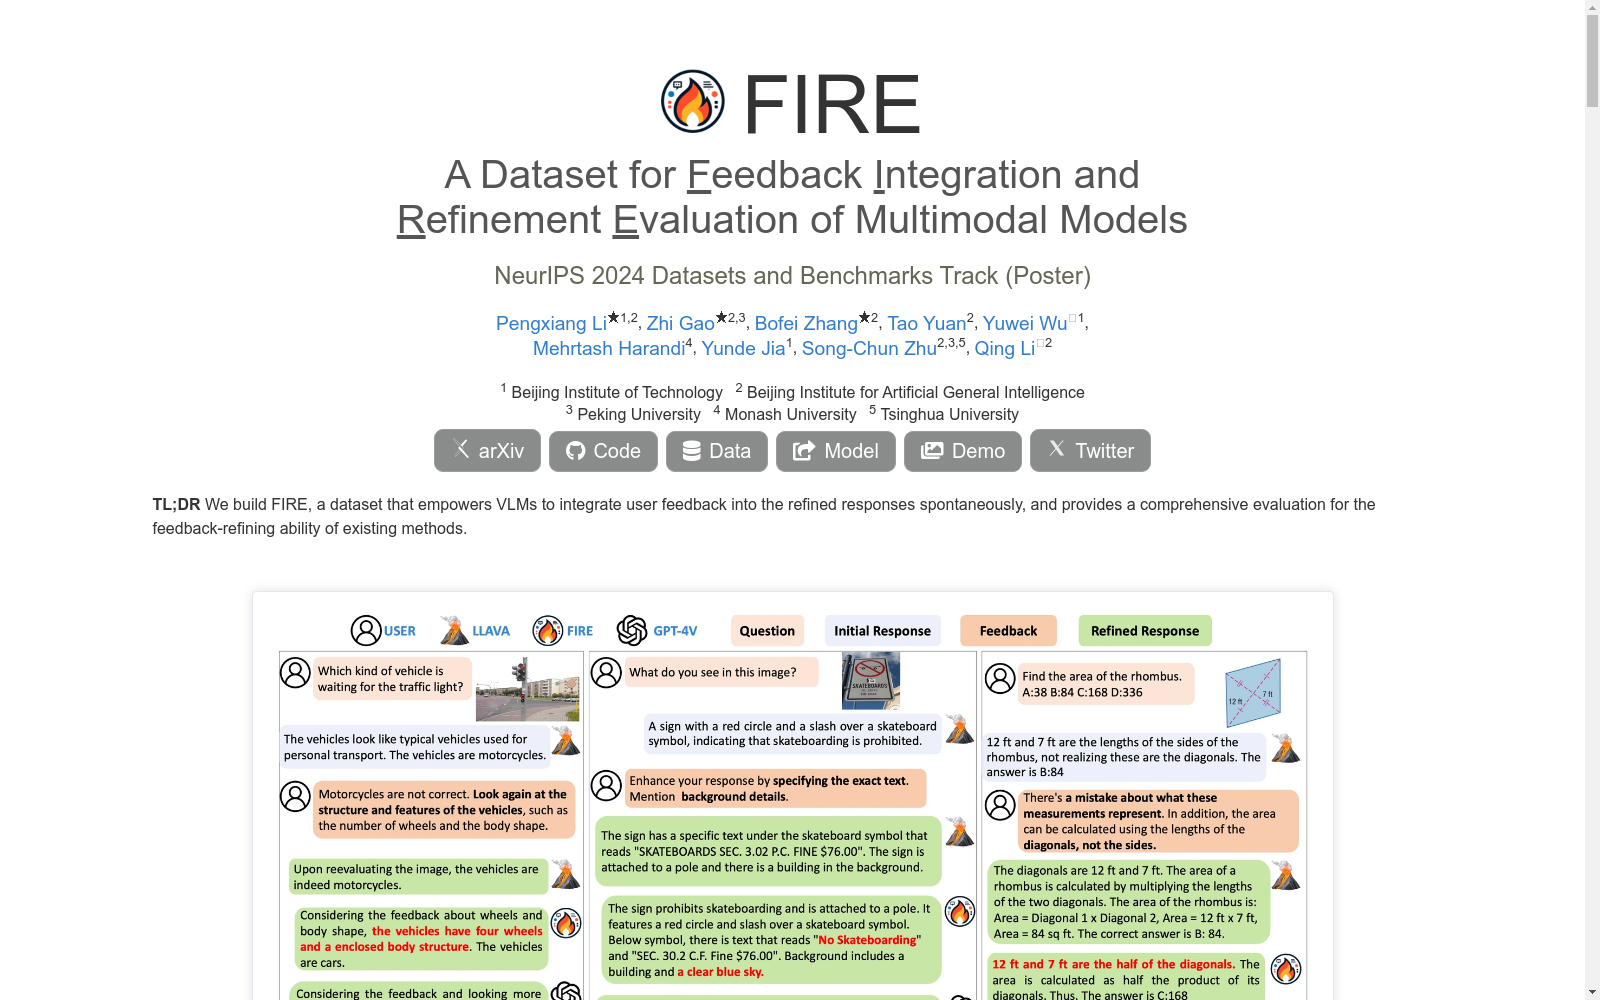
- 1FIRE: A Dataset for Feedback Integration and Refinement Evaluation of Multimodal Models北京理工大学, 北京通用人工智能研究所, 北京大学, 莫纳什大学, 清华大学 · 2024年


