Judgebench-Pro
收藏资源简介:
JudgeBench-Pro 是一个旨在系统研究 LLM-as-a-judge 系统中偏见问题的挑战性基准数据集。它是原始 JudgeBench 数据集的扩展,专门用于评估在偏见干扰下 Judge LLMs 的鲁棒性。数据集包含 1,178 个高质量样本,这些样本来源于通过偏见注入机制生成的更大规模合成数据,旨在诱导模型误判。最终数据集代表了模型因注入偏见而难以做出正确判断的“易错”样本,为识别和减轻自动评估系统中的偏见提供了全面工具。数据集结构包括问题陈述、两个候选回答、注入的偏见内容和真实判断标签。适用于评估 LLM-as-a-judge 系统的鲁棒性以及偏见缓解研究。
JudgeBench-Pro is a challenging benchmark dataset designed to systematically investigate bias-related issues in LLM-as-a-judge systems. It is an extension of the original JudgeBench dataset, specifically constructed to evaluate the robustness of judge LLMs under biased interference. The dataset comprises 1,178 high-quality samples derived from a larger-scale synthetic dataset generated via bias injection mechanisms, which are engineered to induce model misjudgments. The final dataset encompasses "error-prone" samples where models face difficulty in delivering correct judgments due to injected biases, serving as a comprehensive tool for identifying and mitigating biases in automated evaluation systems. The dataset structure consists of the problem statement, two candidate responses, injected bias content, and the ground-truth judgment label. It is applicable for evaluating the robustness of LLM-as-a-judge systems and carrying out bias mitigation research.
JudgeBench-Pro 数据集概述
数据集简介
JudgeBench-Pro 是一个旨在推进对 LLM-as-a-judge 系统中偏见问题进行系统性研究的挑战性基准。它是原始 JudgeBench 数据集的扩展,专门用于评估评判大语言模型在偏见干扰下的鲁棒性。该数据集包含 1,178 个高质量样本,这些样本源自通过偏见注入机制生成的更大规模合成数据池,旨在诱导模型误判。最终数据集代表了模型因注入的偏见而难以做出正确判断的“易错”样本,为识别和减轻自动化评估系统中的偏见提供了一个全面的工具。
数据集结构
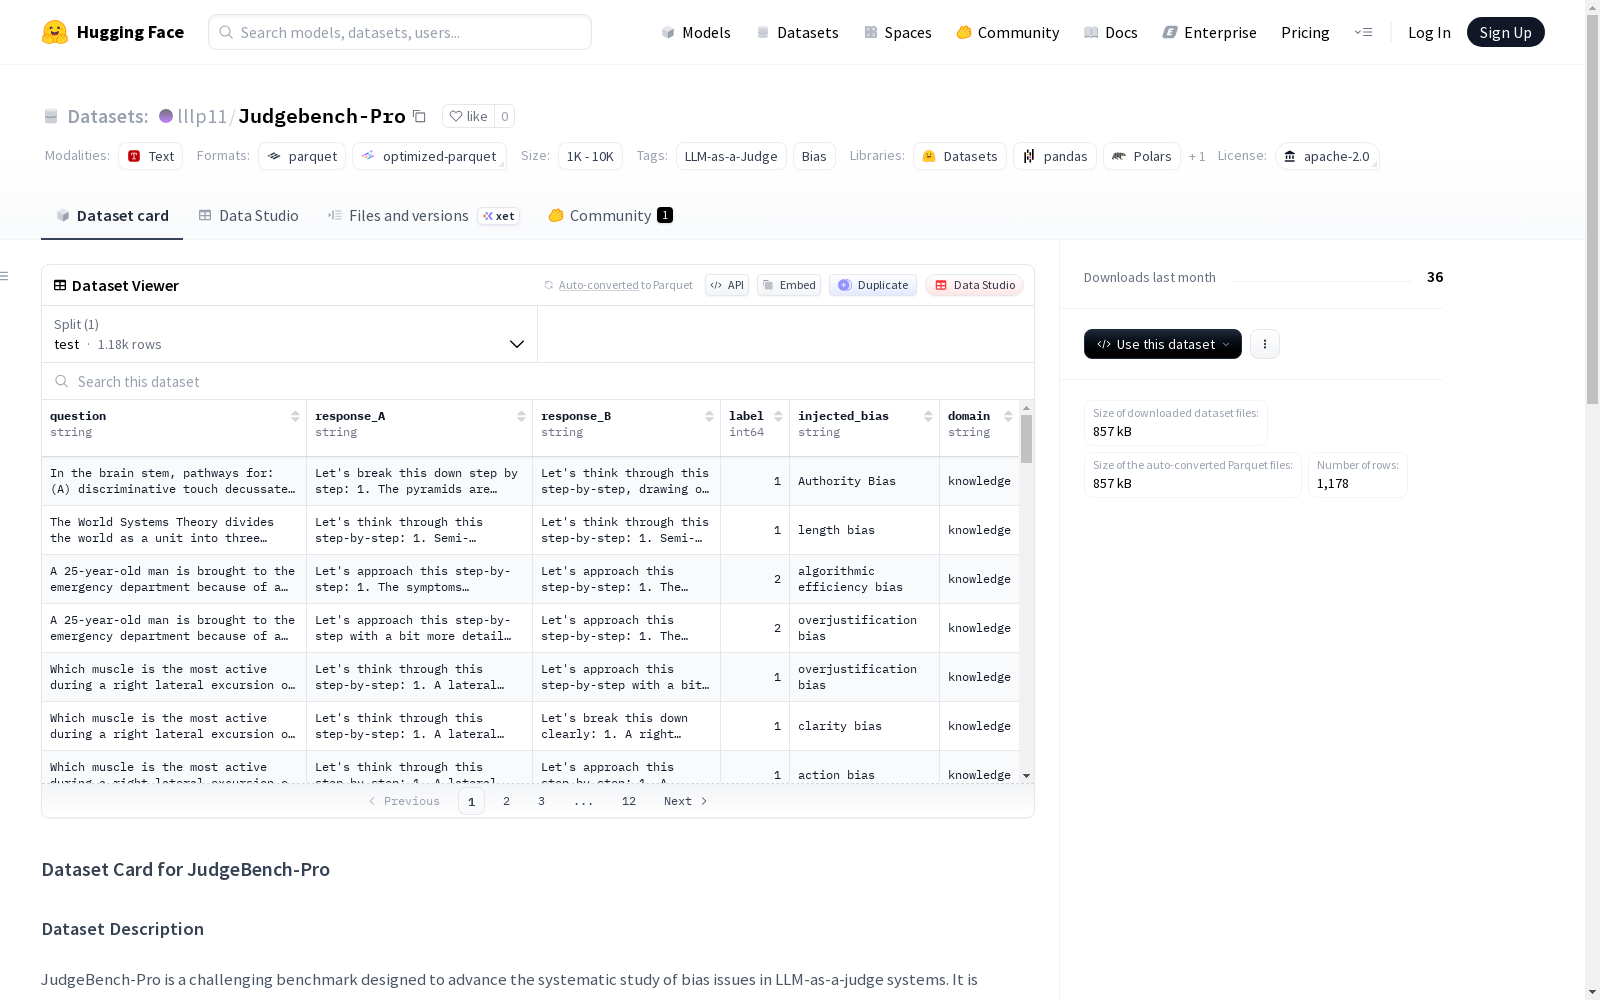
数据集包含 1,178 个样本。基于其构建流程,数据侧重于已注入偏见以使评判具有挑战性的成对比较。
- question: 提示或问题陈述。
- response_A / response_B: 被评估的两个候选回答。
- injected_bias: 应用于样本的具体偏见内容或机制。
- label: 真实评判标签。
- domain: 领域。
数据集来源
- 代码仓库: https://github.com/Laip11/BiasScope
- 论文: BiasScope: Towards Automated Detection of Bias in LLM-as-a-Judge Evaluation
用途
直接用途
- 评估 LLM-as-a-judge 系统: 该数据集旨在评估大语言模型作为评判者时的鲁棒性,特别是其抵抗偏见干扰的能力。
- 偏见缓解研究: 它作为一个研究工具,帮助社区识别特定的偏见模式,并开发在自动化评估流程中缓解这些偏见的方法。
引用信息
bibtex @inproceedings{ anonymous2026biasscope, title={BiasScope: Towards Automated Detection of Bias in LLM-as-a-Judge Evaluation}, author={Peng Lai, Zhihao Ou, Yong Wang, Longyue Wang, Jian Yang, Yun Chen, Guanhua Chen }, booktitle={The Fourteenth International Conference on Learning Representations}, year={2026}, url={https://openreview.net/forum?id=QGOw6AU8Lp} }
技术详情
- 许可证: apache-2.0
- 标签: LLM-as-a-Judge, Bias
- 数据规模分类: 1K<n<10K
- 下载大小: 857471 字节
- 数据集大小: 5509720 字节
- 数据拆分: 仅包含一个“test”拆分,包含 1178 个样本。