fineweb-edu-generalized
收藏资源简介:
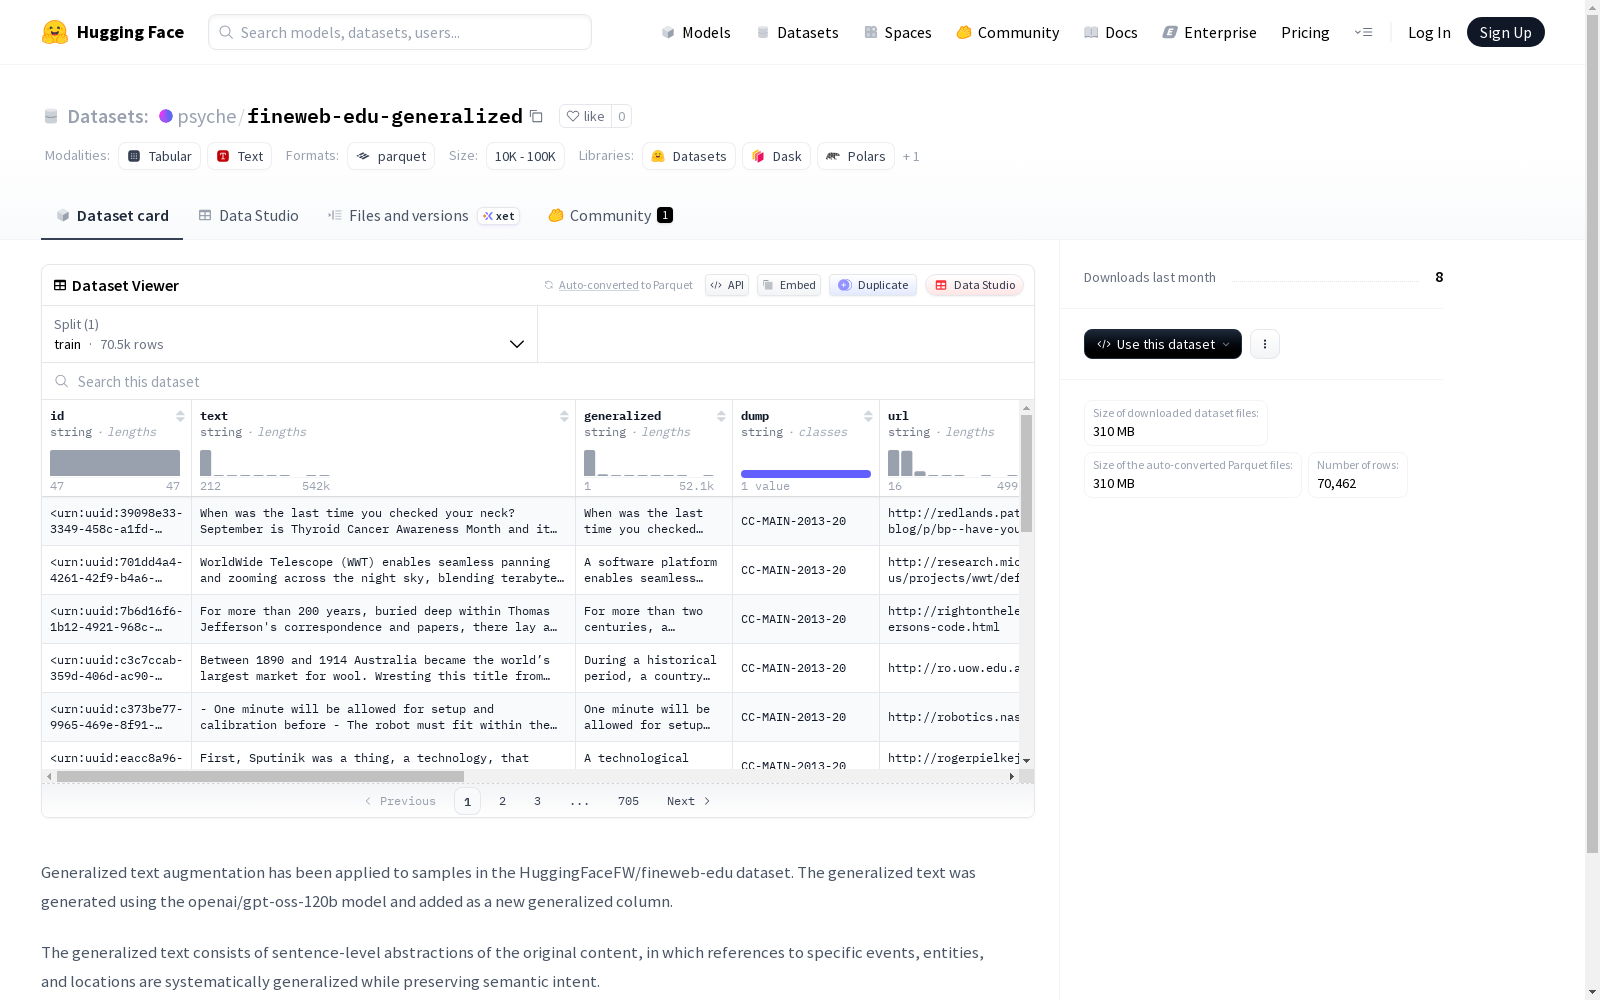
该数据集是对HuggingFaceFW/fineweb-edu数据集进行扩展的版本,通过应用广义文本增强技术,为原始样本添加了新的广义文本列。广义文本由openai/gpt-oss-120b模型生成,包含对原始内容的句子级抽象,其中特定事件、实体和位置的引用被系统性地泛化,同时保留语义意图。数据集包含多个字段,如id(标识符)、text(原始文本)、generalized(广义文本)、dump、url(链接)、file_path(文件路径)、language(语言)、language_score(语言评分)、token_count(标记计数)、score(评分)和int_score(整数评分)。数据集仅包含一个训练集(train)分块,共有42,974个样本,总大小为327,128,581字节。
This dataset is an extended variant of the HuggingFaceFW/fineweb-edu dataset. Generalized text augmentation techniques are applied to add new generalized text columns to the original samples. The generalized text is generated by the openai/gpt-oss-120b model, which conducts sentence-level abstraction on the original content: references to specific events, entities and locations are systematically generalized while the original semantic intent is retained. The dataset includes multiple fields such as id (identifier), text (original text), generalized (generalized text), dump, url, file_path, language, language_score, token_count, score and int_score (integer score). The dataset only contains one training split, with a total of 42,974 samples and an overall size of 327,128,581 bytes.
数据集概述
基本信息
- 数据集名称: fineweb-edu-generalized
- 存储库地址: https://huggingface.co/datasets/psyche/fineweb-edu-generalized
- 数据来源: 基于 HuggingFaceFW/fineweb-edu 数据集进行处理
- 处理方式: 对原始数据集中的样本应用了广义文本增强
数据集内容
数据特征
数据集包含以下字段:
id: 字符串类型,样本标识符text: 字符串类型,原始文本内容generalized: 字符串类型,广义化文本dump: 字符串类型url: 字符串类型,来源网址date: 空值类型file_path: 字符串类型,文件路径language: 字符串类型,语言标识language_score: 浮点数类型,语言识别得分token_count: 整数类型,词元数量score: 浮点数类型,质量得分int_score: 整数类型,整数形式的质量得分
数据规模
- 训练集样本数量: 42,974 条
- 训练集大小: 327,128,581 字节
- 下载大小: 189,394,310 字节
- 数据集总大小: 327,128,581 字节
处理说明
广义文本生成
- 生成模型: 使用 openai/gpt-oss-120b 模型生成广义文本
- 新增字段: 在原始数据集基础上新增了
generalized列 - 处理方式: 对原始内容进行句子级别的抽象化处理
文本处理特点
- 保留语义: 在广义化过程中保持原始内容的语义意图
- 泛化处理: 对具体的事件、实体和位置引用进行系统性的泛化处理
- 抽象级别: 在句子层面进行抽象化处理