anuj0456/arxiv-dataset
收藏资源简介:
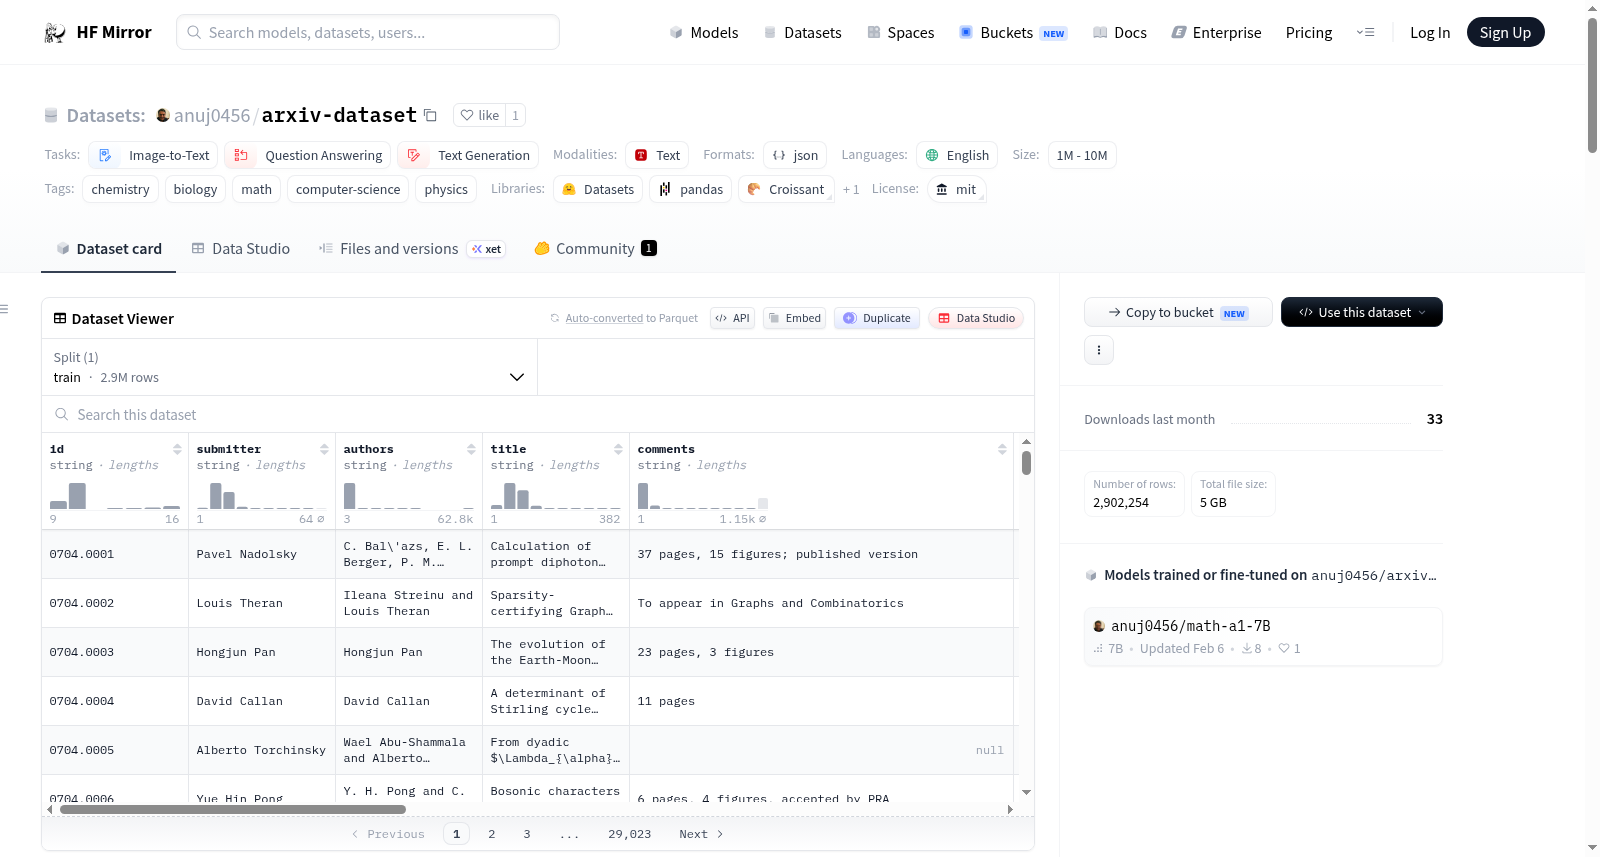
该数据集是arXiv数据集的一个快照,最初发布于Kaggle,后重新上传至Hugging Face Datasets,以便于访问、版本控制和与现代机器学习工作流程的无缝集成。数据集包含arXiv的元数据和论文内容,涵盖化学、生物学、数学、计算机科学和物理学等领域。具体内容包括arXiv ID、标题、作者、主要和次要类别、摘要、提交/更新日期、DOI和期刊引用(如有)。数据集旨在用于LLM训练、检索增强生成(RAG)、引用分析和研究分析等用途。
This dataset is a snapshot of the arXiv dataset, originally published on Kaggle and re-uploaded to Hugging Face Datasets for easier access, versioning, and seamless integration with modern ML workflows. It includes arXiv metadata and paper content, covering fields such as chemistry, biology, math, computer science, and physics. Specific contents include arXiv IDs, titles, authors, primary and secondary categories, abstracts, submission/update dates, and DOI & journal references (when available). The dataset is intended for use in LLM training, retrieval-augmented generation (RAG), citation analysis, and research analytics.