
ShapeTalk
收藏arXiv2025-09-30 收录
数据链接:
官方服务:
资源简介:
该数据集名为ShapeTalk,包含了51,234个样本,这些样本被用于物体参照识别。在三个不同的模型中,共识别出3,990个分类错误的样本。此外,该数据集被用于评估在物体参照识别背景下,为解释这些分类错误的样本而生成的反事实性陈述。具体规模上,总共有51,234个样本,其中选取了1,000个分类错误的样本进行评估。所涉及的任务是物体参照识别。
The dataset named ShapeTalk contains 51,234 samples for object reference recognition. A total of 3,990 misclassified samples were identified across three different models. Moreover, this dataset is utilized to evaluate counterfactual statements generated to explain these misclassified samples within the context of object reference recognition. In terms of specific scale, out of the overall 51,234 samples, 1,000 misclassified samples were selected for evaluation. The task involved is object reference recognition.
搜集汇总
数据集介绍
背景与挑战
背景概述
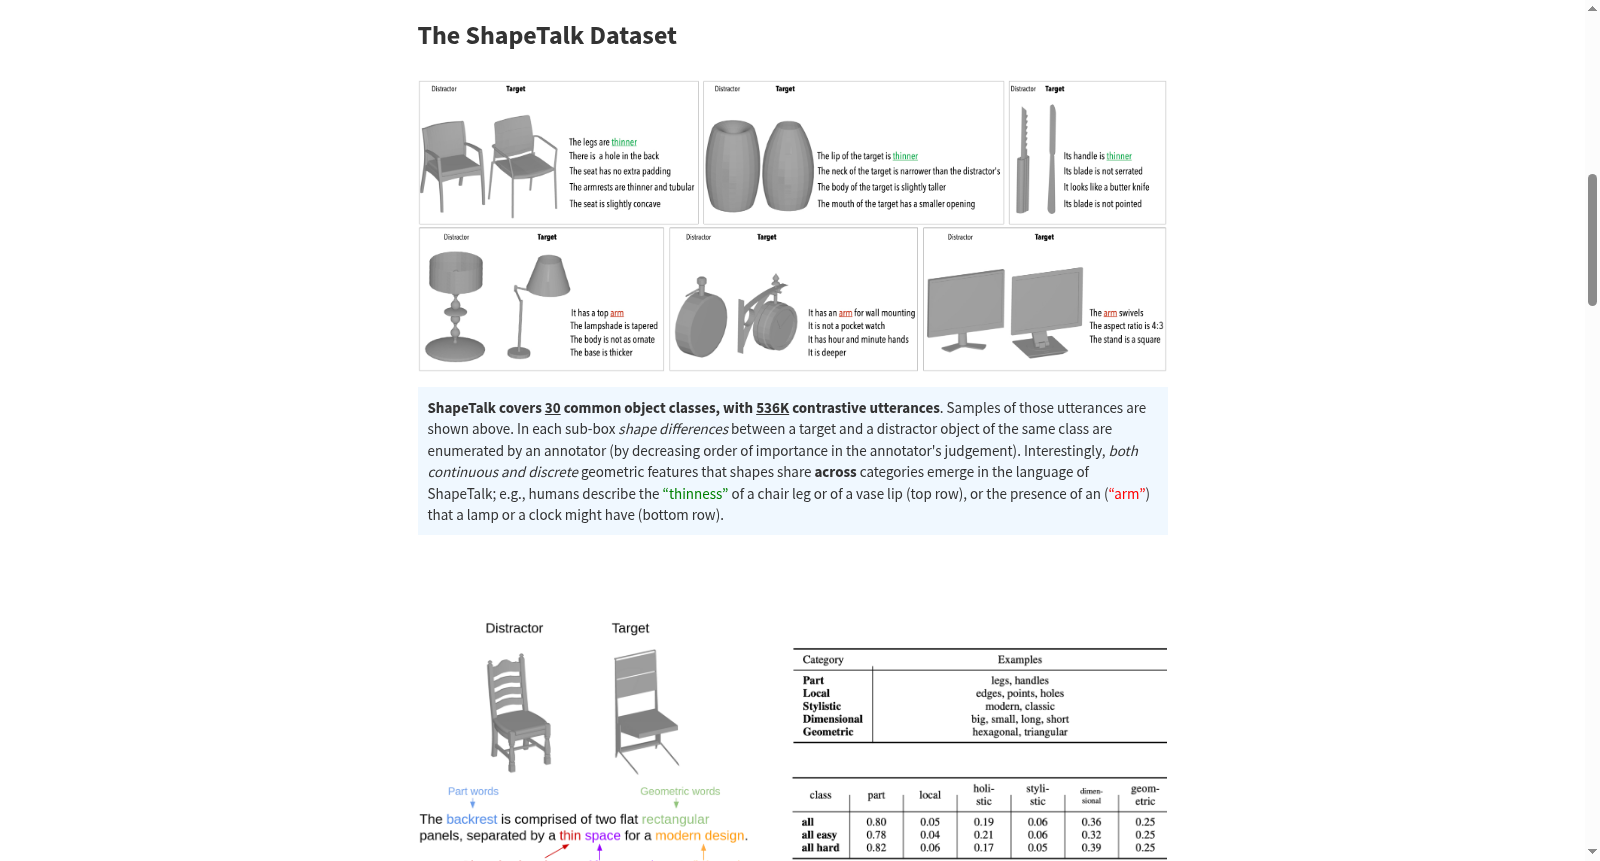
ShapeTalk是一个用于3D形状编辑和变形的语言数据集和框架,包含超过50万个对比性语言描述,覆盖30个常见对象类别。该数据集旨在通过自然语言促进3D模型的几何编辑,支持开放式语言使用和细粒度形状编辑,并提供了ChangeIt3D框架和量化评估方法。
以上内容由遇见数据集搜集并总结生成


