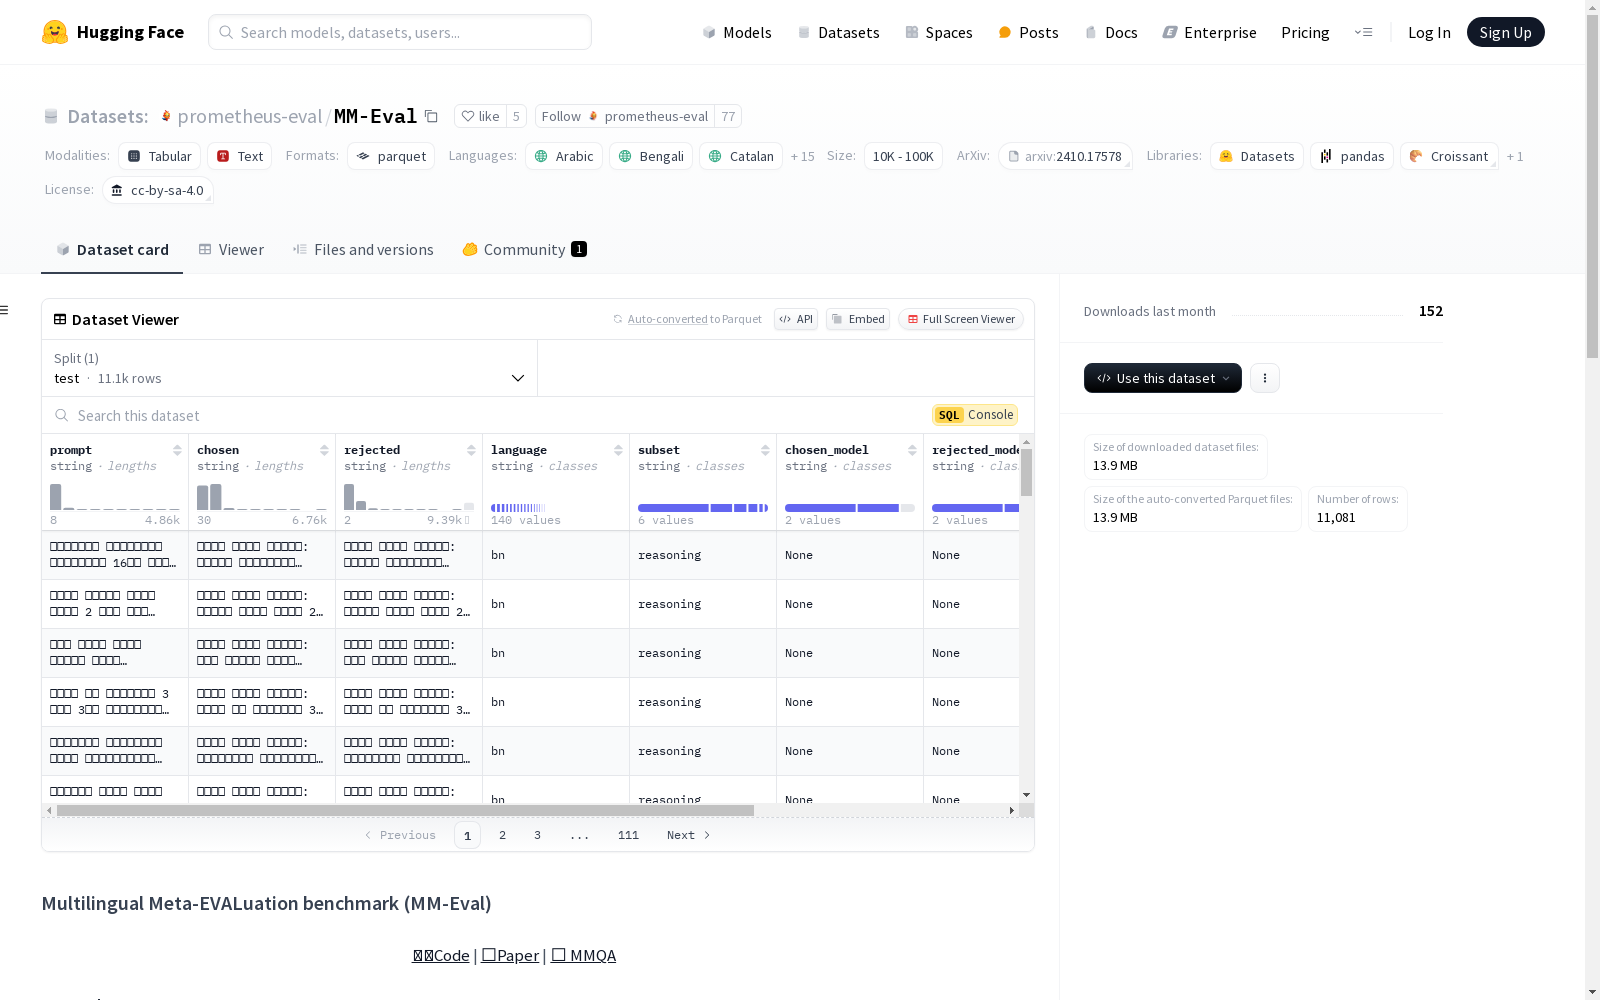
MM-Eval
收藏资源简介:
MM-Eval是一个多语言元评估基准,包含五个核心子集:聊天、推理、安全、语言幻觉和语言学,涵盖18种语言,并有一个语言资源子集涵盖122种语言,用于更广泛的分析语言影响。数据集设计时减少了翻译样本的包含,以避免翻译错误改变现有偏好,仅在安全子集中包含翻译样本。此外,数据集还包含一个语言学子集,用于评估模型对各种语言语言特征的理解能力,并在语言幻觉子集中加入了手工制作的文化相关提示。
MM-Eval is a multilingual meta-evaluation benchmark consisting of five core subsets: Chat, Reasoning, Safety, Language Hallucination, and Linguistics. It covers 18 languages, and additionally includes a language resources subset encompassing 122 languages for broader analysis of language-related impacts. To avoid translation errors altering pre-existing preferences, the dataset minimizes the inclusion of translated samples, with translated samples only included in the Safety subset. Furthermore, the Linguistics subset is designed to evaluate models' understanding of linguistic features across various languages, and handcrafted culture-relevant prompts are added to the Language Hallucination subset.
Multilingual Meta-EVALuation benchmark (MM-Eval)
数据集概述
- 名称: MM-Eval
- 描述: 一个多语言元评估基准,包含五个核心子集——Chat、Reasoning、Safety、Language Hallucination 和 Linguistics,涵盖18种语言,以及一个涵盖122种语言的Language Resource子集,用于更广泛的分析语言效应。
数据集特征
- 特征:
prompt: 字符串chosen: 字符串rejected: 字符串language: 字符串subset: 字符串chosen_model: 字符串rejected_model: 字符串id: 整数__index_level_0__: 整数
数据集分割
- 分割:
test: 包含11081个样本,大小为30802291字节
数据集大小
- 下载大小: 13929039字节
- 数据集大小: 30802291字节
配置
- 配置名称: default
- 数据文件:
test: 路径为data/test-*
支持的语言
- 阿拉伯语, 孟加拉语, 加泰罗尼亚语, 德语, 英语, 西班牙语, 巴斯克语, 法语, 加利西亚语, 意大利语, 日语, 韩语, 俄语, 斯瓦希里语, 泰卢固语, 泰语, 越南语, 中文
许可证
- 许可证: CC BY-SA 4.0
引用
@article{son2024mm, title={MM-Eval: A Multilingual Meta-Evaluation Benchmark for LLM-as-a-Judge and Reward Models}, author={Son, Guijin and Yoon, Dongkeun and Suk, Juyoung and Aula-Blasco, Javier and Aslan, Mano and Kim, Vu Trong and Islam, Shayekh Bin and Prats-Cristi{`a}, Jaume and Tormo-Ba{~n}uelos, Luc{\i}a and Kim, Seungone}, journal={arXiv preprint arXiv:2410.17578}, year={2024} }