P3-Latvian-QuickMT
收藏资源简介:
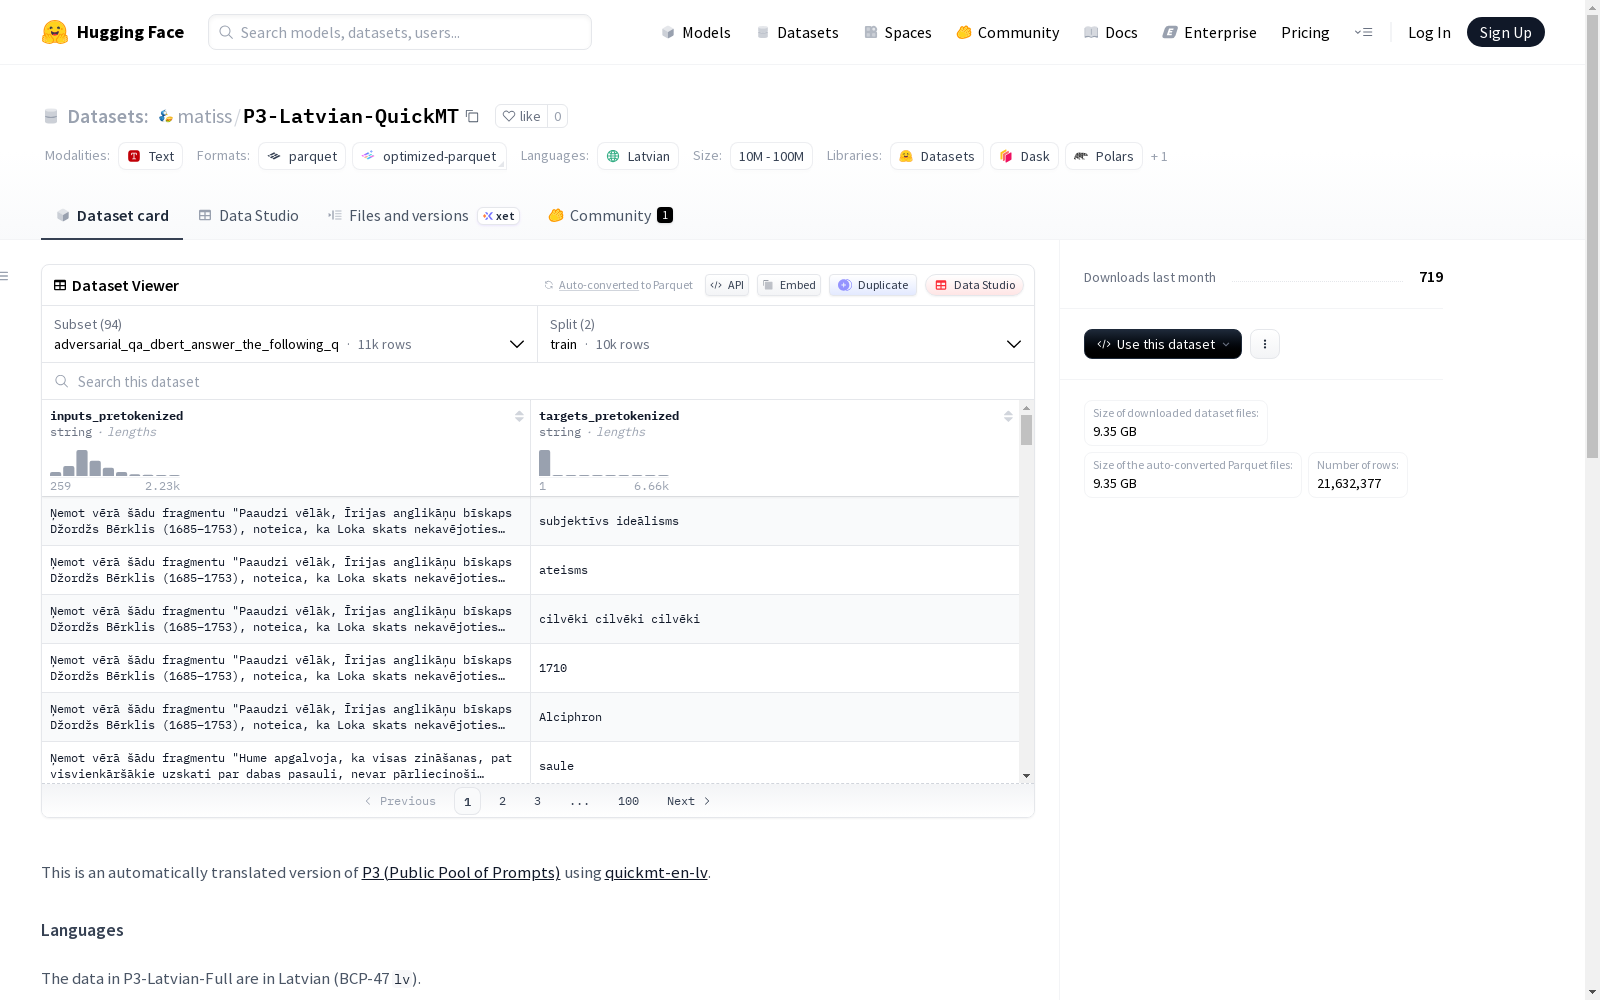
该数据集包含多个配置,涵盖问答、文本分类和情感分析等多种任务。每个配置都包含预处理的输入和目标文本('inputs_pretokenized'和'targets_pretokenized'),部分配置还包含多项选择题的选项('answer_choices')。数据集通常分为训练集、验证集和测试集,具体到每个分区的字节大小和样本数量都有详细记录。例如,某些问答任务的训练集包含10,000个样本,验证集包含1,000个样本。这些数据集适用于自然语言处理任务,如模型训练和评估。
This dataset comprises multiple configurations covering a variety of natural language processing tasks including question answering, text classification, and sentiment analysis. Each configuration contains preprocessed input and target text under the keys 'inputs_pretokenized' and 'targets_pretokenized'; some configurations also include multiple-choice question answer options under the key 'answer_choices'. The dataset is typically divided into training, validation, and test splits, with detailed records of the byte size and sample count for each partition. For example, the training split of certain question answering tasks contains 10,000 samples, while the validation split contains 1,000 samples. This dataset is suitable for natural language processing tasks such as model training and evaluation.