tblard/allocine
收藏资源简介:
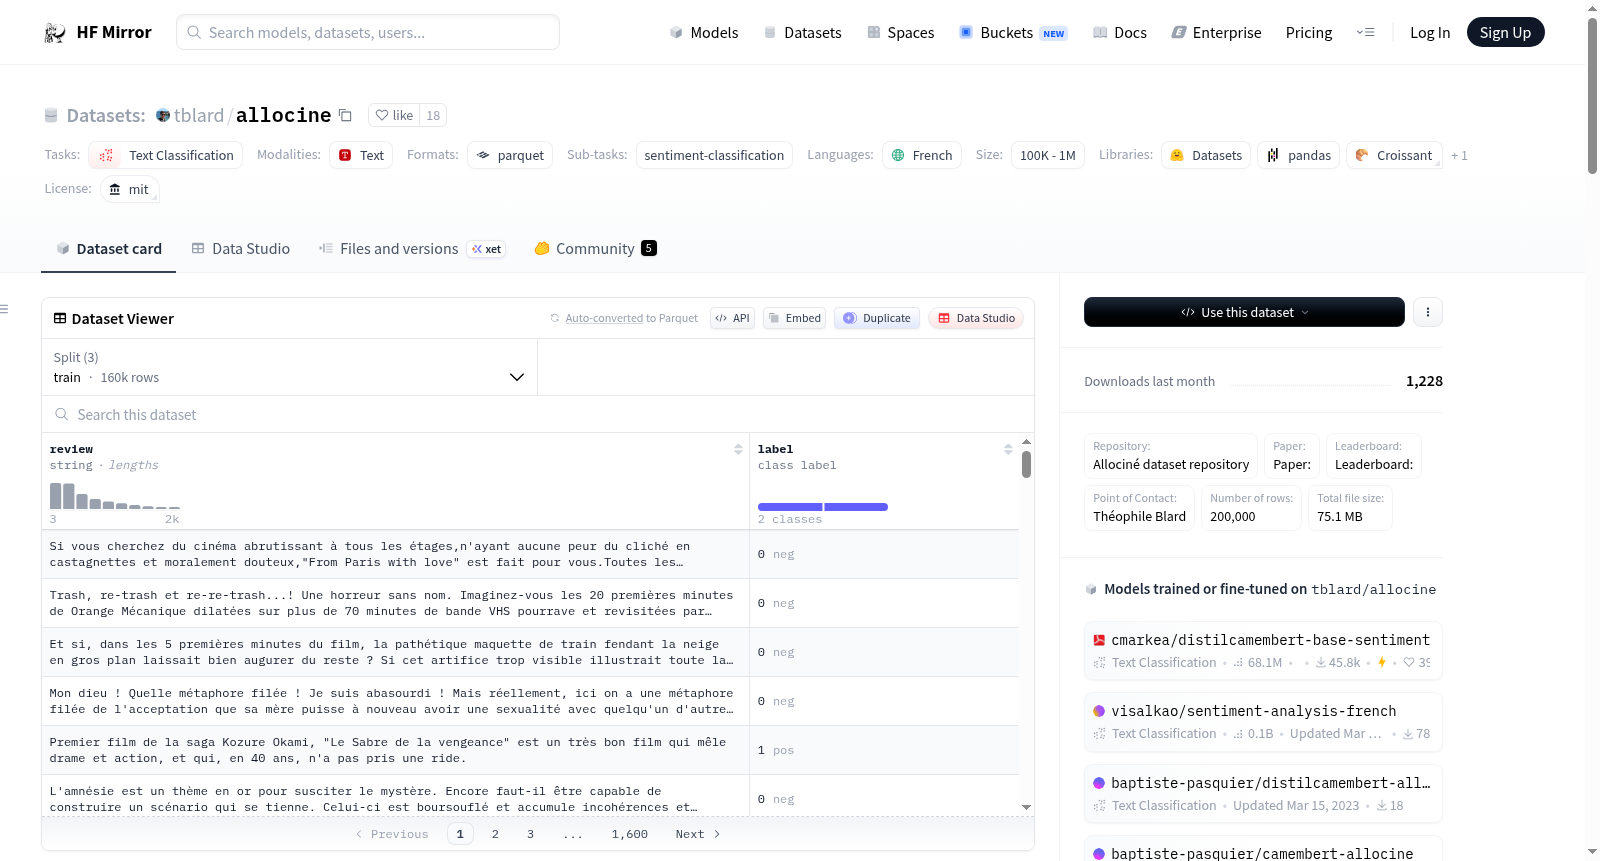
Allociné数据集是一个用于情感分析的法语数据集,包含2006年至2020年间由Allociné.fr社区成员撰写的电影评论。数据集包含100,000条正面评论和100,000条负面评论,分为训练集(160,000条)、验证集(20,000条)和测试集(20,000条)。数据集的主要任务是文本分类和情感分类,旨在训练模型进行情感分析。数据集的结构包括两个字段:review(评论文本)和label(标签,0表示负面,1表示正面)。数据集的创建是为了支持大规模的法语情感分析,并且与一个BERT模型一起发布。
The Allociné dataset is a French-language dataset for sentiment analysis, containing movie reviews written by community members of Allociné.fr between 2006 and 2020. It includes 100,000 positive reviews and 100,000 negative reviews, split into training set (160,000 samples), validation set (20,000 samples) and test set (20,000 samples). The core tasks of this dataset are text classification and sentiment classification, aimed at training models for sentiment analysis. The dataset structure contains two fields: "review" (the review text) and "label" (the label, where 0 indicates negative sentiment and 1 indicates positive sentiment). This dataset was developed to support large-scale French sentiment analysis, and was released alongside a BERT model.
数据集概述
名称: Allociné
语言: 法语 (fr)
许可证: MIT
多语言性: 单语种
大小: 100K<n<1M
源数据: 原始数据
任务类别: 文本分类
任务ID: 情感分类
数据集结构
-
特征:
- review: 字符串类型,包含评论文本。
- label: 分类标签,整数类型,0表示负面,1表示正面。
-
数据分割:
- 训练集: 160,000条记录,字节数91,330,632。
- 验证集: 20,000条记录,字节数11,546,242。
- 测试集: 20,000条记录,字节数11,547,689。
数据集创建
- 数据收集: 使用film page urls和allocine_scraper.py工具收集。
- 数据标注: 无额外标注。
- 数据来源: 来自Allociné.fr网站的在线社区。
使用数据注意事项
- 社会影响: 情感分类模型需具备高级语言理解能力,可能影响决策过程。
- 偏见讨论: 需进一步分析以确定内容审核的有效性。
- 其他限制: 未详细调查,但可能存在如否定、状语修饰和评论者语用等难以准确标记的语言现象。