shiv213/Automatic-Sarcasm-Detection-Twitter
收藏资源简介:
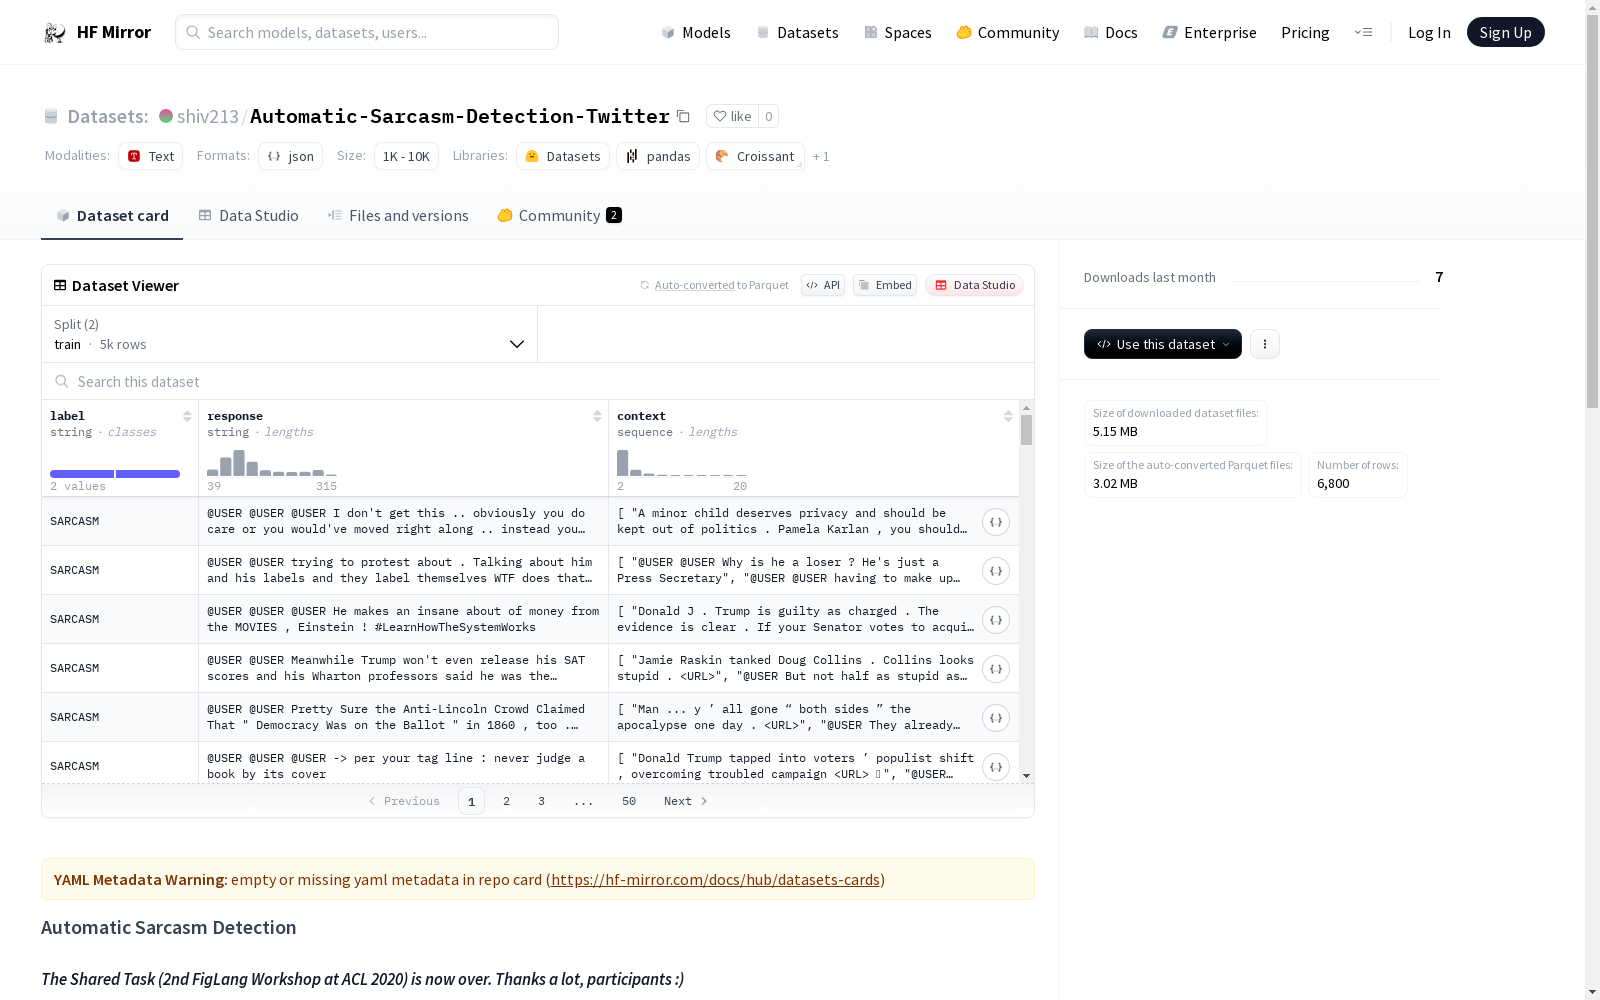
该数据集用于自动讽刺检测任务,包含来自Twitter和Reddit的训练和测试数据,格式为jsonlines。每个数据项包括标签(讽刺或非讽刺)、样本ID(仅在测试数据中)、讽刺响应及其对话上下文。上下文是一个有序的对话列表,帮助理解讽刺响应的背景。数据集的大小统计显示,Reddit的训练和测试样本分别为4400和1800,Twitter的训练和测试样本分别为5000和1800。数据集主要来源于社交媒体平台,可能包含争议性和非正式语言。
This dataset is intended for the automatic sarcasm detection task. It comprises training and test datasets sourced from Twitter and Reddit, formatted as jsonlines. Each data entry includes a label (sarcastic or non-sarcastic), a sample ID (only present in the test datasets), the sarcastic response, and its conversational context. The context is an ordered list of dialogues that helps clarify the background of the sarcastic response. Statistical data of the dataset shows that Reddit has 4400 training samples and 1800 test samples, while Twitter has 5000 training samples and 1800 test samples. The dataset is primarily sourced from social media platforms and may contain controversial and informal language.
数据集概述
数据集名称
Automatic Sarcasm Detection
数据集内容
- 数据格式:JSON Lines
- 数据结构:
- label:标签,值为
SARCASM或NOT_SARCASM - id:样本的唯一标识符,仅在测试数据中提供
- response:讽刺性回复,可能为Twitter推文或Reddit帖子
- context:回复的对话上下文,为一个有序的对话列表
- label:标签,值为
数据集统计
| Train | Test | |
|---|---|---|
| 4400 | 1800 | |
| 5000 | 1800 |
数据集用途
用于讽刺检测任务,训练和测试数据分别提供。
数据集特点
- 训练数据来源于流行的社交媒体平台,包含大量关于争议性、政治和社会话题的内容。
- 数据经过预处理和轻度编辑,但仍包含用户的争议性观点和非正式语言。