mrcr
收藏资源简介:
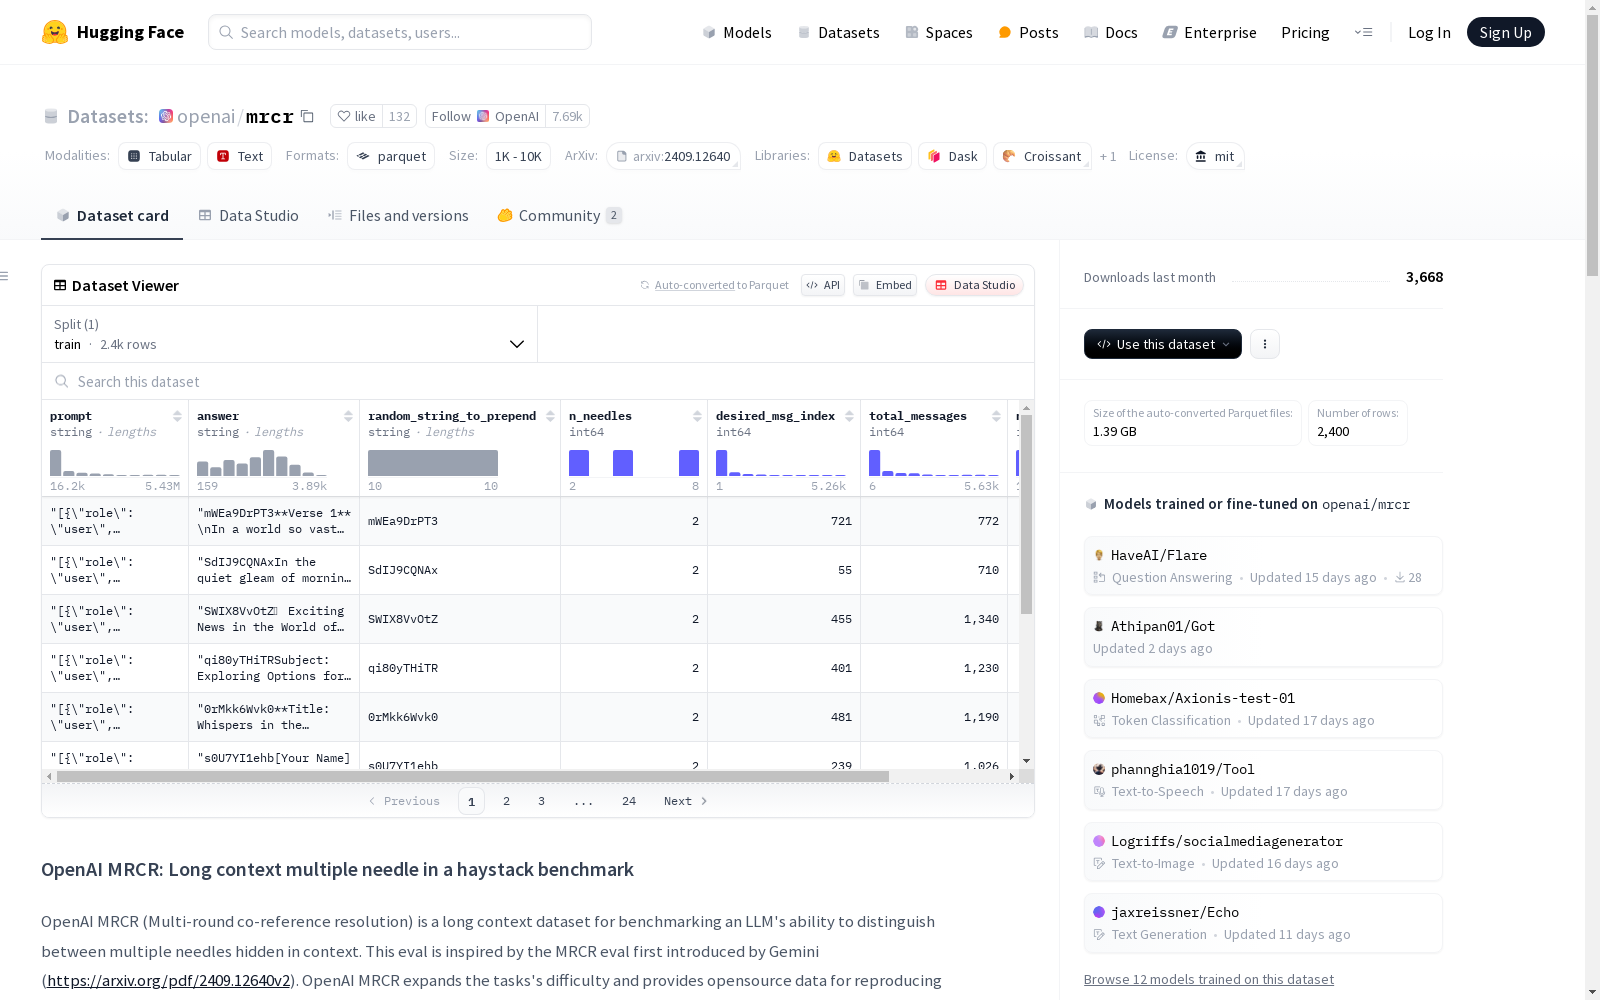
OpenAI MRCR(多轮共指消解)是一个长上下文数据集,用于评估大型语言模型在长上下文中区分隐藏的多个相同问题的能力。数据集中包含用户和模型之间的多轮对话,对话中隐藏了2、4或8次相同的问题,模型需要返回指定次序的答案。数据集难度较高,因为问题和干扰信息具有相同的分布,模型需要区分问题的顺序。数据集包含了438个不同的实体和10种不同的写作格式。
OpenAI MRCR (Multi-Round Coreference Resolution) is a long-context dataset developed to evaluate the capability of large language models (LLMs) in distinguishing multiple identical hidden questions within extended contexts. The dataset comprises multi-turn dialogues between users and models, with 2, 4, or 8 identical questions embedded as hidden content. The model is tasked with returning the answer corresponding to the specified order of these questions. This dataset poses a considerable challenge, as the target questions and distractor information share the same statistical distribution, requiring the model to accurately differentiate the sequential order of the questions. The dataset includes 438 distinct entities and 10 different writing formats.