
MM-EVAL
收藏资源简介:
MM-EVAL是由延世大学和韩国科学技术院等机构创建的多语言元评估基准,涵盖18种语言,包含六个子集,旨在评估大型语言模型在非英语环境下的评估能力。数据集包含4981条数据,涵盖聊天、推理、安全、语言幻觉和语言学等多个领域。创建过程中,数据集通过多种语言的本地化处理和任务设计,确保了在低资源语言中的有效性。该数据集主要应用于评估和改进大型语言模型在多语言环境中的表现,解决其在非英语环境下的评估偏差问题。
MM-EVAL is a multilingual meta-evaluation benchmark developed by Yonsei University, Korea Advanced Institute of Science and Technology (KAIST) and other institutions. It covers 18 languages and comprises six subsets, with the goal of assessing the capabilities of large language models (LLMs) in non-English contexts. The dataset contains 4,981 instances spanning multiple domains such as chat, reasoning, security, linguistic hallucinations and linguistics. During its creation, the dataset underwent localization processing and task design across various languages to guarantee its effectiveness in low-resource languages. This benchmark is mainly applied to evaluate and enhance the performance of large language models in multilingual environments, addressing the issue of evaluation bias in non-English environments.
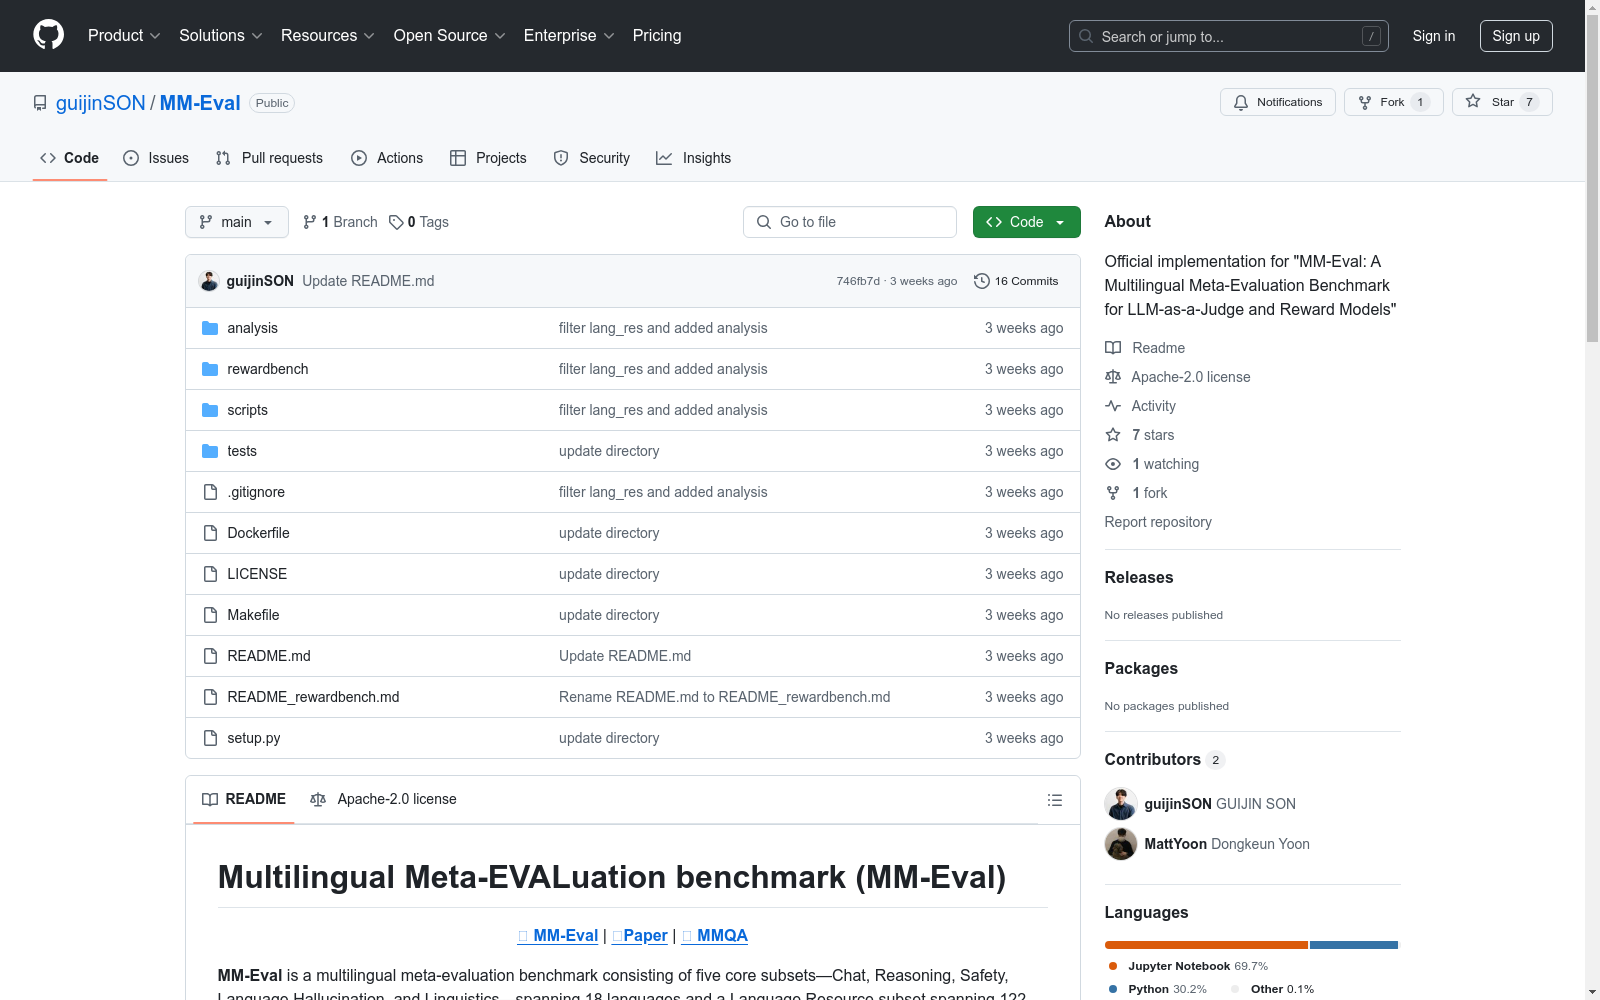
Multilingual Meta-EVALuation benchmark (MM-Eval)
概述
MM-Eval 是一个多语言元评估基准,包含五个核心子集:Chat、Reasoning、Safety、Language Hallucination 和 Linguistics,涵盖 18 种语言。此外,还有一个 Language Resource 子集,涵盖 122 种语言,用于更广泛的分析语言效应。
设计选择
- 最小化翻译样本的包含,以避免翻译错误导致的偏好变化。
- 增加语言和文化相关实例的比例。
- 仅在 Safety 子集中包含翻译样本。
- 增加 Linguistics 子集,评估模型对各种语言语言特征的理解能力。
- 在 Language Hallucination 子集中包含手工制作的文化相关提示。
使用方法
安装
python git clone https://github.com/guijinSON/MM-Eval cd MM-Eval cd reward-bench pip install -e .
评估奖励模型
bash python scripts/run_rm.py --model=prometheus-eval/MM-Mistral-7B-RM --custom_dataset_path prometheus-eval/MM-Eval
-
确保模型适合 GPU,否则减少批量大小: bash --batch_size 1
-
某些模型可能需要添加以下标志: bash --trust_remote_code
评估专有模型
-
添加 OpenAI API 密钥: bash export OPENAI_API_KEY="{your-api-key}"
-
运行评估: bash python scripts/run_generative.py --model=gpt-4o-mini-2024-07-18 --custom_dataset_path prometheus-eval/MM-Eval
评估 Prometheus2.0 和 Self-Taught Evaluator
- 使用原始实现,而非 Reward-Bench 代码库。
- 实验复现教程将很快添加。
引用
[TBD]
- 1MM-Eval: A Multilingual Meta-Evaluation Benchmark for LLM-as-a-Judge and Reward Models延世大学1 韩国科学技术院2 OneLineAI3 巴塞罗那超级计算中心4 Artful Media5 孟加拉工程技术大学6 卡内基梅隆大学7 · 2024年


