x_dataset_0612232
收藏资源简介:
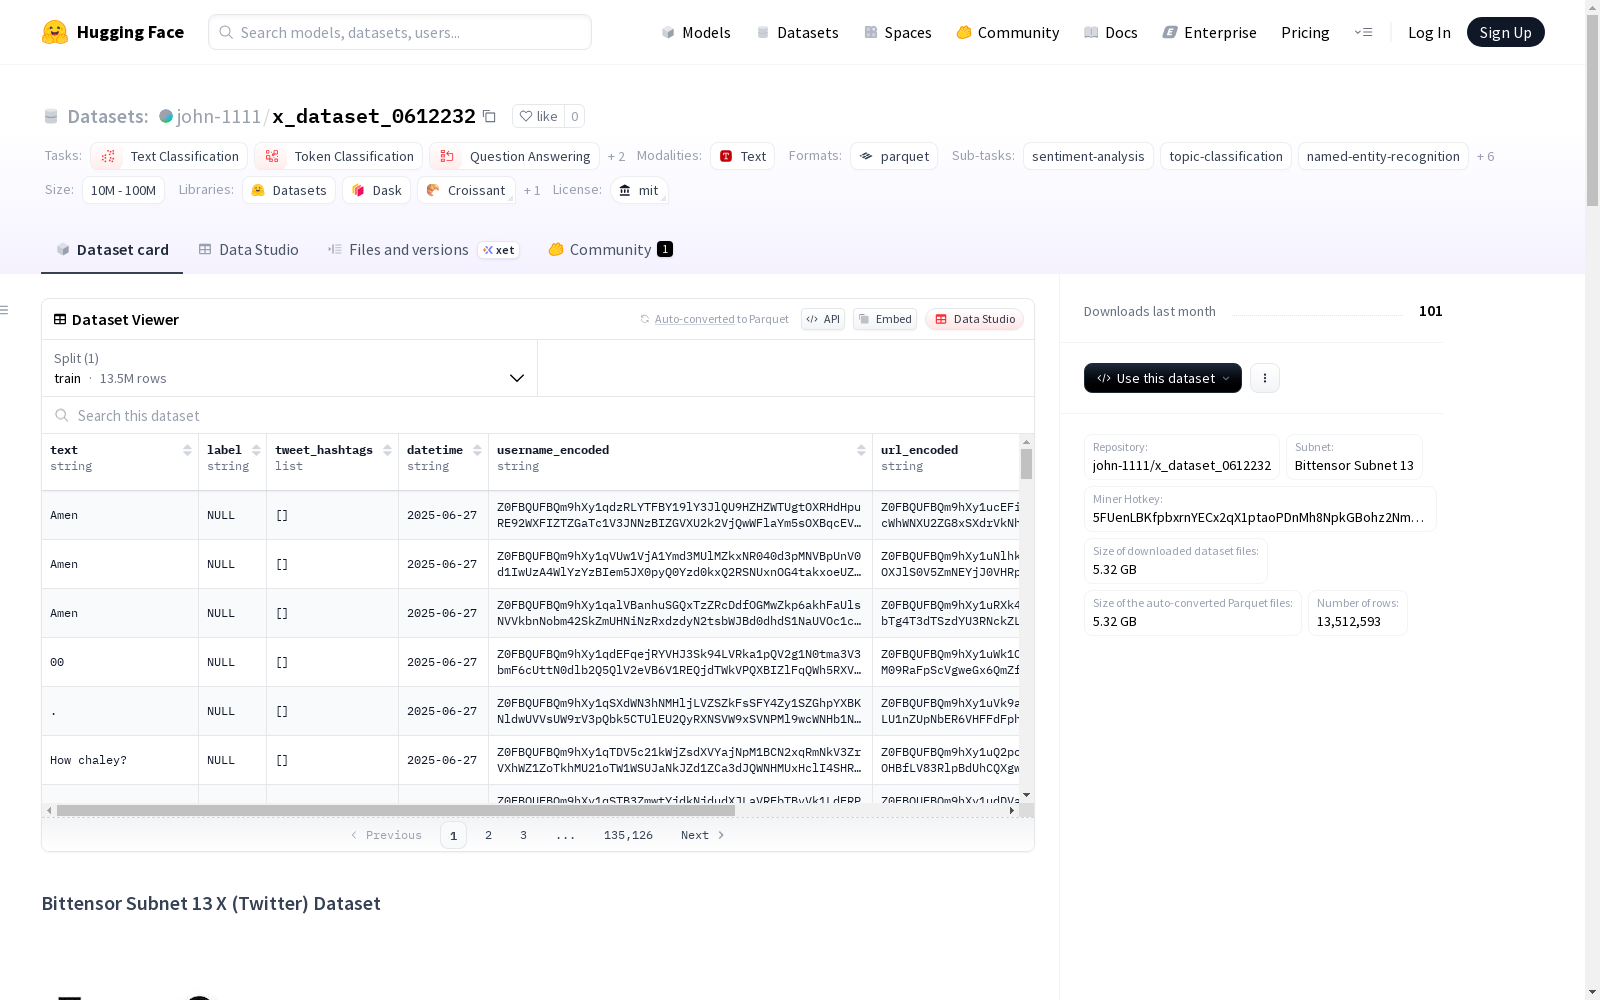
Bittensor Subnet 13 X(Twitter)数据集是Bittensor Subnet 13去中心化网络的一部分,包含了来自X(前Twitter)的预处理推文数据。这些数据由网络矿工持续更新,为各种分析和机器学习任务提供实时推文流。数据集支持多种自然语言处理任务,包括情感分析、趋势检测、内容分析和用户行为建模等。数据集主要是英文,但也可能是多语言的。每个数据实例代表一条推文,包括推文内容、情感或主题标签、话题标签列表、发布日期、编码后的用户名和URL等字段。数据集不断更新,用户需根据需求和时间戳自行创建数据划分。
The Bittensor Subnet 13 X (Twitter) Dataset is part of the Bittensor Subnet 13 decentralized network, which contains preprocessed tweet data sourced from X (formerly Twitter). The data is continuously updated by network miners, providing real-time tweet streams for various analytics and machine learning tasks. The dataset supports multiple natural language processing tasks including sentiment analysis, trend detection, content analysis, user behavior modeling and more. While primarily in English, the dataset may also include multilingual content. Each data instance represents a single tweet and includes fields such as tweet content, sentiment or topic tags, a list of hashtags, publication date, encoded usernames, URLs and other relevant information. The dataset is updated on an ongoing basis, and users need to create their own data splits based on their specific requirements and timestamps.