
Spatial-MLLM-120k
收藏资源简介:
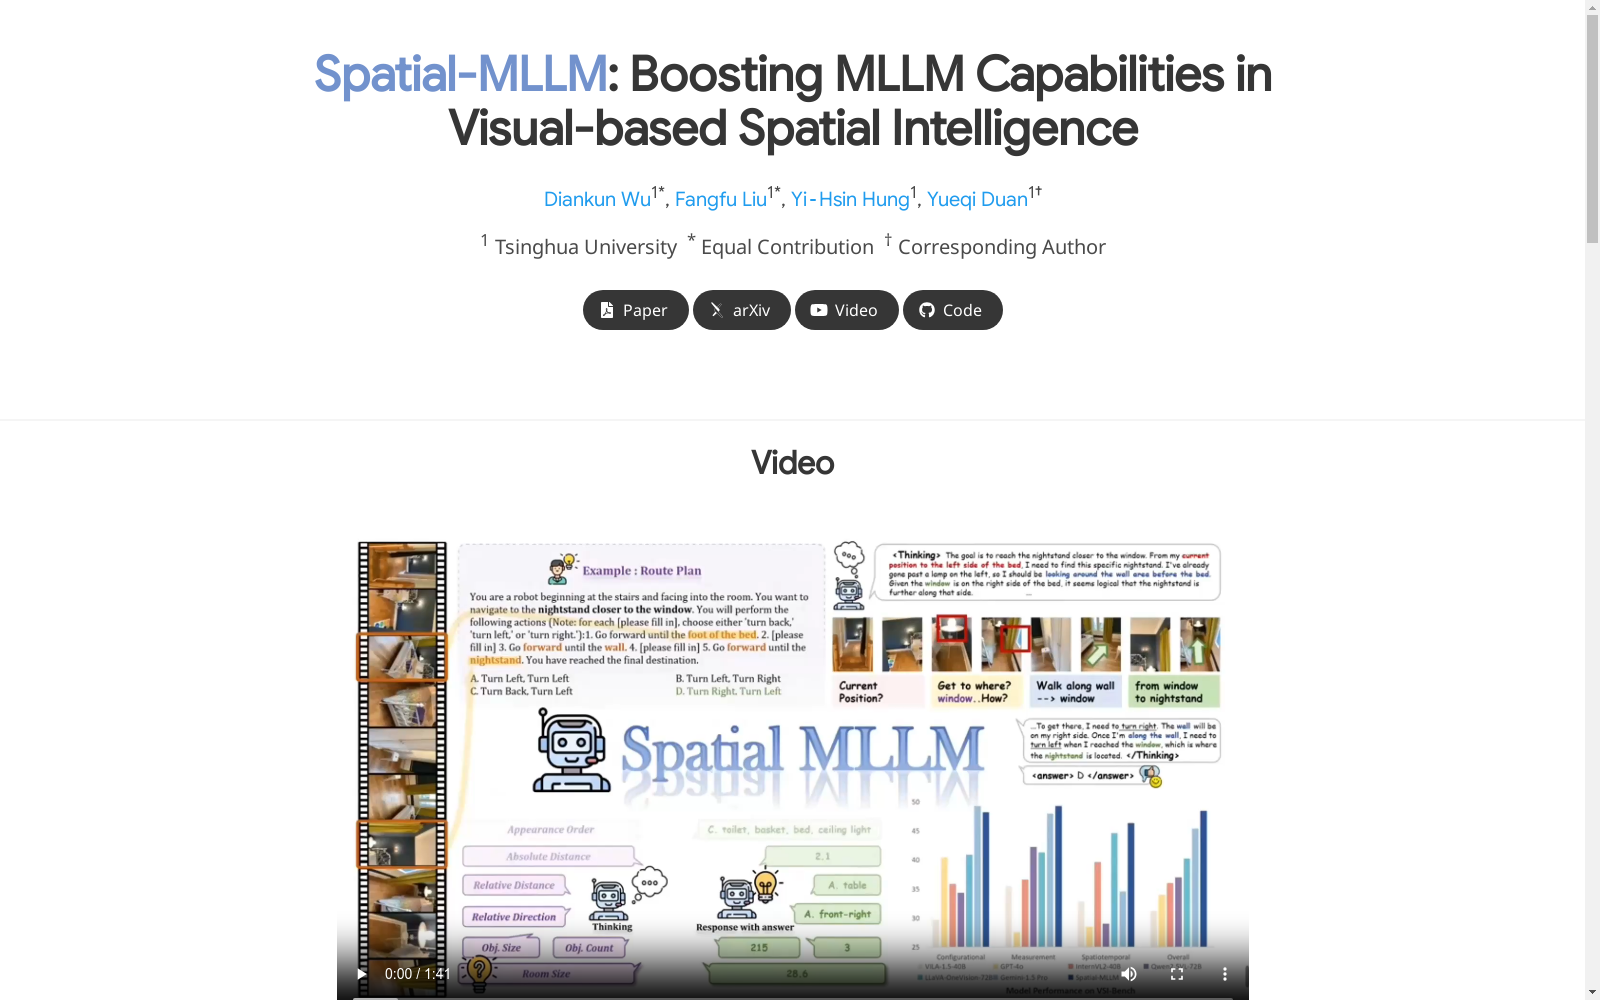
Spatial-MLLM-120k数据集是由清华大学的研究团队创建的,旨在提升现有视频多模态大语言模型的空间智能。该数据集包含120,000个条目,用于训练模型进行视觉基础的空间推理。数据集的构建过程涉及了从纯2D观察中提取视觉基础的空间推理能力,使用了双编码器架构和空间感知帧采样策略。数据集的应用领域包括各种基于视觉的空间理解和推理任务,如视觉-空间智能基准(VSIBench)、ScanQA和SQA3D等,旨在解决现有视频多模态大语言模型在空间智能方面的挑战。
The Spatial-MLLM-120k dataset was created by a research team from Tsinghua University, aiming to enhance the spatial intelligence of existing video multimodal large language models. This dataset comprises 120,000 entries designed to train models for visual-grounded spatial reasoning. The construction of the dataset involves extracting visual-grounded spatial reasoning capabilities from purely 2D visual observations, leveraging a dual-encoder architecture and a spatial-aware frame sampling strategy. Its application scenarios cover various vision-based spatial understanding and reasoning tasks, including Visual-Spatial Intelligence Benchmark (VSIBench), ScanQA, SQA3D, and other related benchmarks, with the purpose of addressing the spatial intelligence challenges faced by current video multimodal large language models.
Spatial-MLLM 数据集概述
基本信息
- 标题: Spatial-MLLM: Boosting MLLM Capabilities in Visual-based Spatial Intelligence
- 作者: Diankun Wu, Fangfu Liu, Yi-Hsin Hung, Yueqi Duan
- 机构: 清华大学
- 论文链接: arXiv
- 代码链接: 未提供具体地址
- 视频链接: 未提供具体地址
研究背景
- 多模态大语言模型(MLLMs)在2D视觉任务上表现优异,但在空间智能方面仍有提升空间。
- 现有3D MLLMs依赖额外的3D或2.5D数据,限制了其在仅有2D输入(如图像或视频)场景中的应用。
方法概述
- 框架名称: Spatial-MLLM
- 核心创新:
- 提出一种从纯2D观察中进行视觉空间推理的新框架。
- 采用双编码器架构:预训练的2D视觉编码器提取语义特征,空间编码器(基于视觉几何模型)提取3D结构特征。
- 引入连接器将两种特征整合为统一的视觉标记。
- 提出空间感知帧采样策略,在推理时选择空间信息丰富的帧。
数据集
- 训练数据集: Spatial-MLLM-120k(由研究团队构建)
性能评估
- VSI-Bench:
- 使用16帧作为输入。
- 在开源模型中表现最佳或次佳。
- ScanQA & SQA3D:
- 在ScanQA验证集和SQA3D测试集上评估。
- 在各模型类别中表现最佳或次佳。
引用格式
bibtex @article{wu2025spatialmllmboostingmllmcapabilities, title={Spatial-MLLM: Boosting MLLM Capabilities in Visual-based Spatial Intelligence}, author={Wu, Diankun and Liu, Fangfu and Hung, Yi-Hsin and Duan, Yueqi}, journal={arXiv preprint arXiv:2505.23747}, year={2025} }
- 1Spatial-MLLM: Boosting MLLM Capabilities in Visual-based Spatial Intelligence清华大学 · 2025年


