piqa-multilingual
收藏资源简介:
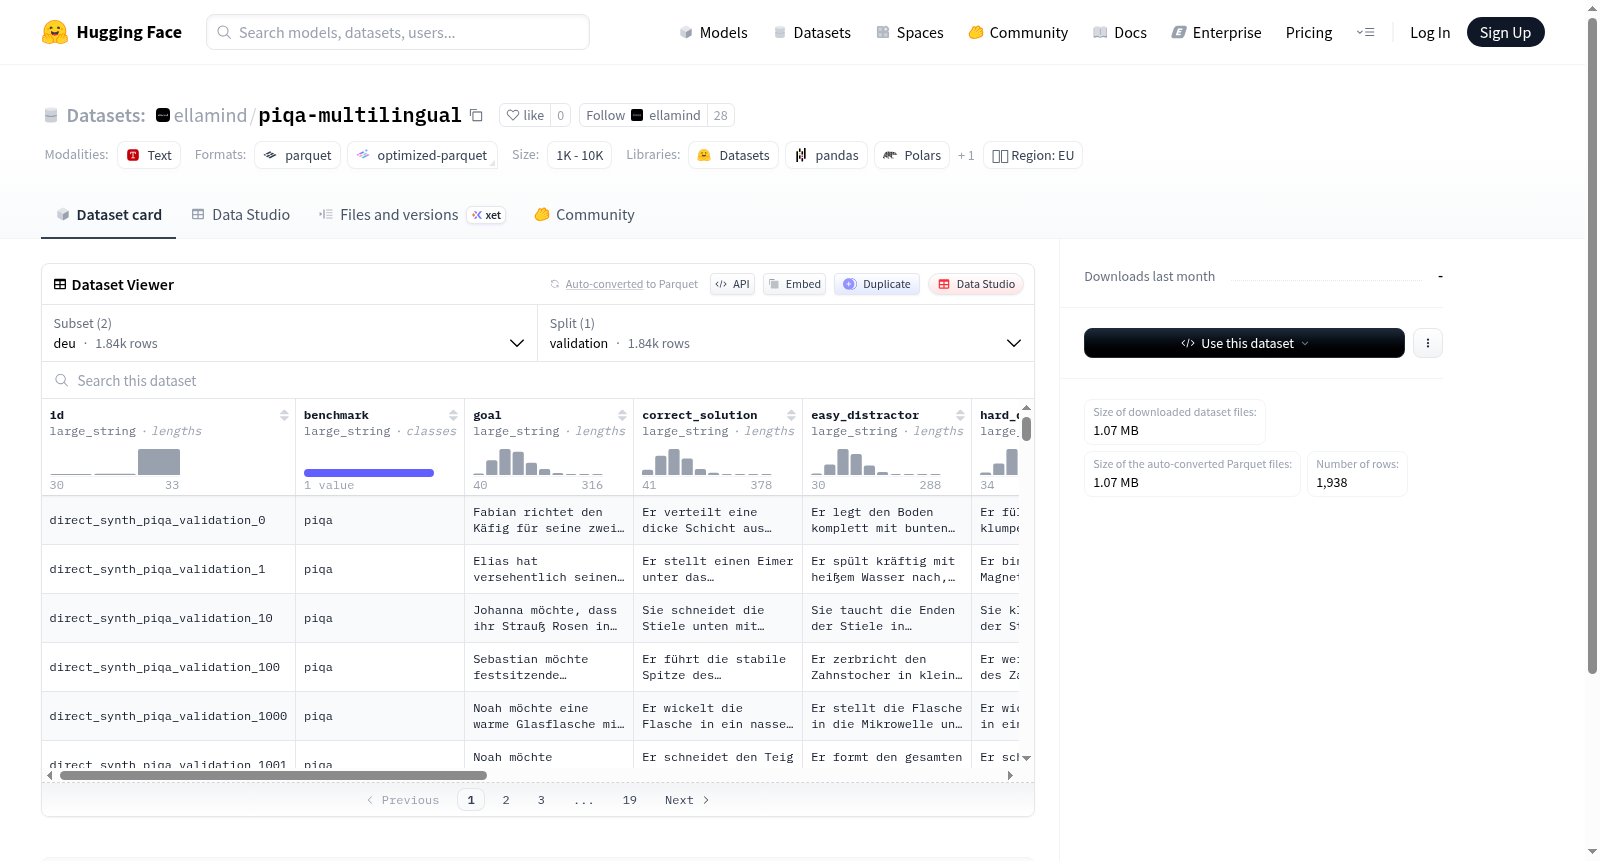
该数据集包含两种语言配置(德语 'deu' 和法语 'fra'),主要用于验证任务。每个配置包含验证集,其中德语配置有1838个样本,法语配置有100个样本。数据集的特征包括:id(唯一标识符)、benchmark(基准信息)、goal(目标描述)、correct_solution(正确解决方案)、easy_distractor(简单干扰项)、hard_distractor(困难干扰项)、seed_id(种子标识符)、topic_description(主题描述)、reasoning_type(推理类型)、synthesis_notes(综合注释)、flag_for_review(需审核标志)和review_reason(审核原因)。数据集适用于自然语言处理任务,如文本理解、干扰项识别和推理任务验证。
This dataset includes two language configurations: German ('deu') and French ('fra'), primarily designed for validation tasks. Each configuration is equipped with a validation set, where the German configuration contains 1838 samples and the French configuration contains 100 samples. The dataset has the following attributes: id (unique identifier), benchmark (benchmark information), goal (target description), correct_solution (correct solution), easy_distractor (simple distractor), hard_distractor (difficult distractor), seed_id (seed identifier), topic_description (topic description), reasoning_type (reasoning type), synthesis_notes (synthesis notes), flag_for_review (flag for review), and review_reason (review reason). This dataset is applicable to natural language processing tasks such as text understanding, distractor recognition and reasoning task validation.