登录后查看消息通知
搜索
常见问题
消息
登录
首页
/
数据集
/
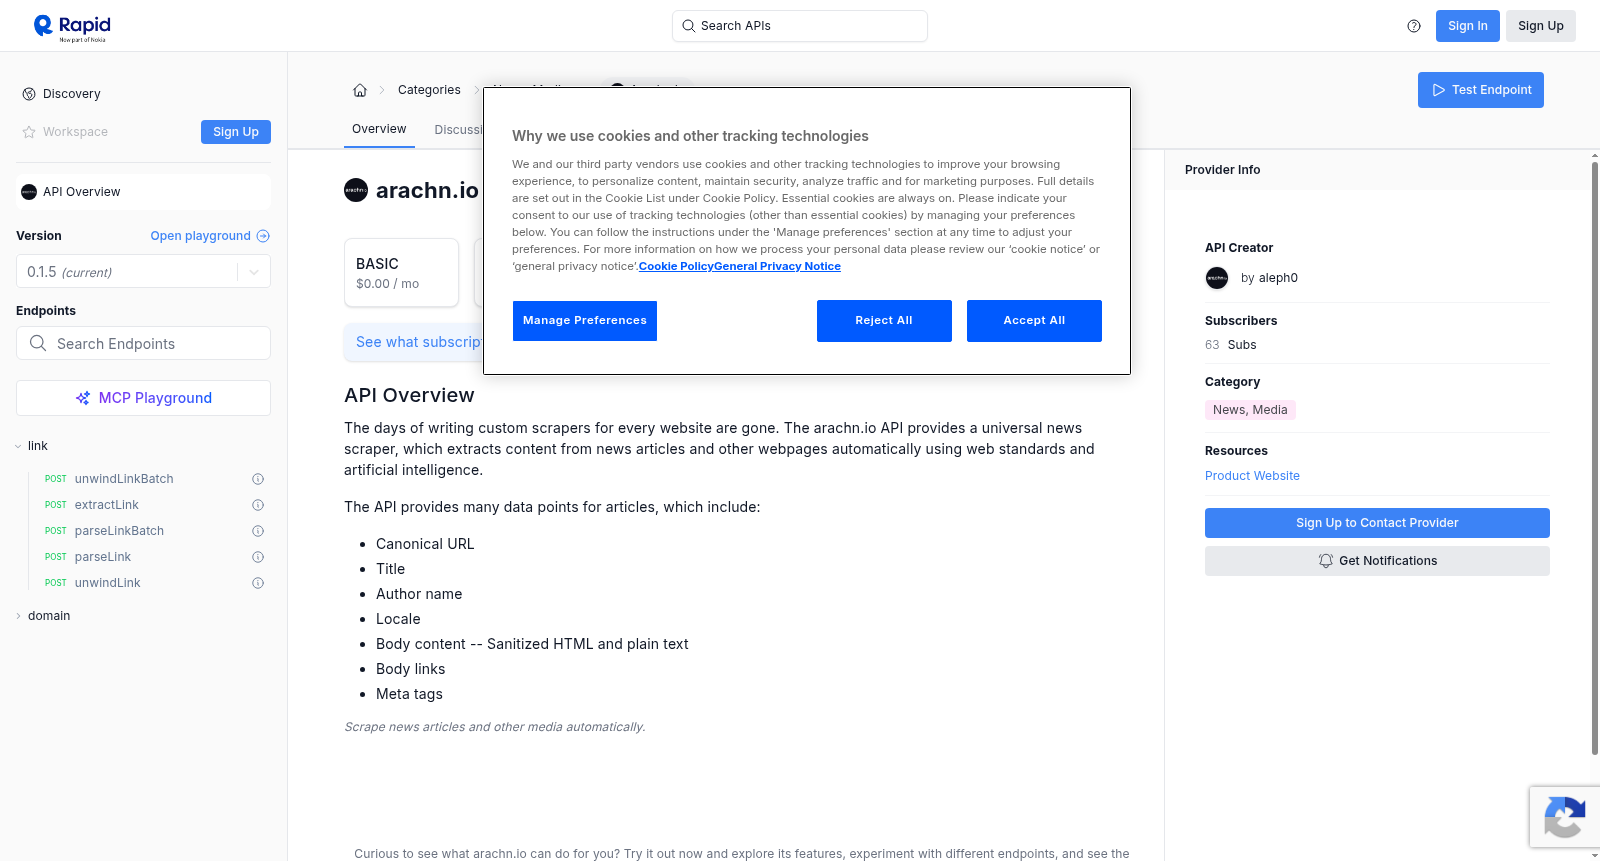
arachn.io
arachn.io
收藏
RapidAPI
2023-03-21 更新
2024-05-11 收录
网络爬虫
新闻媒体
数据链接:
https://rapidapi.com/aleph0-aleph0-default/api/arachn-io
数据链接
链接失效反馈
官方服务:
问题咨询
购买咨询
在线客服
NEW
资源简介:
Scrape news articles and other media automatically.
应用场景:
创建时间:
2023-03-21
搜集汇总
数据集介绍
背景与挑战
背景概述
arachn.io 是一个用于自动抓取新闻文章和其他媒体内容的数据集。它通过爬虫技术实现对网络信息的自动化采集。
以上内容由遇见数据集搜集并总结生成
相关数据集
KathirKs/CC-MAIN-2017-22_row_wise_20241007_162941
网络爬虫
数据挖掘
该数据集包含文本内容、唯一标识符和元数据三个主要特征。文本内容为字符串序列,唯一标识符为字符串类型,元数据包含dump、file_path、id和url四个子字段,均为字符串类型。数据集分为一个训练集,包含1,688,855个样本,总大小为20,446,020,473字节。下载大小为7,685,259,506字节。数据集的配置文件名为default,数据文件路径为data/train-*。
Hugging Face
2024-10-07 更新
15
0
Yehor/ukrainian-news-headlines
新闻媒体
自然语言处理
该数据集包含5,242,391个乌克兰新闻标题样本。
Hugging Face
2022-07-30 更新
6
0
Amazon Website Scraper
电子商务
网络爬虫
Amazon Website Scraper allows easy access to products, prices, sales rank, and reviews data from Amazon in JSON format.
RapidAPI
2021-07-23 更新
6
0
Amazon Scraper API
网络爬虫
电子商务
An Amazon Scraper API is a tool that allows you to extract data from the Amazon website using a programmatic interface. This can include information such as product details, pricing, and reviews. The
RapidAPI
2023-01-23 更新
13
0
Websites using Google AdsBot Disallow in Brazil
网络爬虫
广告技术
A list of all websites using Google AdsBot Disallow in Brazil. Based on global website indexing by BuiltWith.
trends.builtwith.com
6
0
© 2023-2026 上海数据发展科技有限责任公司 版权所有
沪ICP备17003045号-15
沪公网安备31010402336585号
热门搜索
社区交流群
科研交流群
商业服务
数据资源
寻源服务
数据采集
标注服务
数据产品
代理销售
数据领域
凭证登记
数据产品
介绍推广