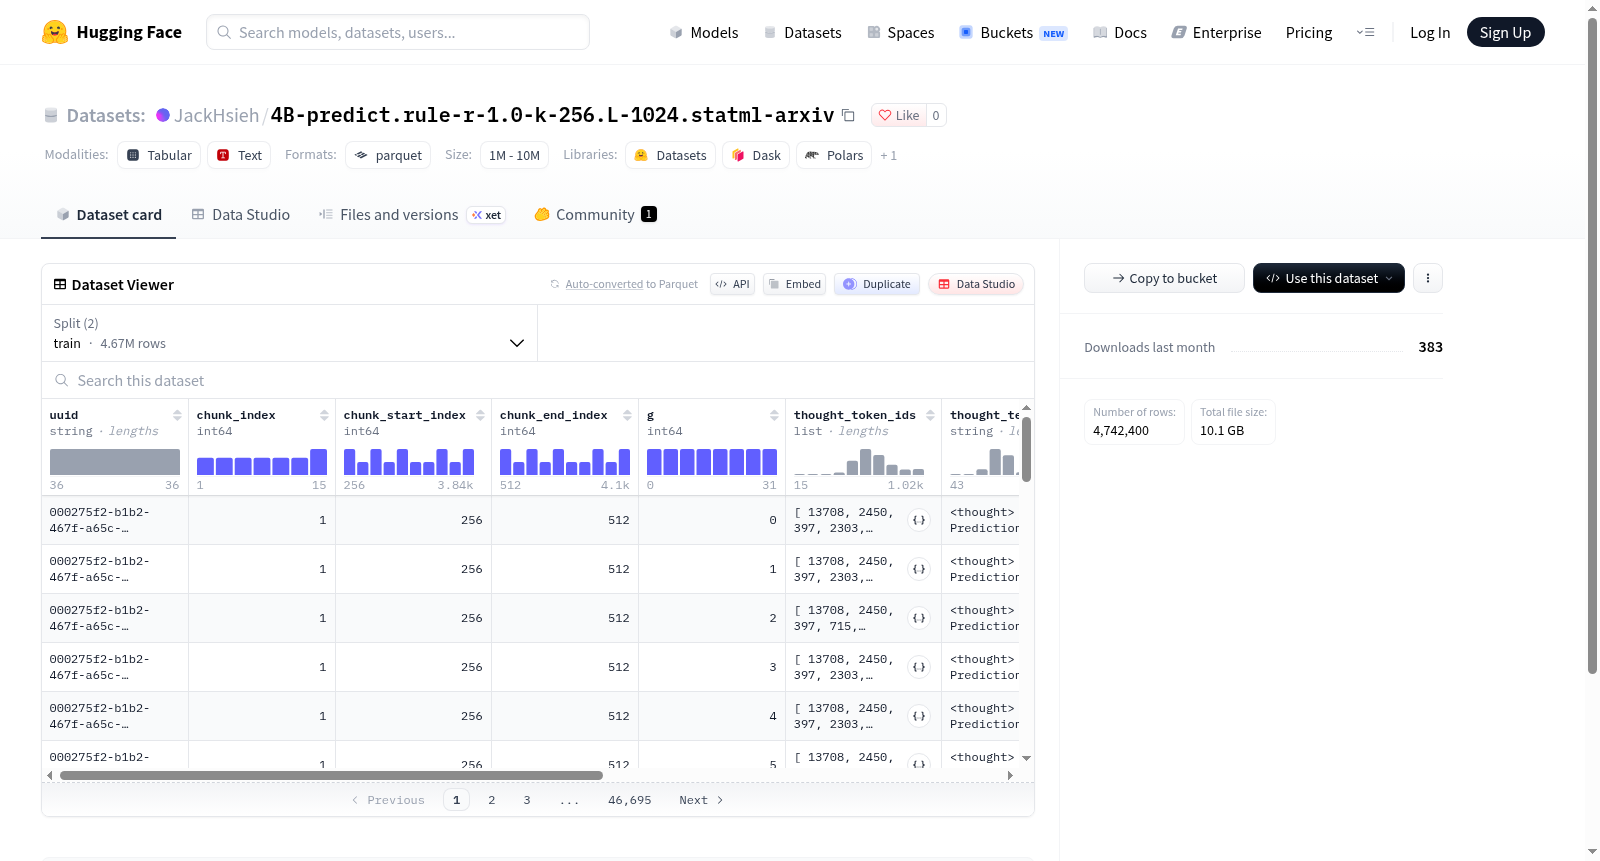
JackHsieh/4B-predict.rule-r-1.0-k-256.L-1024.statml-arxiv
收藏资源简介:
--- dataset_info: features: - name: uuid dtype: string - name: chunk_index dtype: int64 - name: chunk_start_index dtype: int64 - name: chunk_end_index dtype: int64 - name: g dtype: int64 - name: thought_token_ids list: int64 - name: thought_text dtype: string - name: truncated dtype: bool - name: finish_reason dtype: string - name: generated_at dtype: string - name: generation_seconds dtype: float64 splits: - name: train num_bytes: 38456839303.0 num_examples: 4669440 - name: test num_bytes: 601467385.0 num_examples: 72960 download_size: 10097410336 dataset_size: 39058306688.0 configs: - config_name: default data_files: - split: train path: data/train-* - split: test path: data/test-* ---
Dataset containing thought process text with chunk indices, token ids, and generation metadata.