
SpatialBench
收藏资源简介:
SpatialBench是由多所顶尖学术机构联合构建的大规模空间认知评估数据集,专为测评多模态大语言模型的空间推理能力而设计。该数据集包含1,347个精细标注的问答对,源自50个第一人称视角视频,覆盖室内外静态与动态场景,数据来源通过定制传感平台采集的实景录像。数据集构建采用分层认知框架,将空间智能分解为五个渐进层级,通过专业标注流程实现多维度能力评估。该数据集主要应用于人工智能领域,旨在系统解决现有模型在符号推理、因果推断和路径规划等高级空间认知任务中的能力缺陷问题。
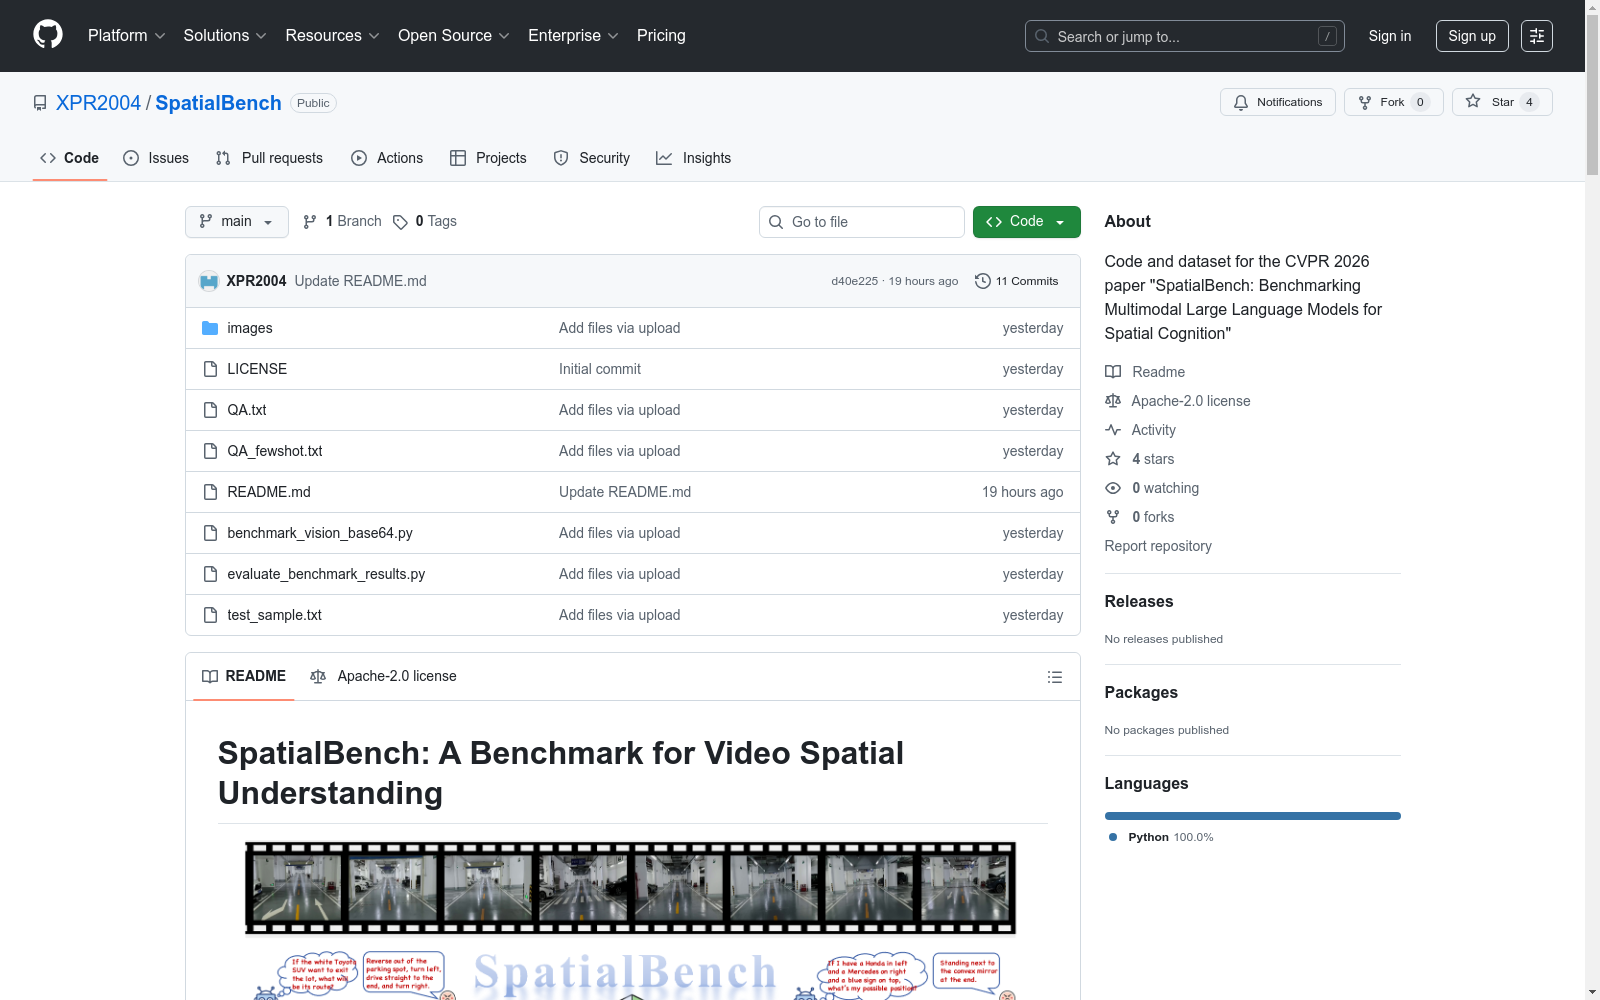
SpatialBench is a large-scale spatial cognitive assessment dataset jointly developed by multiple leading academic institutions, specifically designed to evaluate the spatial reasoning capabilities of multimodal large language models. This dataset contains 1,347 meticulously annotated question-answer pairs sourced from 50 first-person perspective videos, covering both indoor and outdoor static and dynamic scenarios. The data is collected from real-world footage captured via a custom sensing platform. The dataset is constructed using a hierarchical cognitive framework, which decomposes spatial intelligence into five progressive levels, and enables multi-dimensional capability assessment through a professional annotation workflow. Primarily applied in the field of artificial intelligence, this dataset aims to systematically resolve the capability deficits of existing models in advanced spatial cognitive tasks such as symbolic reasoning, causal inference and path planning.
SpatialBench 数据集概述
数据集基本信息
- 数据集名称: SpatialBench
- 核心功能: 评估多模态大语言模型的视频空间理解能力
- 关联论文: CVPR 2026论文《SpatialBench: Benchmarking Multimodal Large Language Models for Spatial Cognition》
- 论文链接: https://arxiv.org/abs/2511.21471
数据集特点
- 多维度评估: 涵盖5个主要类别和15个子类别的空间任务
- 任务类型: 观察与测量、拓扑与组合、符号视觉推理、空间因果关系、空间规划
- 支持模型: 兼容OpenAI Chat Completion API的任何视觉语言模型
数据集文件组成
- QA.txt: 标准基准数据集,包含空间推理问题
- QA_fewshot.txt: 深度引导模式数据集,用于少样本学习
- test_sample.txt: 快速测试和调试的小样本数据集
- dataset/: 测试视频文件目录
数据格式规范
json [ { "sample": { "problem_id": 1001, "path": "dataset/video_01.mp4", "problem_type": "object_counting", "problem": "How many red cups are in the video?", "options": ["1", "2", "3", "4"], "solution": "<answer>2</answer>", "scene_type": "indoor" } } ]
评估方法
- 多选题: 匹配模型输出选项,正确得1分,错误得0分
- 回归问题: 使用平均相对精度算法,得分范围0-1
- 加权总分: 根据不同任务类别的难度和重要性计算最终得分
引用信息
@misc{xu2025spatialbenchbenchmarkingmultimodallarge, title={SpatialBench: Benchmarking Multimodal Large Language Models for Spatial Cognition}, author={Peiran Xu and Sudong Wang and Yao Zhu and Jianing Li and Yunjian Zhang}, year={2025}, eprint={2511.21471}, archivePrefix={arXiv}, primaryClass={cs.AI}, url={https://arxiv.org/abs/2511.21471}, }
- 1SpatialBench: Benchmarking Multimodal Large Language Models for Spatial Cognition中山大学、香港科技大学(广州)、浙江大学、北京大学、中国科学院大学 · 2025年


