marimeireles/scifi-corpus
收藏资源简介:
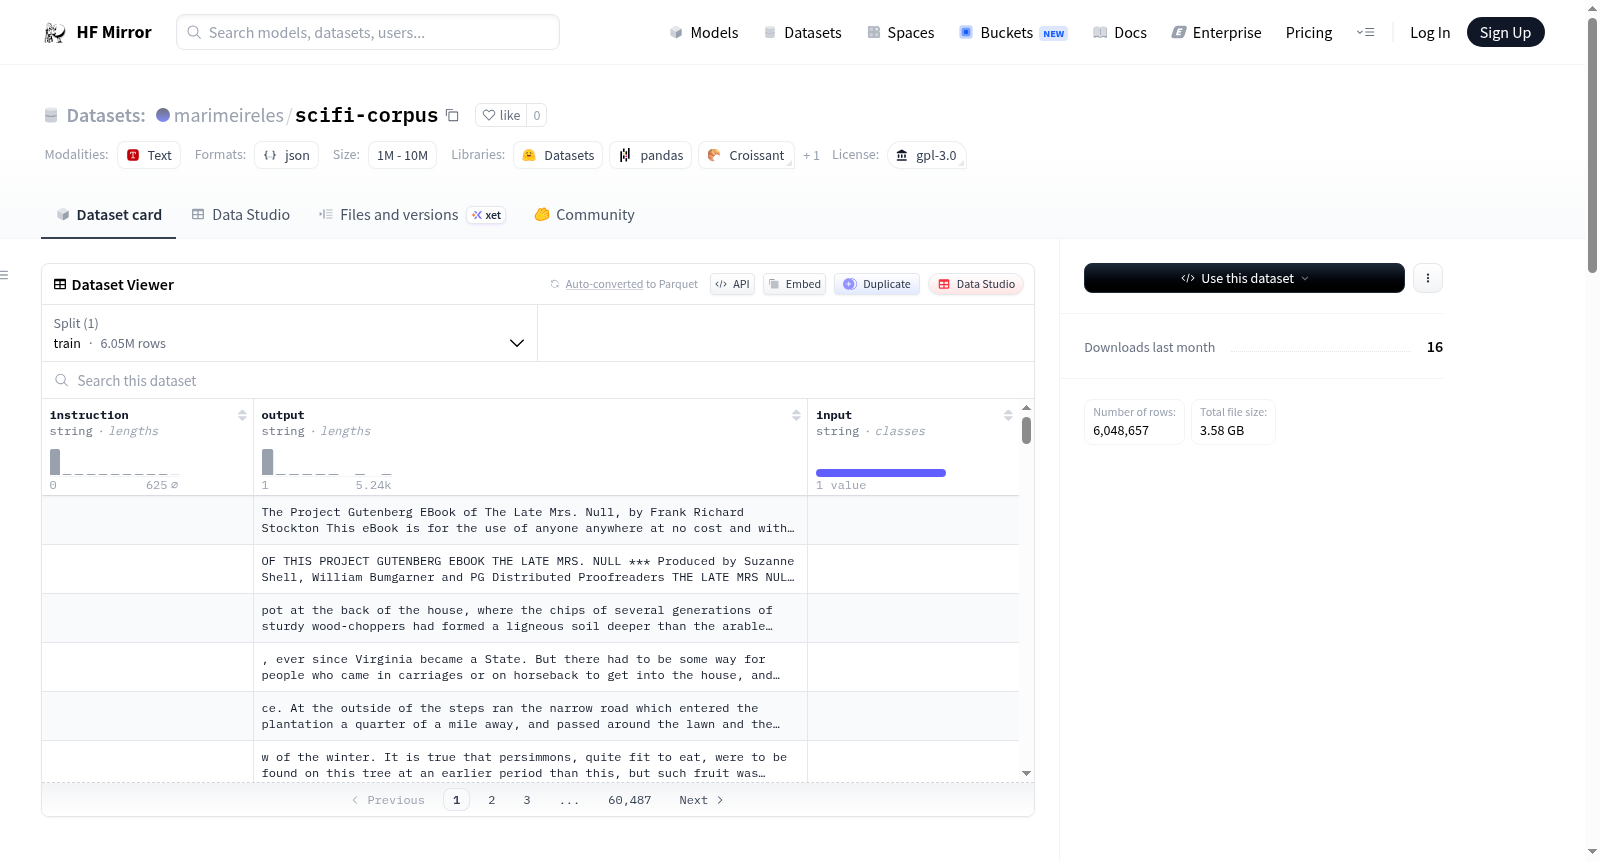
这是一个GPLv3许可证下的科幻语料库,用于训练大型语言模型(LLMs)。数据集包含一个JSON格式的文件,其中每个条目包含一个指令、输入和输出。指令是通过不同的语言模型(如GPT、Falcon、Llama等)基于输出生成的,而输出则来自多个不同的源(如Reddit、OMDB、Gutenberg等)。数据集的主要用途是用于微调当前的LLM模型,但用户可以根据需要修改数据格式。数据集目前包含约3GB的数据。
This is a sci-fi corpus licensed under the GPLv3 license, designed for training large language models (LLMs). The dataset includes a single JSON-formatted file, with each entry comprising an instruction, an input, and an output. The instructions are generated based on the outputs via various large language models such as GPT, Falcon, Llama, and others, while the outputs are sourced from multiple distinct platforms and resources including Reddit, OMDB, Gutenberg, and more. The core intended use case of this dataset is fine-tuning existing LLM models, and users may modify the data format according to their specific needs. Currently, the dataset contains approximately 3GB of data.
数据集概述
数据集名称
- 名称:scifi-corpus
数据集描述
- 目的:用于训练大型语言模型(LLMs)的科幻(sci-fi)语料库。
- 许可:GPLv3,允许自由使用和修改数据集,但需遵循GPLv3许可协议。
数据集内容
-
格式:JSON文件格式,包含指令、输入和输出。
-
示例: json { "instruction": "...", "input": "", "output": "..." }
-
数据量:约3GB。
-
用途:主要用于当前(2023年)大型语言模型的微调。
数据集来源
- 来源:包括reddit、omdb、gutenberg等多个来源。
- 状态:部分来源已完成数据收集,部分需要脚本或进一步处理。
如何参与
- 贡献:欢迎贡献,可通过GitHub项目页面了解参与方式。
如何引用
- 引用格式:Meireles, M. (2023). Sci-Fi Corpus. ORCID: 0000-0001-9227-9798. Available at: https://huggingface.co/datasets/elektra/scifi-corpus