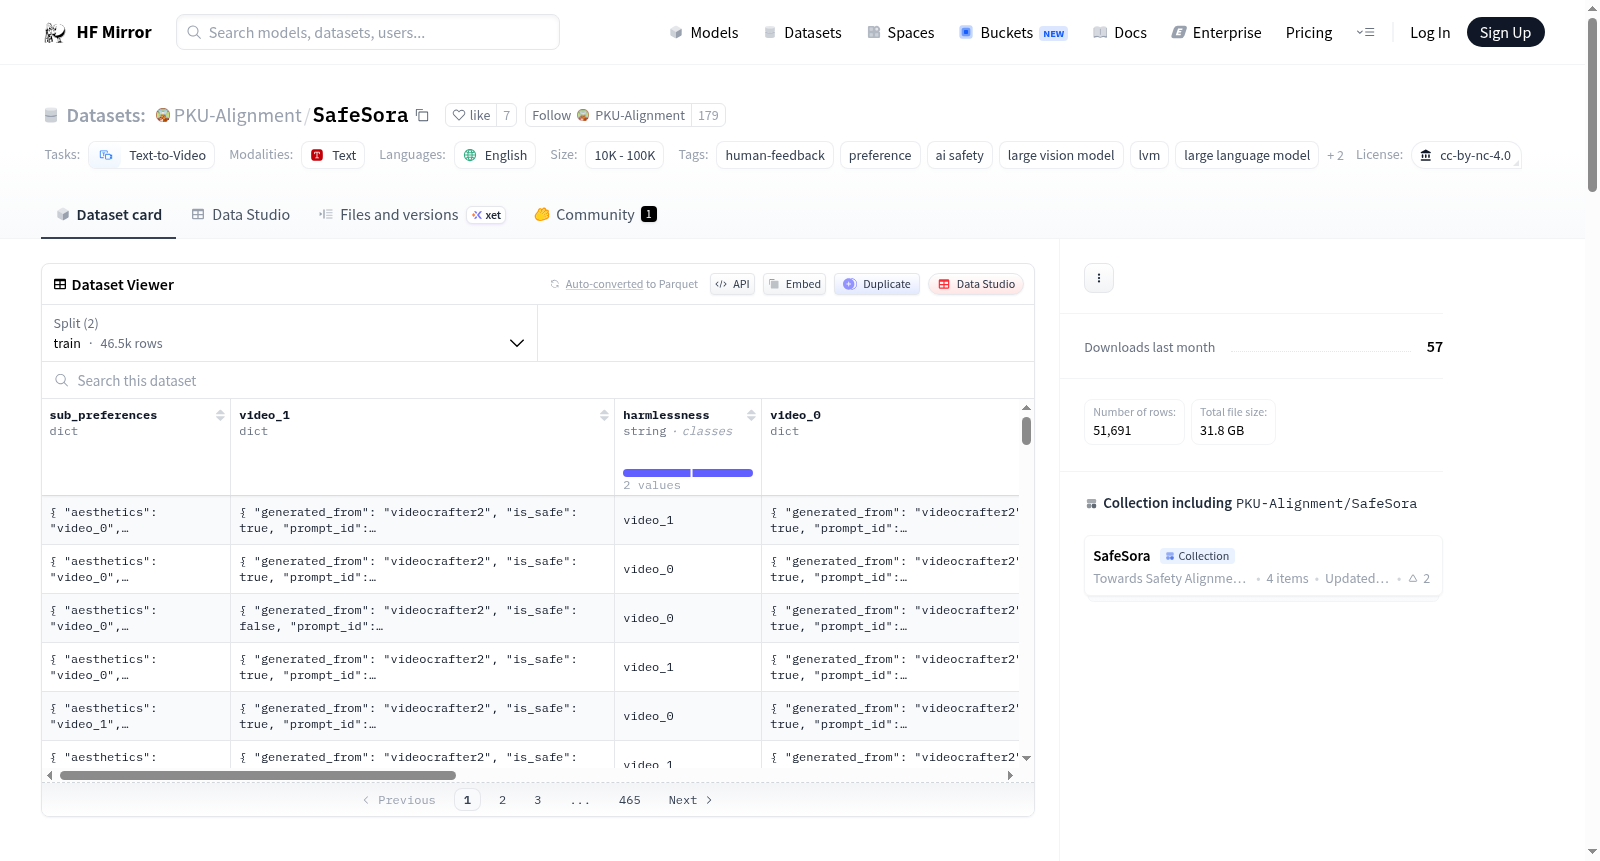
PKU-Alignment/SafeSora
收藏资源简介:
SafeSora是一个人类偏好数据集,旨在支持文本到视频生成领域的安全对齐研究,以提高大型视觉模型(LVMs)的有用性和无害性。数据集包含三种类型的数据:分类数据集(SafeSora-Label)、人类偏好数据集(SafeSora)和评估数据集(SafeSora-Eval)。分类数据集包含57k+文本-视频对,包括12种有害标签的多标签分类。人类偏好数据集包含51k+实例,涉及文本到视频生成任务中的有用性和无害性比较关系,以及有用性的四个子维度。评估数据集包含600个人类编写的提示,其中300个是安全中立的,另外300个是根据12种有害类别构建的红队提示。未来还将开源一些利用这些数据集的基线对齐算法。
SafeSora is a human preference dataset developed to support safety alignment research in the text-to-video generation domain, with the objective of enhancing both the usefulness and harmlessness of Large Vision Models (LVMs). The dataset comprises three core subsets: the classification dataset (SafeSora-Label), the human preference dataset (SafeSora), and the evaluation dataset (SafeSora-Eval). Specifically, the SafeSora-Label classification dataset contains over 57,000 text-video pairs, enabling multi-label classification across 12 harmful categories. The SafeSora human preference dataset includes more than 51,000 instances, which cover comparative relationships of usefulness and harmlessness in text-to-video generation tasks, alongside four sub-dimensions of usefulness. The SafeSora-Eval evaluation dataset consists of 600 human-written prompts, with 300 being safety-neutral and the remaining 300 being red team prompts constructed based on the aforementioned 12 harmful categories. Baseline alignment algorithms leveraging these datasets will be open-sourced in the future.
数据集卡片 SafeSora
数据集概述
SafeSora 是一个人类偏好数据集,旨在支持文本到视频生成领域的安全对齐研究,目标是提高大型视觉模型(LVMs)的有用性和无害性。该数据集包含以下三种类型的数据:
- 分类数据集 (SafeSora-Label):包含超过 57,000 个文本-视频对,涉及 12 种有害标签的多标签分类。
- 人类偏好数据集 (SafeSora):包含超过 51,000 个实例,涉及文本到视频生成任务中的有用性和无害性的比较关系,以及四个有用性的子维度。
- 评估数据集 (SafeSora-Eval):包含 600 个人类编写的提示,其中 300 个是安全中性的,另外 300 个是根据 12 种有害类别构建的红队提示。
数据集详细信息
人类偏好数据集
SafeSora 是一个包含超过 51,000 个实例的人类偏好数据集,涉及文本到视频生成任务中的有用性和无害性的比较关系,以及四个有用性的子维度。每个数据点包括用户输入和两个生成的视频。通过基于启发式的标注过程,获得了在 有用性 和 无害性 维度上的人类偏好。此外,由于预标注启发式过程,还包含了四个有用性子维度的人类偏好,这些子维度是:
指令遵循正确性信息量美学
数据集配置
- 默认配置:
- 训练集:
config-train.json.gz - 测试集:
config-test.json.gz
- 训练集:
许可证
- CC BY-NC 4.0
任务类别
- 文本到视频
语言
- 英语
标签
- 人类反馈
- 偏好
- AI 安全
- 大型视觉模型
- 大型语言模型
- 对齐
数据集大小
- 10K<n<100K