jganzabalseenka/stop_phrases_train_166396_assets
收藏资源简介:
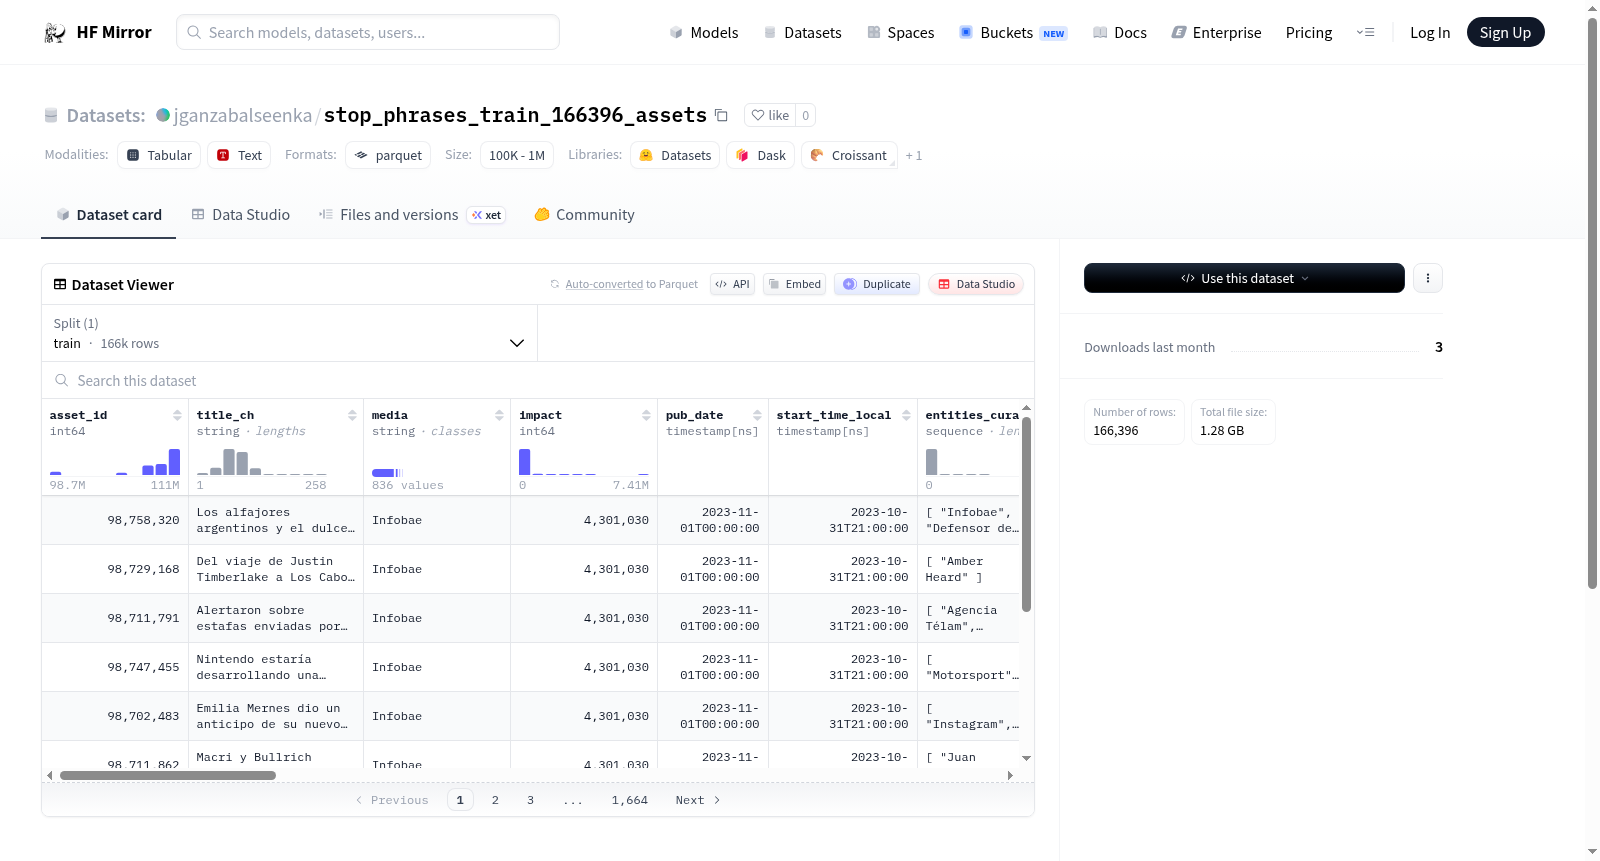
该数据集包含新闻文章的相关信息,字段包括资产ID、中文标题、媒体来源、影响力评分、发布日期、本地开始时间、实体信息(包括经过整理的实体和原始实体)、预测的实体时间、关键词、预测的关键词时间、截断文本、标题和文本的组合、预测延迟、完整文本等。数据集主要用于新闻内容的分析和处理,可能涉及实体识别、关键词提取、文本分析等NLP任务。
This dataset contains information related to news articles, including fields such as asset ID, Chinese title, media source, impact score, publication date, local start time, entity information (including curated entities and raw entities), predicted entity time, keywords, predicted keyword time, truncated text, combination of title and text, prediction delay, full text, etc. The dataset is primarily used for the analysis and processing of news content, potentially involving NLP tasks such as entity recognition, keyword extraction, and text analysis.
数据集概述
数据集信息
-
特征列表:
asset_id: 整数类型title_ch: 字符串类型media: 字符串类型impact: 整数类型pub_date: 时间戳类型start_time_local: 时间戳类型entities_curated: 字符串序列类型entities: 字符串序列类型predicted_at_entities: 时间戳类型entities_raw_transformers: 列表类型entities: 列表类型end: 整数类型entity_group: 字符串类型score: 浮点数类型start: 整数类型word: 字符串类型
text: 字符串类型
entities_transformers: 字符串序列类型title: 字符串类型text: 字符串类型keywords: 字符串序列类型predicted_at_keywords: 时间戳类型truncated_text: 字符串类型title_and_text: 字符串类型prediction_delay_predictions: 浮点数类型prediction_delay: 浮点数类型full_text: 字符串类型__index_level_0__: 整数类型
-
数据分割:
train:- 字节数: 2368614650
- 样本数: 166396
-
下载大小: 1281401661 字节
-
数据集大小: 2368614650 字节
配置信息
- 配置名称:
default- 数据文件路径:
data/train-*
- 数据文件路径:
数据集URI
news_2023-11-01_24hsnews_2023-11-02_24hsnews_2024-04-01_24hsnews_2024-04-02_24hsnews_2024-05-01_24hsnews_2024-05-02_24hsnews_2024-05-20_24hsnews_2024-05-21_24hsnews_2024-06-01_24hsnews_2024-06-02_24hsnews_2024-06-04_24hsnews_2024-06-05_24hs