mii-llm/pinocchio
收藏资源简介:
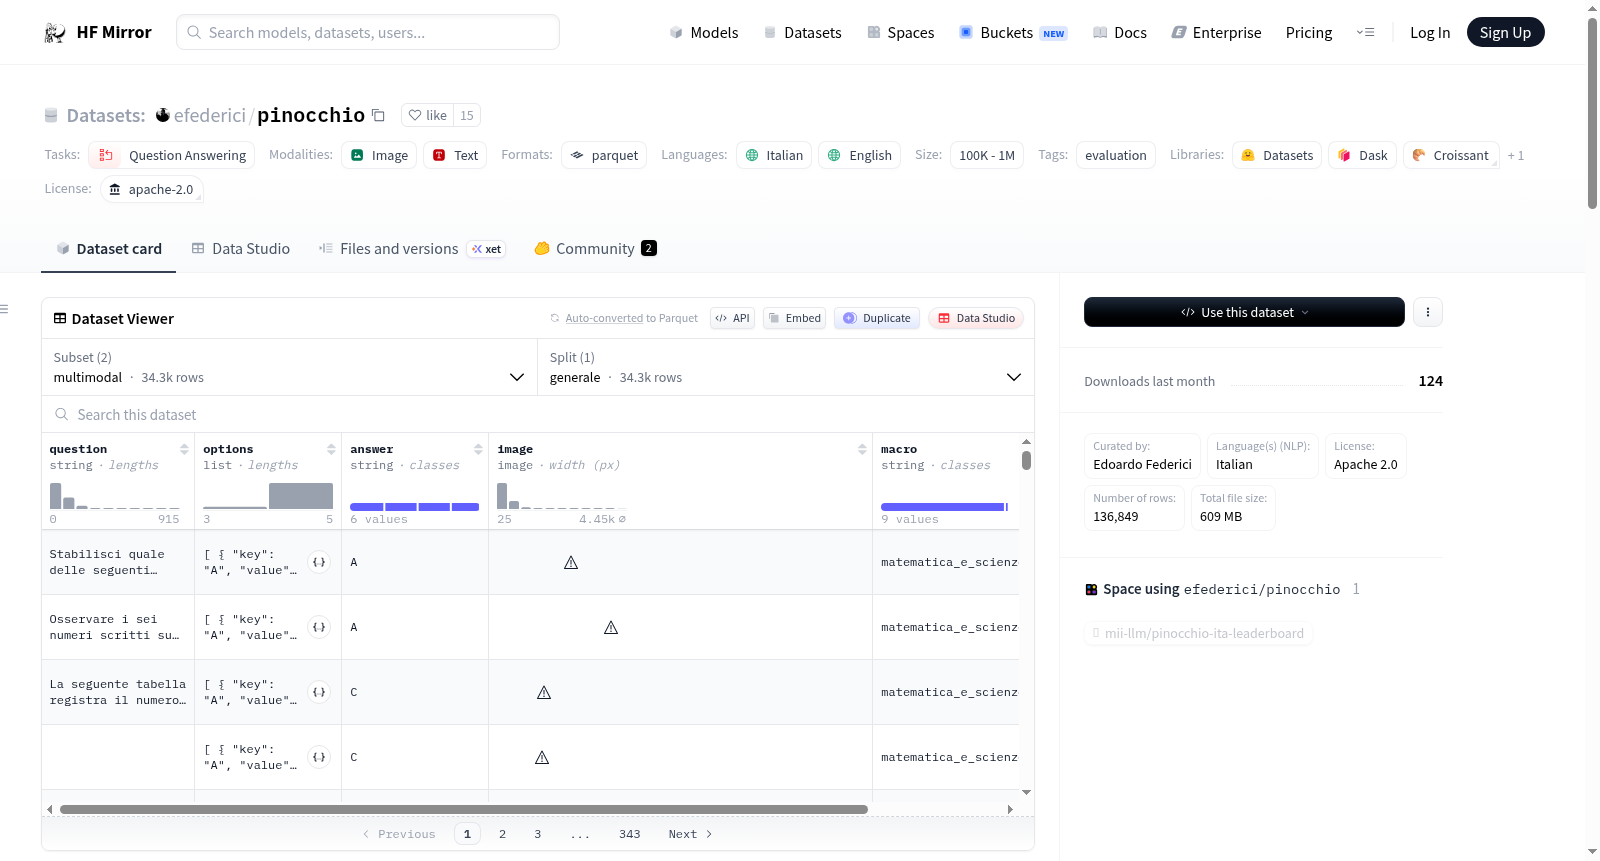
Pinocchio数据集是一个全面的、具有挑战性的自然语言理解(NLU)数据集,旨在严格评估语言模型的能力,特别关注意大利语言、文化和各种专业领域。数据集包含约140,000个问题,涵盖多种模态和约40个学科。数据集的特点包括对意大利语的全面关注、多样化的专业领域、多模态评估和难度分层。数据集由Edoardo Federici策划,采用Apache 2.0许可证。
The Pinocchio dataset is a comprehensive and challenging Natural Language Understanding (NLU) dataset designed specifically for Italian language and culture, containing approximately 140,000 questions across multiple modalities and about 40 disciplines. It particularly focuses on Italian language and culture, filling a crucial gap in NLU evaluation. It includes dedicated splits for law, foreign languages, logic, and STEM, as well as a multimodal split that allows for the assessment of models ability to understand and reason about both text and images. The dataset also provides carefully curated subsets, allowing for nuanced evaluation of model capabilities.
Pinocchio 数据集概述
基本信息
- 语言: 意大利语, 英语
- 许可证: Apache 2.0
- 数据集大小: 100K<n<1M
- 任务类别: 问答
- 数据集名称: Pinocchio
数据集配置
多模态配置 (multimodal)
- 特征:
question: 字符串options: 列表,包含key和value,均为字符串answer: 字符串image: 图像macro: 字符串category: 字符串
- 分割:
generale: 34275 个样本, 673172291.25 字节
- 下载大小: 590129851 字节
- 数据集大小: 673172291.25 字节
文本配置 (text)
- 特征:
question: 字符串options: 列表,包含key和value,均为字符串answer: 字符串macro: 字符串category: 字符串
- 分割:
cultura: 10000 个样本, 4058099 字节diritto: 10000 个样本, 4552269 字节lingua_straniera: 10000 个样本, 1918919 字节logica: 10000 个样本, 3466676 字节matematica_e_scienze: 10000 个样本, 2632463 字节generale: 52574 个样本, 20438794 字节
- 下载大小: 19120837 字节
- 数据集大小: 37067220 字节
数据文件路径
- 多模态配置:
generale:multimodal/generale-*
- 文本配置:
cultura:text/cultura-*diritto:text/diritto-*lingua_straniera:text/lingua_straniera-*logica:text/logica-*matematica_e_scienze:text/matematica_e_scienze-*generale:text/generale-*
标签
- evaluation