
ACAV100M
收藏资源简介:
ACAV100M是一个大规模的音频-视觉视频数据集,由首尔国立大学创建,旨在支持自监督视频表示学习。该数据集包含1亿个视频片段,这些片段具有高度的音频-视觉对应性,非常适合用于训练自监督模型。数据集的创建过程采用了一种自动化的数据集策划方法,基于子集优化,旨在最大化视频中音频和视觉通道之间的互信息。ACAV100M数据集的应用领域主要集中在解决视频理解中的自监督学习问题,通过利用大量未标记的在线视频数据,提高模型的性能和泛化能力。
ACAV100M is a large-scale audio-visual video dataset developed by Seoul National University, designed to support self-supervised video representation learning. This dataset contains 100 million video clips with strong audio-visual correspondence, making it highly suitable for training self-supervised models. The dataset was constructed using an automated dataset curation method based on subset optimization, which aims to maximize the mutual information between the audio and visual modalities of the videos. The main application scenarios of ACAV100M focus on solving self-supervised learning tasks in video understanding, leveraging large volumes of unlabeled online video data to enhance model performance and generalization capability.
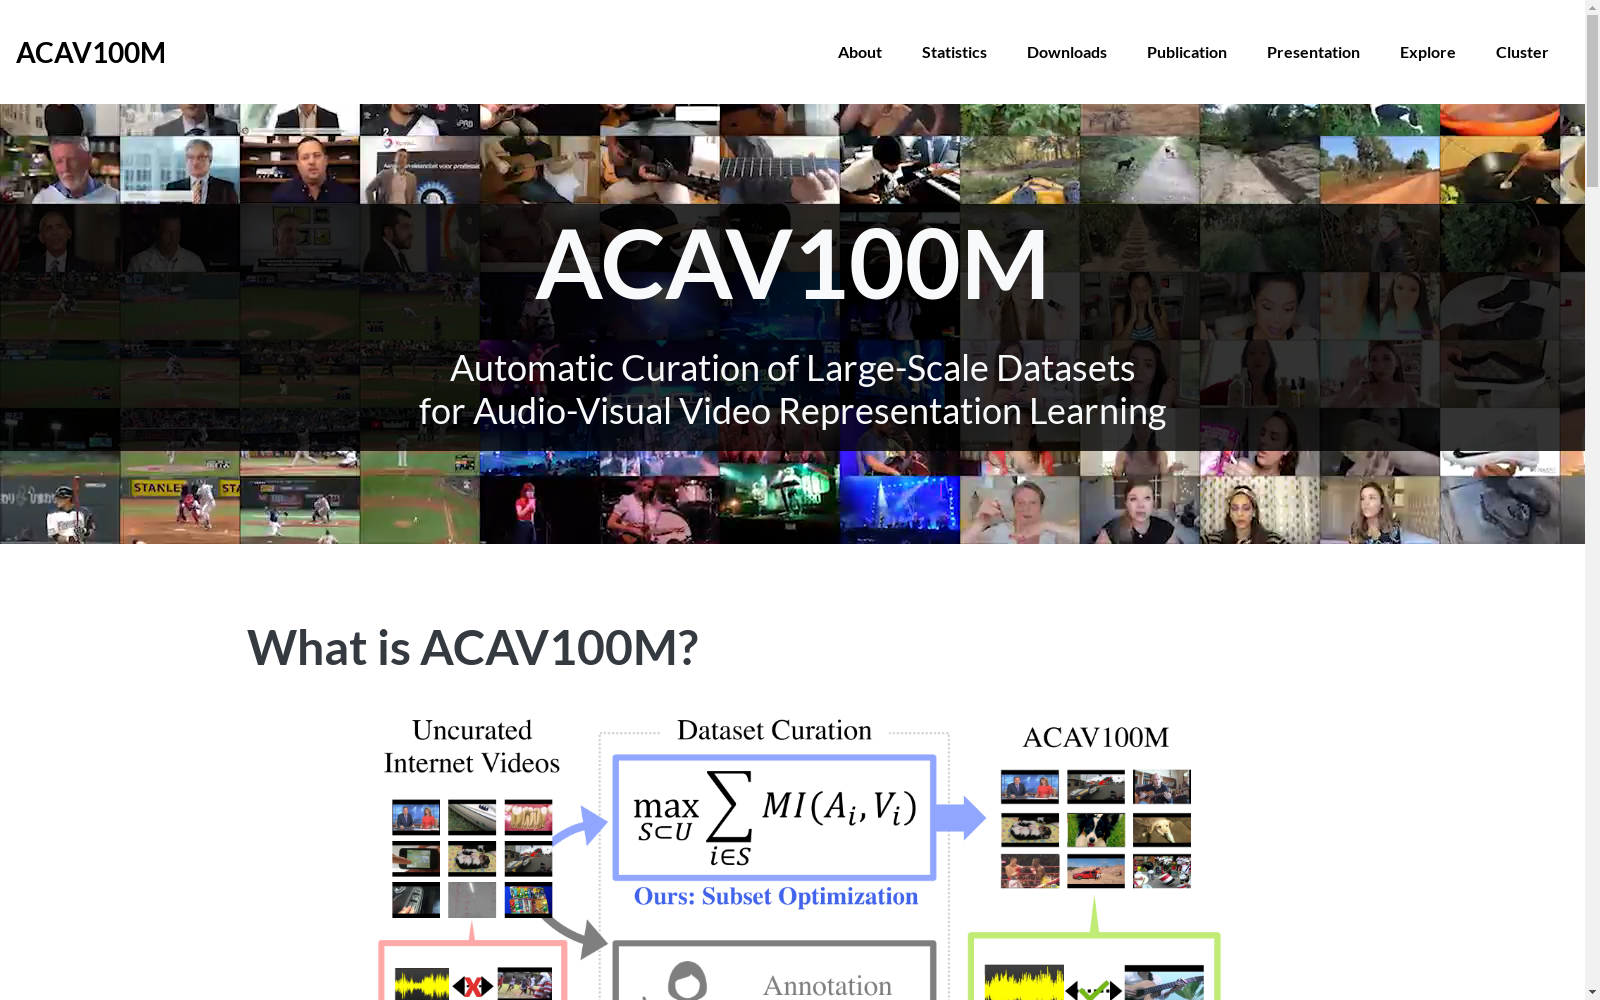
- 1ACAV100M: Automatic Curation of Large-Scale Datasets for Audio-Visual Video Representation Learning首尔国立大学 · 2021年


