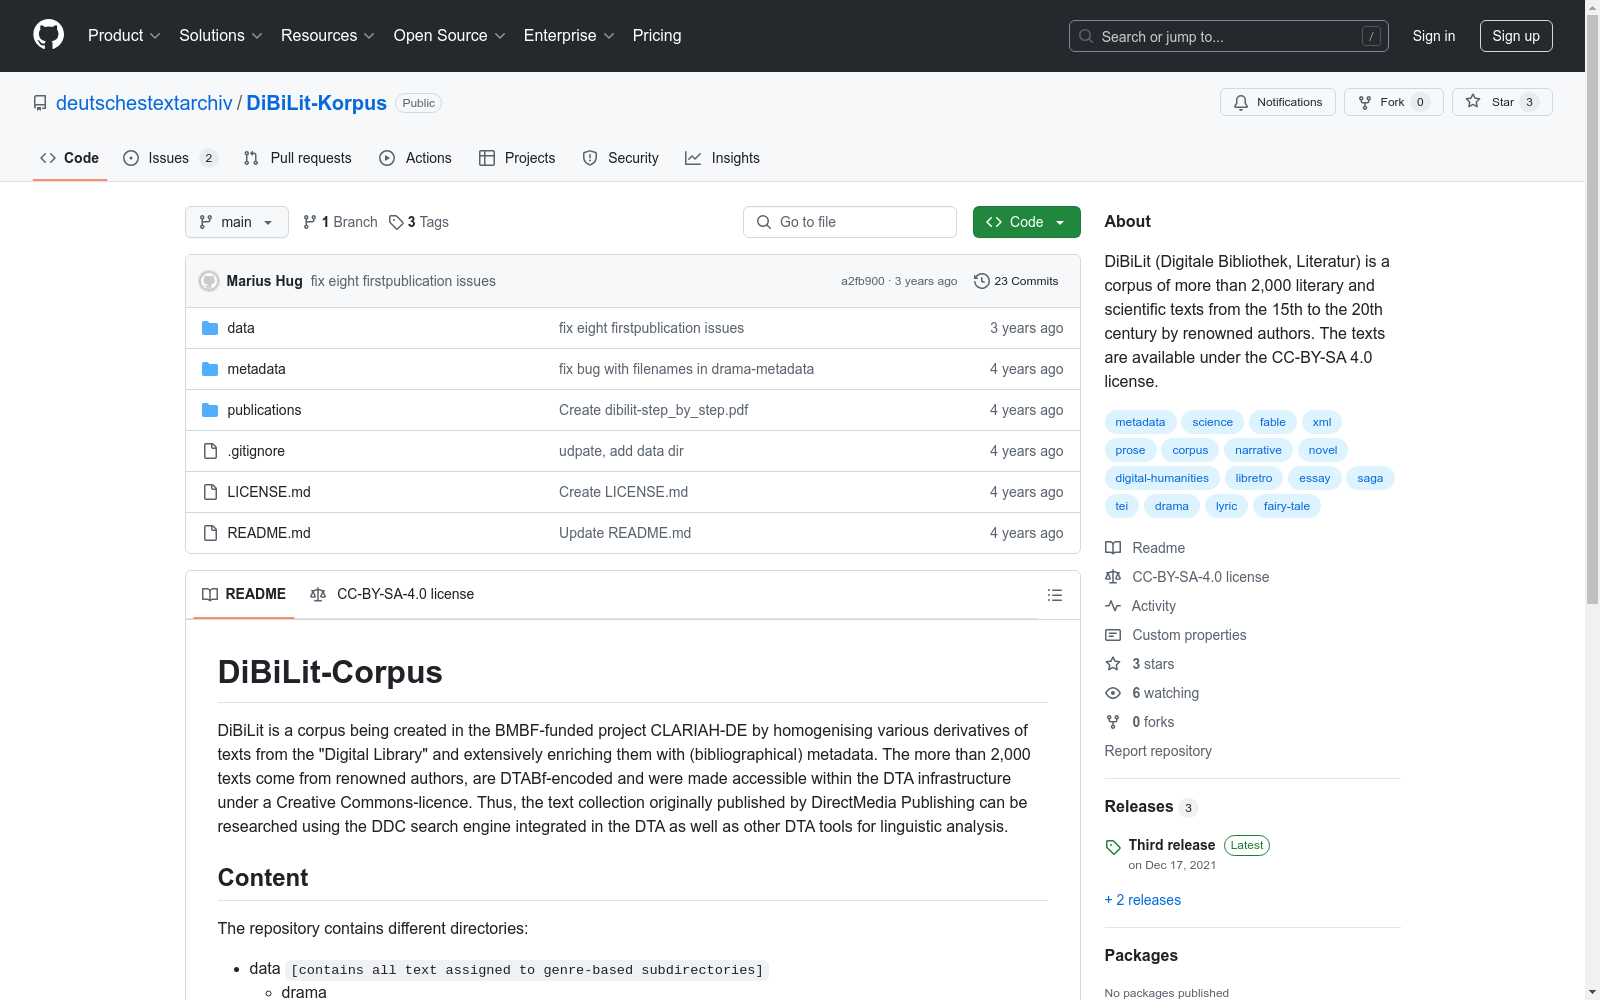
DiBiLit-Corpus
收藏资源简介:
DiBiLit是一个由BMBF资助的CLARIAH-DE项目中创建的语料库,通过统一来自数字图书馆的各种文本衍生品,并大量丰富其(书目)元数据。该语料库包含超过2000个来自知名作者的文本,采用DTABf编码,并在DTA基础设施下以Creative Commons许可证提供。这些文本最初由DirectMedia Publishing发布,可通过DTA集成的DDC搜索引擎以及其他DTA语言分析工具进行研究。
DiBiLit is a corpus created within the CLARIAH-DE project funded by the BMBF, which unifies various text derivatives from digital libraries and significantly enriches their (bibliographic) metadata. This corpus contains over 2000 texts from renowned authors, encoded in DTABf, and is made available under a Creative Commons license via the DTA infrastructure. These texts were originally published by DirectMedia Publishing and can be researched using the DTA-integrated DDC search engine as well as other DTA linguistic analysis tools.
DiBiLit-Corpus 数据集概述
数据集描述
DiBiLit-Corpus 是由 BMBF-funded 项目 CLARIAH-DE 创建的一个语料库,通过对“数字图书馆”中各种文本衍生物进行统一,并大量丰富其(书目)元数据。该数据集包含超过2,000篇来自知名作者的文本,这些文本采用DTABf编码,并在DTA基础设施下以Creative Commons许可证形式提供。用户可以通过集成在DTA中的DDC搜索引擎以及其他DTA语言分析工具对该文本集合进行研究。
数据集内容
数据集的存储库包含以下目录:
-
data:包含所有根据体裁分配的子目录中的文本。
- drama
- erzaehlungen
- essays
- fabel
- libretti
- lyrik
- prosa
- roman
- sagen_maerchen
- wissenschaft
-
metadata:包含与元数据相关的两个子目录。
- bibl:包含作为DTABf-Headers基础的书目元数据。
- headers:包含所有文本的DTABf-headers。
-
publications:包含工作流程的文档。
数据集访问
数据集可通过以下链接访问:
- Deutsches Textarchiv (DTA)/DiBiLit-Corpus: https://deutschestextarchiv.de/dibilit/