
UStAI Dataset
收藏资源简介:
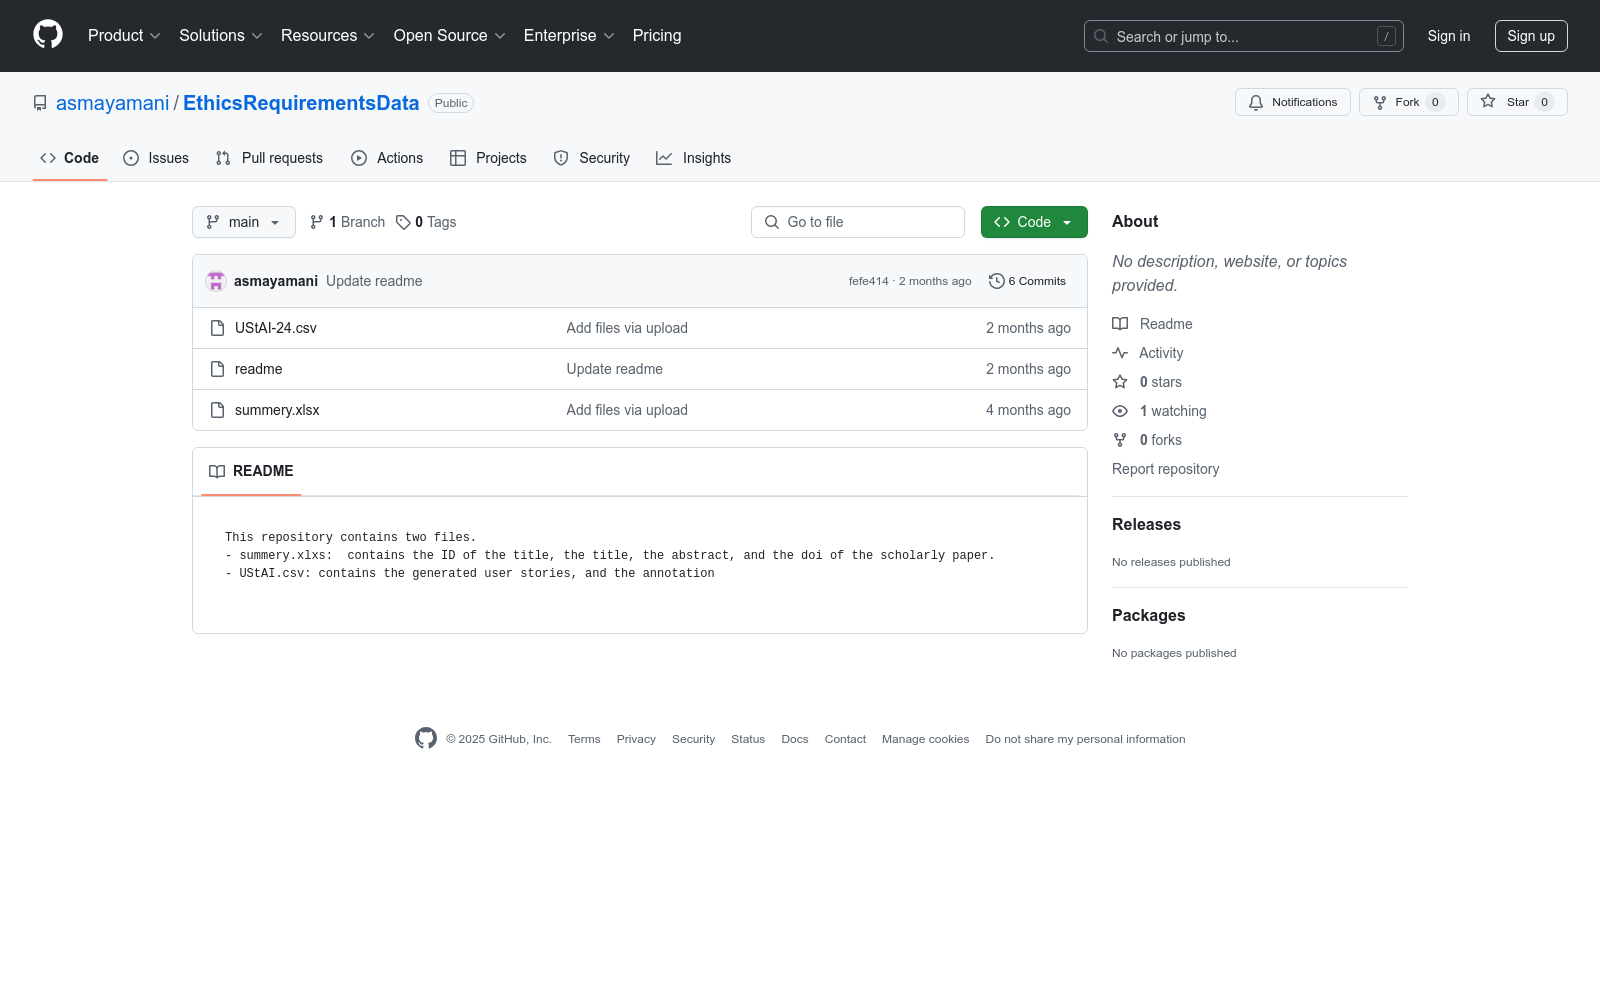
UStAI数据集是由沙特国王阿卜杜拉大学的Asma Yamani等人创建的,包含1260个用户故事,这些故事是基于学术文章摘要中的AI组件描述生成的。该数据集旨在促进AI系统需求的研究,尤其是利用大型语言模型(LLM)生成用户故事。数据集涵盖了26个领域的42篇摘要,并通过三种LLM模型生成用户故事,旨在服务于AI系统的早期需求获取阶段,同时考虑了非功能需求和伦理原则。
The UStAI Dataset was created by Asma Yamani and colleagues from King Abdullah University of Science and Technology, comprising 1260 user stories generated based on descriptions of AI components extracted from academic article abstracts. This dataset is intended to facilitate research on AI system requirements, especially the generation of user stories using Large Language Models (LLMs). The dataset covers 42 abstracts spanning 26 different domains, with the user stories generated using three distinct LLM models. It is designed to support the early requirements elicitation phase of AI systems while also accounting for non-functional requirements and ethical principles.
- 1Leveraging LLMs for User Stories in AI Systems: UStAI Dataset沙特国王阿卜杜拉大学 · 2025年


