
Lots-of-LoRAs/task670_ambigqa_question_generation
收藏官方服务:
资源简介:
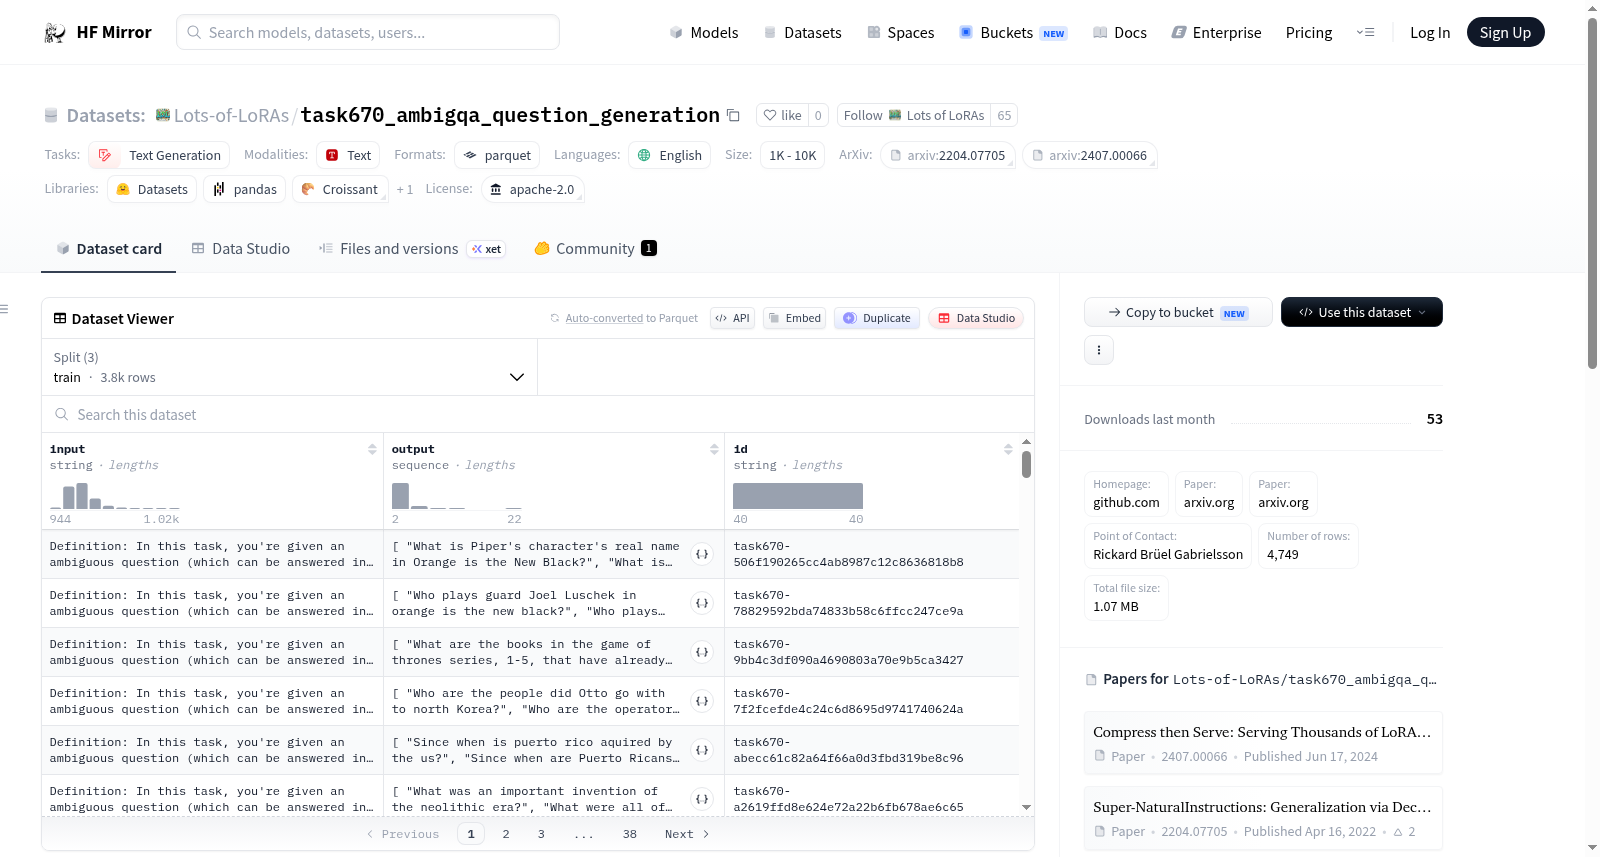
该数据集名为task670_ambigqa_question_generation,主要用于文本生成任务。数据集包含3799个训练样本、475个验证样本和475个测试样本。每个样本包含输入、输出和ID三个特征,输入和输出均为字符串类型。数据集的创建是通过众包方式完成的,语言为英语,遵循Apache 2.0许可证。数据集的相关信息可以在GitHub主页和两篇论文中找到。
The dataset, named task670_ambigqa_question_generation, is primarily used for text generation tasks. It contains 3799 training samples, 475 validation samples, and 475 test samples. Each sample includes three features: input, output, and ID, with both input and output being of string type. The dataset was created through crowdsourcing, is in English, and follows the Apache 2.0 license. Further information about the dataset can be found on its GitHub homepage and in two related papers.
提供机构:
Lots-of-LoRAs原始信息汇总
数据集概述
基本信息
- 数据集名称: task670_ambigqa_question_generation
- 任务类别: 文本生成
- 语言: 英语
- 许可证: Apache 2.0
- 数据创建者: 众包
- 注释创建者: 众包
数据集配置
- 配置名称: plain_text
数据集特征
- 输入: 字符串
- 输出: 字符串
- ID: 字符串
数据集分割
- 训练集: 3799个样本
- 验证集: 475个样本
- 测试集: 475个样本
搜集汇总
数据集介绍
背景与挑战
背景概述
该数据集是一个用于歧义问题澄清生成的文本生成任务数据集,源自Natural Instructions项目。它包含约4.75k条英文样本,每个样本给定一个歧义问题,要求生成多个澄清后具有唯一答案的问题,旨在训练模型消除问题歧义的能力。数据集采用Apache 2.0许可证,格式为parquet,适用于自然语言处理研究。
以上内容由遇见数据集搜集并总结生成


