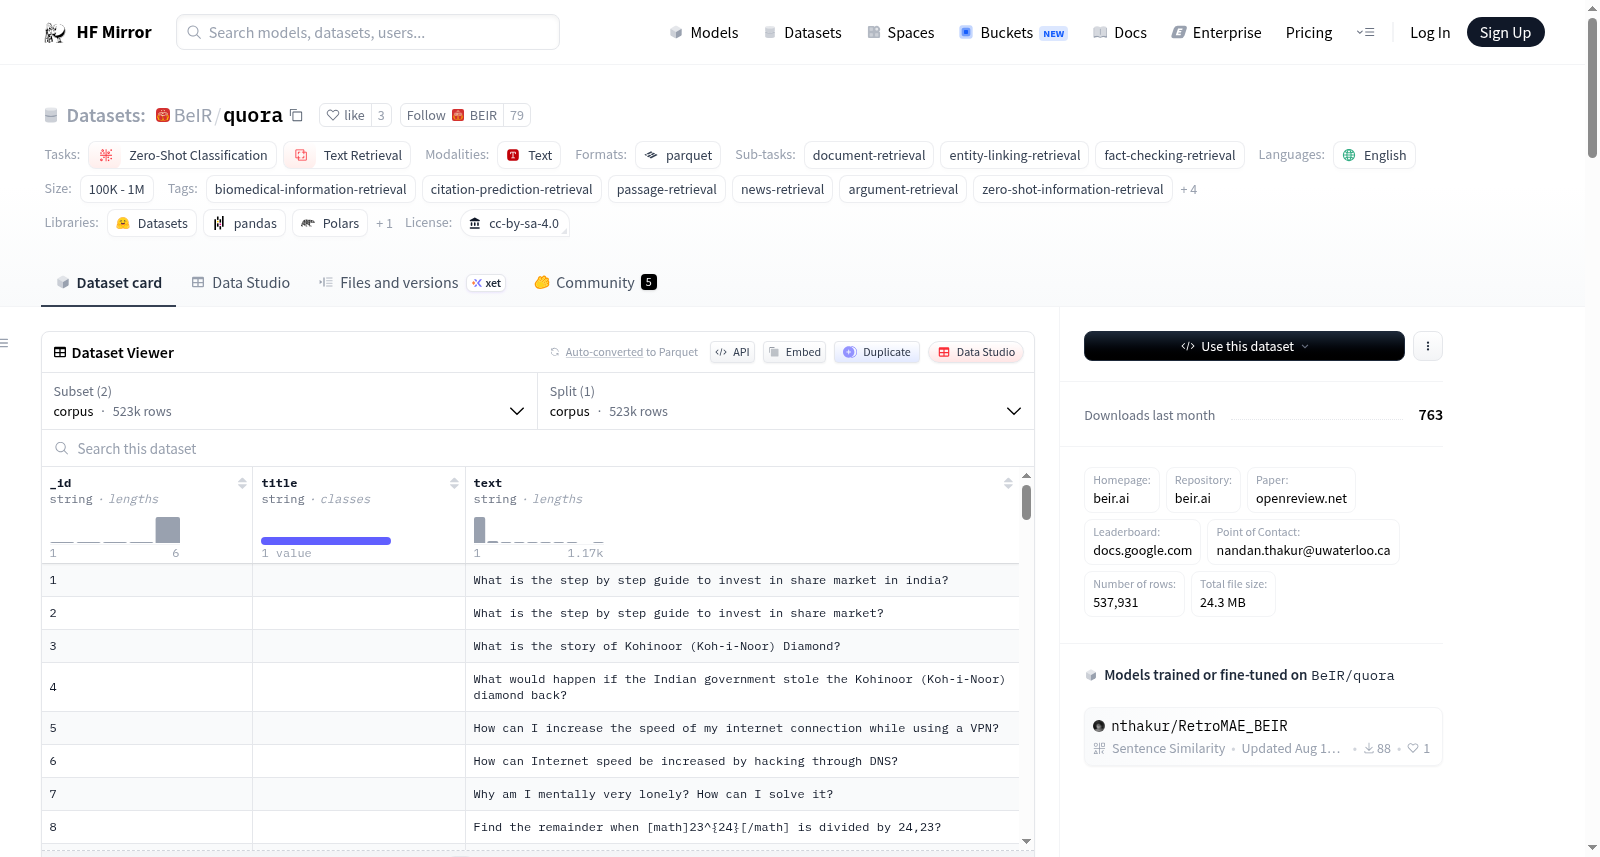
BeIR/quora
收藏资源简介:
--- language: - en license: - cc-by-sa-4.0 multilinguality: - monolingual paperswithcode_id: beir pretty_name: BEIR Benchmark task_categories: - zero-shot-classification - text-retrieval task_ids: - document-retrieval - entity-linking-retrieval - fact-checking-retrieval tags: - biomedical-information-retrieval - citation-prediction-retrieval - passage-retrieval - news-retrieval - argument-retrieval - zero-shot-information-retrieval - tweet-retrieval - question-answering-retrieval - duplication-question-retrieval - zero-shot-retrieval configs: - config_name: corpus data_files: - split: corpus path: corpus/corpus-* - config_name: queries data_files: - split: queries path: queries/queries-* dataset_info: - config_name: corpus features: - name: _id dtype: string - name: title dtype: string - name: text dtype: string splits: - name: corpus num_bytes: 23601001 num_examples: 522931 download_size: 23601001 dataset_size: 23601001 - config_name: queries features: - name: _id dtype: string - name: title dtype: string - name: text dtype: string splits: - name: queries num_bytes: 647974 num_examples: 15000 download_size: 647974 dataset_size: 647974 --- # Dataset Card for BEIR Benchmark > **`quora` is one of the datasets from the Duplicate Question Retrieval task within BEIR, measuring duplicate query retrieval for a given query.** > **NOTE: ArguAna has queries also incorporated within the corpus, so you should remove the same query_id if present within the corpus during inference (implemented in BEIR)** ## Dataset Description - **Homepage:** https://beir.ai - **Repository:** https://beir.ai - **Paper:** https://openreview.net/forum?id=wCu6T5xFjeJ - **Leaderboard:** https://docs.google.com/spreadsheets/d/1L8aACyPaXrL8iEelJLGqlMqXKPX2oSP_R10pZoy77Ns - **Point of Contact:** nandan.thakur@uwaterloo.ca ### Dataset Summary BEIR is a heterogeneous benchmark built from 18 diverse datasets representing 9 information retrieval tasks. - Fact-checking: [FEVER](http://fever.ai), [Climate-FEVER](http://climatefever.ai), [SciFact](https://github.com/allenai/scifact) - Question-Answering: [NQ](https://ai.google.com/research/NaturalQuestions), [HotpotQA](https://hotpotqa.github.io), [FiQA-2018](https://sites.google.com/view/fiqa/) - Bio-Medical IR: [TREC-COVID](https://ir.nist.gov/covidSubmit/index.html), [BioASQ](http://bioasq.org), [NFCorpus](https://www.cl.uni-heidelberg.de/statnlpgroup/nfcorpus/) - News Retrieval: [TREC-NEWS](https://trec.nist.gov/data/news2019.html), [Robust04](https://trec.nist.gov/data/robust/04.guidelines.html) - Argument Retrieval: [Touche-2020](https://webis.de/events/touche-20/shared-task-1.html), [ArguAna](tp://argumentation.bplaced.net/arguana/data) - Duplicate Question Retrieval: [Quora](https://www.quora.com/q/quoradata/First-Quora-Dataset-Release-Question-Pairs), [CqaDupstack](http://nlp.cis.unimelb.edu.au/resources/cqadupstack/) - Citation-Prediction: [SCIDOCS](https://allenai.org/data/scidocs) - Tweet Retrieval: [Signal-1M](https://research.signal-ai.com/datasets/signal1m-tweetir.html) - Entity Retrieval: [DBPedia](https://github.com/iai-group/DBpedia-Entity/) ### Languages All tasks are in English (`en`). ## Dataset Structure This dataset uses the standard BEIR retrieval layout and includes: - `corpus`: one row per document with `_id`, `title`, `text` - `queries`: one row per query with `_id`, `title`, `text` ### Data Fields - `_id` (`string`): unique identifier - `title` (`string`): title (empty string when unavailable) - `text` (`string`): document/query text ### Data Instances A high level example of any BEIR dataset: ```python corpus = { "doc1" : { "title": "Albert Einstein", "text": "Albert Einstein was a German-born theoretical physicist. who developed the theory of relativity, \ one of the two pillars of modern physics (alongside quantum mechanics). His work is also known for \ its influence on the philosophy of science. He is best known to the general public for his mass–energy \ equivalence formula E = mc2, which has been dubbed 'the world's most famous equation'. He received the 1921 \ Nobel Prize in Physics 'for his services to theoretical physics, and especially for his discovery of the law \ of the photoelectric effect', a pivotal step in the development of quantum theory." }, "doc2" : { "title": "", # Keep title an empty string if not present "text": "Wheat beer is a top-fermented beer which is brewed with a large proportion of wheat relative to the amount of \ malted barley. The two main varieties are German Weißbier and Belgian witbier; other types include Lambic (made\ with wild yeast), Berliner Weisse (a cloudy, sour beer), and Gose (a sour, salty beer)." }, } queries = { "q1" : "Who developed the mass-energy equivalence formula?", "q2" : "Which beer is brewed with a large proportion of wheat?" } qrels = { "q1" : {"doc1": 1}, "q2" : {"doc2": 1}, } ``` ### Quora Data Splits | Subset | Split | Rows | | --- | --- | ---: | | corpus | corpus | 522,931 | | queries | queries | 15,000 | ### BEIR Direct Download You can also download BEIR datasets directly (without loading through Hugging Face datasets) using the links below. | Dataset | Website | BEIR-Name | Type | Queries | Corpus | Rel D/Q | Down-load | md5 | | --- | --- | --- | --- | ---: | ---: | ---: | --- | --- | | MSMARCO | [Homepage](https://microsoft.github.io/msmarco/) | `msmarco` | `train` `dev` `test` | 6,980 | 8.84M | 1.1 | [Link](https://public.ukp.informatik.tu-darmstadt.de/thakur/BEIR/datasets/msmarco.zip) | `444067daf65d982533ea17ebd59501e4` | | TREC-COVID | [Homepage](https://ir.nist.gov/covidSubmit/index.html) | `trec-covid` | `test` | 50 | 171K | 493.5 | [Link](https://public.ukp.informatik.tu-darmstadt.de/thakur/BEIR/datasets/trec-covid.zip) | `ce62140cb23feb9becf6270d0d1fe6d1` | | NFCorpus | [Homepage](https://www.cl.uni-heidelberg.de/statnlpgroup/nfcorpus/) | `nfcorpus` | `train` `dev` `test` | 323 | 3.6K | 38.2 | [Link](https://public.ukp.informatik.tu-darmstadt.de/thakur/BEIR/datasets/nfcorpus.zip) | `a89dba18a62ef92f7d323ec890a0d38d` | | BioASQ | [Homepage](http://bioasq.org) | `bioasq` | `train` `test` | 500 | 14.91M | 8.05 | No | [How to Reproduce?](https://github.com/UKPLab/beir/blob/main/examples/dataset#2-bioasq) | | NQ | [Homepage](https://ai.google.com/research/NaturalQuestions) | `nq` | `train` `test` | 3,452 | 2.68M | 1.2 | [Link](https://public.ukp.informatik.tu-darmstadt.de/thakur/BEIR/datasets/nq.zip) | `d4d3d2e48787a744b6f6e691ff534307` | | HotpotQA | [Homepage](https://hotpotqa.github.io) | `hotpotqa` | `train` `dev` `test` | 7,405 | 5.23M | 2.0 | [Link](https://public.ukp.informatik.tu-darmstadt.de/thakur/BEIR/datasets/hotpotqa.zip) | `f412724f78b0d91183a0e86805e16114` | | FiQA-2018 | [Homepage](https://sites.google.com/view/fiqa/) | `fiqa` | `train` `dev` `test` | 648 | 57K | 2.6 | [Link](https://public.ukp.informatik.tu-darmstadt.de/thakur/BEIR/datasets/fiqa.zip) | `17918ed23cd04fb15047f73e6c3bd9d9` | | Signal-1M(RT) | [Homepage](https://research.signal-ai.com/datasets/signal1m-tweetir.html) | `signal1m` | `test` | 97 | 2.86M | 19.6 | No | [How to Reproduce?](https://github.com/UKPLab/beir/blob/main/examples/dataset#4-signal-1m) | | TREC-NEWS | [Homepage](https://trec.nist.gov/data/news2019.html) | `trec-news` | `test` | 57 | 595K | 19.6 | No | [How to Reproduce?](https://github.com/UKPLab/beir/blob/main/examples/dataset#1-trec-news) | | ArguAna | [Homepage](http://argumentation.bplaced.net/arguana/data) | `arguana` | `test` | 1,406 | 8.67K | 1.0 | [Link](https://public.ukp.informatik.tu-darmstadt.de/thakur/BEIR/datasets/arguana.zip) | `8ad3e3c2a5867cdced806d6503f29b99` | | Touche-2020 | [Homepage](https://webis.de/events/touche-20/shared-task-1.html) | `webis-touche2020` | `test` | 49 | 382K | 19.0 | [Link](https://public.ukp.informatik.tu-darmstadt.de/thakur/BEIR/datasets/webis-touche2020.zip) | `46f650ba5a527fc69e0a6521c5a23563` | | CQADupstack | [Homepage](http://nlp.cis.unimelb.edu.au/resources/cqadupstack/) | `cqadupstack` | `test` | 13,145 | 457K | 1.4 | [Link](https://public.ukp.informatik.tu-darmstadt.de/thakur/BEIR/datasets/cqadupstack.zip) | `4e41456d7df8ee7760a7f866133bda78` | | Quora | [Homepage](https://www.quora.com/q/quoradata/First-Quora-Dataset-Release-Question-Pairs) | `quora` | `dev` `test` | 10,000 | 523K | 1.6 | [Link](https://public.ukp.informatik.tu-darmstadt.de/thakur/BEIR/datasets/quora.zip) | `18fb154900ba42a600f84b839c173167` | | DBPedia | [Homepage](https://github.com/iai-group/DBpedia-Entity/) | `dbpedia-entity` | `dev` `test` | 400 | 4.63M | 38.2 | [Link](https://public.ukp.informatik.tu-darmstadt.de/thakur/BEIR/datasets/dbpedia-entity.zip) | `c2a39eb420a3164af735795df012ac2c` | | SCIDOCS | [Homepage](https://allenai.org/data/scidocs) | `scidocs` | `test` | 1,000 | 25K | 4.9 | [Link](https://public.ukp.informatik.tu-darmstadt.de/thakur/BEIR/datasets/scidocs.zip) | `38121350fc3a4d2f48850f6aff52e4a9` | | FEVER | [Homepage](http://fever.ai) | `fever` | `train` `dev` `test` | 6,666 | 5.42M | 1.2 | [Link](https://public.ukp.informatik.tu-darmstadt.de/thakur/BEIR/datasets/fever.zip) | `5a818580227bfb4b35bb6fa46d9b6c03` | | Climate-FEVER | [Homepage](http://climatefever.ai) | `climate-fever` | `test` | 1,535 | 5.42M | 3.0 | [Link](https://public.ukp.informatik.tu-darmstadt.de/thakur/BEIR/datasets/climate-fever.zip) | `8b66f0a9126c521bae2bde127b4dc99d` | | SciFact | [Homepage](https://github.com/allenai/scifact) | `scifact` | `train` `test` | 300 | 5K | 1.1 | [Link](https://public.ukp.informatik.tu-darmstadt.de/thakur/BEIR/datasets/scifact.zip) | `5f7d1de60b170fc8027bb7898e2efca1` | | Robust04 | [Homepage](https://trec.nist.gov/data/robust/04.guidelines.html) | `robust04` | `test` | 249 | 528K | 69.9 | No | [How to Reproduce?](https://github.com/UKPLab/beir/blob/main/examples/dataset#3-robust04) | ## Citation Information ```bibtex @inproceedings{ thakur2021beir, title={{BEIR}: A Heterogeneous Benchmark for Zero-shot Evaluation of Information Retrieval Models}, author={Nandan Thakur and Nils Reimers and Andreas R{\"u}ckl{\'e} and Abhishek Srivastava and Iryna Gurevych}, booktitle={Thirty-fifth Conference on Neural Information Processing Systems Datasets and Benchmarks Track (Round 2)}, year={2021}, url={https://openreview.net/forum?id=wCu6T5xFjeJ} } ```
数据集卡片 for BEIR Benchmark
数据集描述
数据集摘要
BEIR 是一个异构基准,由 18 个不同数据集组成,代表 9 种信息检索任务:
- 事实检查:FEVER, Climate-FEVER, SciFact
- 问答:NQ, HotpotQA, FiQA-2018
- 生物医学信息检索:TREC-COVID, BioASQ, NFCorpus
- 新闻检索:TREC-NEWS, Robust04
- 论点检索:Touche-2020, ArguAna
- 重复问题检索:Quora, CqaDupstack
- 引文预测:SCIDOCS
- 推文检索:Signal-1M
- 实体检索:DBPedia
所有这些数据集都已预处理,可供实验使用。
支持的任务和排行榜
数据集支持排行榜,评估模型在任务特定指标(如 F1 或 EM)以及从 Wikipedia 检索支持信息的能力。
语言
所有任务均为英语 (en)。
数据集结构
所有 BEIR 数据集必须包含语料库、查询和 qrels(相关性判断文件)。它们必须采用以下格式:
corpus文件:一个.jsonl文件(jsonlines),包含一个字典列表,每个字典有三个字段_id(唯一文档标识符)、title(文档标题,可选)和text(文档段落或段落)。queries文件:一个.jsonl文件(jsonlines),包含一个字典列表,每个字典有两个字段_id(唯一查询标识符)和text(查询文本)。qrels文件:一个.tsv文件(制表符分隔),包含三列,即query-id、corpus-id和score(查询和文档的相关性判断)。
数据实例
一个高层次的 BEIR 数据集示例:
python corpus = { "doc1": { "title": "Albert Einstein", "text": "Albert Einstein was a German-born theoretical physicist..." }, "doc2": { "title": "", "text": "Wheat beer is a top-fermented beer which is brewed with a large proportion of wheat..." }, }
queries = { "q1": "Who developed the mass-energy equivalence formula?", "q2": "Which beer is brewed with a large proportion of wheat?" }
qrels = { "q1": {"doc1": 1}, "q2": {"doc2": 1}, }
数据字段
所有配置的示例具有以下特征:
语料库
corpus:一个dict特征,表示文档标题和段落文本,由以下部分组成:_id:一个string特征,表示唯一文档 ID。title:一个string特征,表示文档标题。text:一个string特征,表示文档文本。
查询
queries:一个dict特征,表示查询,由以下部分组成:_id:一个string特征,表示唯一查询 ID。text:一个string特征,表示查询文本。
Qrels
qrels:一个dict特征,表示查询文档相关性判断,由以下部分组成:_id:一个string特征,表示查询 ID。_id:一个string特征,表示文档 ID。score:一个int32特征,表示查询和文档的相关性判断。
数据分割
| 数据集 | 网站 | BEIR 名称 | 类型 | 查询数量 | 语料库大小 | 相关文档/查询 | 下载链接 | md5 |
|---|---|---|---|---|---|---|---|---|
| MSMARCO | Homepage | msmarco |
train<br>dev<br>test |
6,980 | 8.84M | 1.1 | Link | 444067daf65d982533ea17ebd59501e4 |
| TREC-COVID | Homepage | trec-covid |
test |
50 | 171K | 493.5 | Link | ce62140cb23feb9becf6270d0d1fe6d1 |
| NFCorpus | Homepage | nfcorpus |
train<br>dev<br>test |
323 | 3.6K | 38.2 | Link | a89dba18a62ef92f7d323ec890a0d38d |
| BioASQ | Homepage | bioasq |
train<br>test |
500 | 14.91M | 8.05 | No | How to Reproduce? |
| NQ | Homepage | nq |
train<br>test |
3,452 | 2.68M | 1.2 | Link | d4d3d2e48787a744b6f6e691ff534307 |
| HotpotQA | Homepage | hotpotqa |
train<br>dev<br>test |
7,405 | 5.23M | 2.0 | Link | f412724f78b0d91183a0e86805e16114 |
| FiQA-2018 | Homepage | fiqa |
train<br>dev<br>test |
648 | 57K | 2.6 | Link | 17918ed23cd04fb15047f73e6c3bd9d9 |
| Signal-1M(RT) | Homepage | signal1m |
test |
97 | 2.86M | 19.6 | No | How to Reproduce? |
| TREC-NEWS | Homepage | trec-news |
test |
57 | 595K | 19.6 | No | How to Reproduce? |
| ArguAna | Homepage | arguana |
test |
1,406 | 8.67K | 1.0 | Link | 8ad3e3c2a5867cdced806d6503f29b99 |
| Touche-2020 | Homepage | webis-touche2020 |
test |
49 | 382K | 19.0 | Link | 46f660ba5a527fc69e0a6521c5a23563 |
| CQADupstack | Homepage | cqadupstack |
test |
13,145 | 457K | 1.4 | Link | 4e41456d7df8ee7760a7f866133bda78 |
| Quora | Homepage | quora |
dev<br>test |
10,000 | 523K | 1.6 | Link | 18fb154900ba42a600f84b839c173167 |
| DBPedia | Homepage | dbpedia-entity |
dev<br>test |
400 | 4.63M | 38.2 | Link | c2a39eb420a3164af735795df012ac2c |
| SCIDOCS | Homepage | scidocs |
test |
1,000 | 25K | 4.9 | Link | 38121350fc3a4d2f48850f6aff52e4a9 |
| FEVER | Homepage | fever |
train<br>dev<br>test |
6,666 | 5.42M | 1.2 | Link | 5a818580227bfb4b35bb6fa46d9b6c03 |
| Climate-FEVER | Homepage | climate-fever |
test |
1,535 | 5.42M | 3.0 | Link | 8b66f0a9126c521bae2bde127b4dc99d |
| SciFact | Homepage | scifact |
train<br>test |
300 | 5K | 1.1 | Link | 5f7d1de60b170fc8027bb7898e2efca1 |
| Robust04 | Homepage | robust04 |
test |
249 | 528K | 69.9 | No | How to Reproduce? |
数据集创建
策划理由
[需要更多信息]
源数据
初始数据收集和规范化
[需要更多信息]
源语言生产者是谁?
[需要更多信息]
注释
注释过程
[需要更多信息]
注释者是谁?
[需要更多信息]
个人和敏感信息
[需要更多信息]
使用数据的注意事项
数据集的社会影响
[需要更多信息]
偏见的讨论
[需要更多信息]
其他已知限制
[需要更多信息]
附加信息
数据集策展人
[需要更多信息]
许可信息
[需要更多信息]
引用信息
引用为:
@inproceedings{ thakur2021beir, title={{BEIR}: A Heterogeneous Benchmark for Zero-shot Evaluation of Information Retrieval Models}, author={Nandan Thakur and Nils Reimers and Andreas R{"u}ckl{e} and Abhishek Srivastava and Iryna Gurevych}, booktitle={Thirty-fifth Conference on Neural Information Processing Systems Datasets and Benchmarks Track (Round 2)}, year={2021}, url={https://openreview.net/forum?id=wCu6T5xFjeJ} }
贡献
感谢 @Nthakur20 添加此数据集。