ycbench
收藏资源简介:
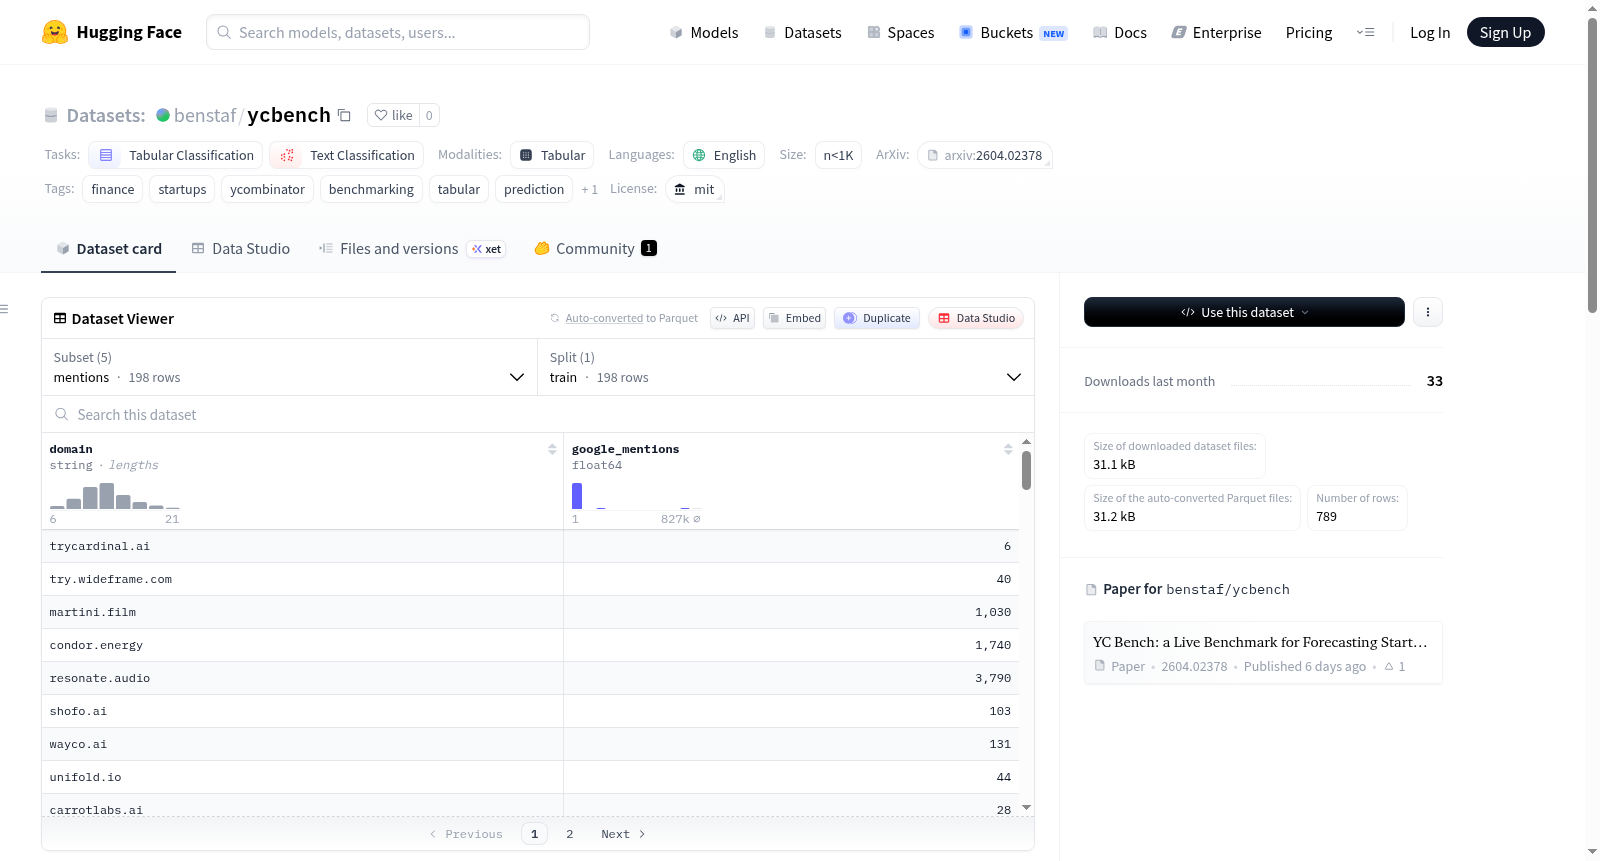
YCbench 是一个用于预测 Y Combinator 批次中初创公司短期表现的实时基准数据集。该数据集由 Mostapha Benhenda 在论文《YC Bench: a Live Benchmark for Forecasting Startup Outperformance in Y Combinator Batches》中提出,专注于 W26 批次的 196 家公司。数据集提供了结构化的公共信号,用于评估预测哪些初创公司将在短期内(直到 Demo Day)超越同行的模型。性能通过结合牵引信号和网络可见性的“Pre-Demo Day Score”来衡量。数据集包含多个配置:`startups`(基本初创公司信息)、`traction`(牵引指标)、`scores`(预演示日分数和速度)、`mentions`(Google/网络提及计数)和 `mentions_early`(早期提及数据)。数据集适用于表格分类和文本分类任务,规模小于 1K 样本。
YCbench is a live benchmark dataset for predicting the short-term performance of startups in Y Combinator batches. It was proposed by Mostapha Benhenda in the paper "YC Bench: a Live Benchmark for Forecasting Startup Outperformance in Y Combinator Batches", focusing on 196 startups from the W26 batch. This dataset provides structured public signals for evaluating models that forecast which startups will outperform their peers in the short term (until Demo Day). Performance is measured using the "Pre-Demo Day Score", which combines traction metrics and network visibility. The dataset includes multiple configurations: `startups` (basic startup information), `traction` (traction metrics), `scores` (Pre-Demo Day scores and velocity), `mentions` (Google/web mention counts), and `mentions_early` (early mention data). This dataset is applicable to tabular classification and text classification tasks, with a sample size of fewer than 1,000.
YCbench数据集概述
数据集基本信息
- 数据集名称:YCbench
- 数据集标识:ycbench
- 主要语言:英语 (en)
- 许可证:MIT
- 标签:金融、初创公司、Y Combinator、基准测试、表格数据、预测、风险投资
- 任务类别:表格分类、文本分类
- 数据规模:小于1K样本 (n<1K)
数据集简介
YCbench是一个用于预测Y Combinator批次内初创公司短期(截止至Demo Day)表现是否优于同批其他公司的实时基准测试数据集。该数据集在论文《YC Bench: a Live Benchmark for Forecasting Startup Outperformance in Y Combinator Batches》中被提出。
数据集内容与结构
数据集专注于Y Combinator的W26批次(包含196家公司),提供了结构化的公开信号。表现通过一个结合了增长信号和网络可见度的Pre-Demo Day Score来衡量。
数据集包含以下配置(configs),每个配置对应一个CSV文件:
| 配置名称 | 数据文件 | 描述 |
|---|---|---|
startups |
yc_w26_startups.csv |
初创公司基本信息 |
traction |
yc_w26_traction.csv |
增长指标 |
scores |
yc_w26_pre_demo_scores.csv |
Demo Day前的得分与速度 |
mentions |
yc_mentions.csv |
Google/网络提及次数 |
mentions_early |
yc_mentions_early.csv |
早期阶段提及数据 |
数据加载方式
使用datasets库加载
python from datasets import load_dataset startups = load_dataset("benstaf/ycbench", "startups") scores = load_dataset("benstaf/ycbench", "scores") mentions = load_dataset("benstaf/ycbench", "mentions")
使用pandas直接加载(简易方式)
python import pandas as pd df = pd.read_csv("hf://datasets/benstaf/ycbench/yc_w26_pre_demo_scores.csv")
相关资源链接
- 论文:https://huggingface.co/papers/2604.02378
- 实时基准测试网站:https://ycbench.com/
- GitHub仓库:https://github.com/benstaf/ycbench