
ALPBench
收藏资源简介:
ALPBench是由慕尼黑路德维希大学MCML创建的一个综合性的主动学习基准数据集,包含86个真实世界的表格分类数据集,涵盖二分类和多分类问题。该数据集通过精心设计,确保了评估的可重复性,包括精确的数据集分割和算法超参数设置。创建过程中,数据集结合了多种学习算法和查询策略,旨在通过主动学习提高机器学习算法的效率和性能。ALPBench的应用领域广泛,特别适用于需要有限标注数据资源的场景,如医疗、金融和制造等行业,旨在通过优化数据点选择策略,提升模型在有限数据条件下的泛化能力。
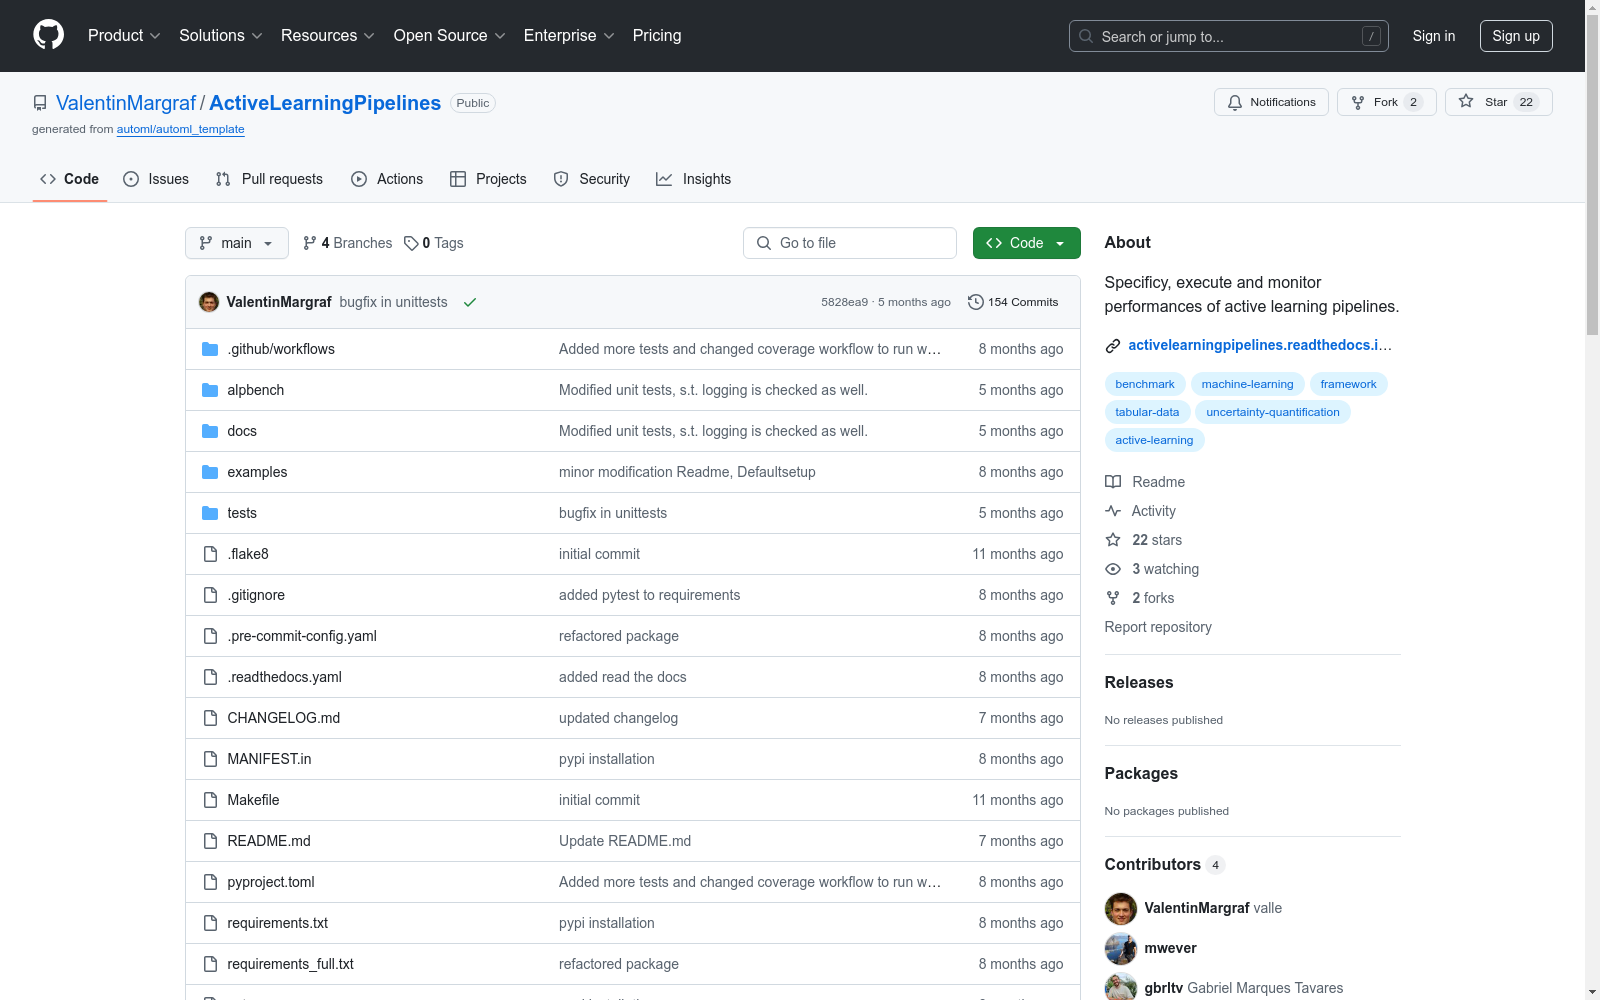
ALPBench is a comprehensive active learning benchmark dataset developed by the MCML (Munich Center for Machine Learning) at Ludwig Maximilian University of Munich. It includes 86 real-world tabular classification datasets covering both binary classification and multi-class classification tasks. This dataset is meticulously designed to ensure evaluation reproducibility, including precise dataset splits and algorithm hyperparameter settings. During its creation, a diverse set of learning algorithms and query strategies have been integrated, aiming to improve the efficiency and performance of machine learning algorithms through active learning. ALPBench has a wide range of application scenarios, and is particularly suitable for use cases with limited labeled data resources such as healthcare, finance, and manufacturing industries. Its core objective is to enhance the generalization ability of models under limited data conditions by optimizing data point selection strategies.
ALPBench: A Benchmark for Active Learning Pipelines on Tabular Data
ALPBench 是一个用于指定、执行和性能监控的 Python 包,专注于包含学习算法和查询策略的主动学习管道(ALP)在真实世界表格分类任务中的应用。该包内置了确保评估可重复性的措施,保存了确切的训练集划分和使用的算法的超参数设置。ALPBench 包含 86 个真实世界的表格分类数据集和 5 种主动学习设置,总共产生 430 个主动学习问题。此外,该基准允许轻松扩展,例如实现自己的学习算法和/或查询策略,并与现有方法进行比较。
安装
ALPBench 适用于 Python 3.10 及以上版本。
bash
通过 pip 安装基本包:
pip install alpbench
或者通过 pip 安装完整包:
pip install alpbench[full]
或者从源代码安装:
git clone https://github.com/ValentinMargraf/ActiveLearningPipelines.git cd ActiveLearningPipelines conda create --name alpbench python=3.10 conda activate alpbench
安装用于使用的包(不包括 TabNet 和 TabPFN):
pip install -r requirements.txt
安装用于使用的包(包括 TabNet 和 TabPFN):
pip install -r requirements_full.txt
快速开始
您可以通过不同的方式使用 ALPBench。已经存在许多学习器和查询策略,可以通过它们的名称访问,如下面的最小示例所示。在 ALP.pipeline 模块中,您还可以实现自己的(新的)查询策略。
拟合一个主动学习管道
拟合一个 ALP 在 openmlid 为 31 的数据集上,使用随机森林和边缘采样。您可以在 examples/ 中找到类似的示例代码片段。
python from sklearn.metrics import accuracy_score from alpbench.benchmark.BenchmarkConnector import DataFileBenchmarkConnector from alpbench.evaluation.experimenter.DefaultSetup import ensure_default_setup from alpbench.pipeline.ALPEvaluator import ALPEvaluator
创建基准连接器并建立数据库连接
benchmark_connector = DataFileBenchmarkConnector()
加载一些默认设置和算法选择
ensure_default_setup(benchmark_connector)
evaluator = ALPEvaluator(benchmark_connector=benchmark_connector, setting_name="small", openml_id=31, query_strategy_name="margin", learner_name="rf_gini") alp = evaluator.fit()
拟合 / 预测并评估预测结果
X_test, y_test = evaluator.get_test_data() y_hat = alp.predict(X=X_test) print("最终测试准确率", accuracy_score(y_test, y_hat))
输出
最终测试准确率 0.7181818181818181
- 1ALPBench: A Benchmark for Active Learning Pipelines on Tabular Data慕尼黑路德维希大学MCML · 2024年


