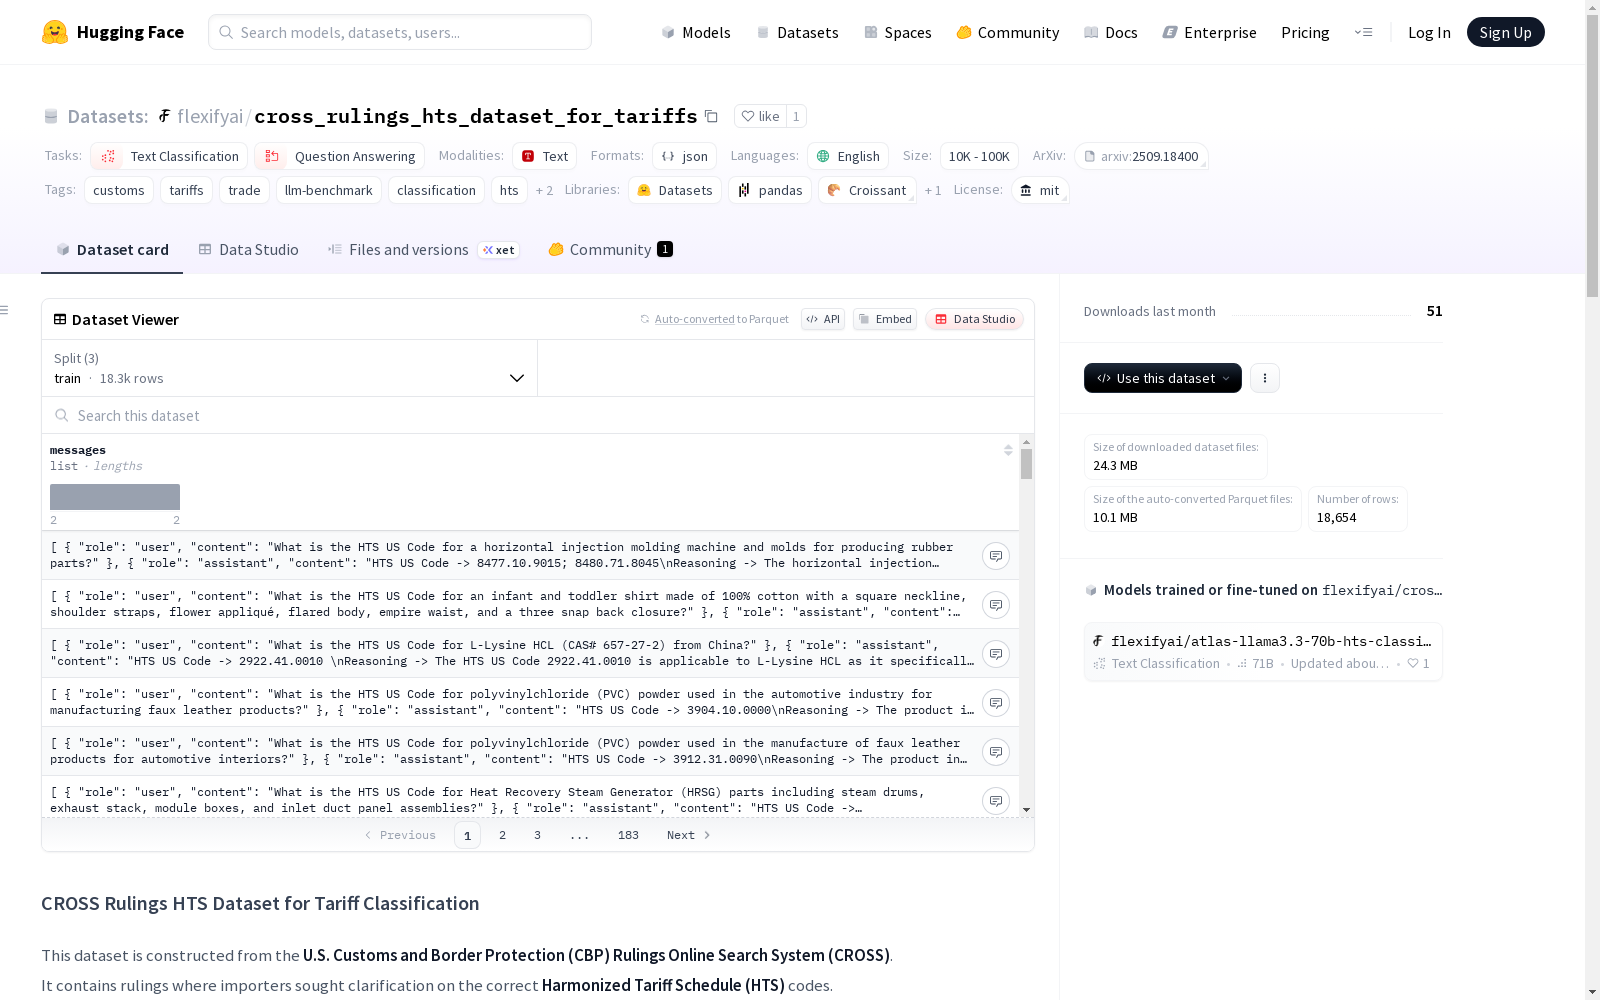
HTS CROSS Rulings Dataset
收藏资源简介:
该数据集为全球贸易中的商品分类提供了一个基准,来源于美国海关在线搜索系统(CROSS)。数据集包含18731个案例,涵盖了2992个独特的HTS代码,跨越了广泛的商品类别。数据集被分为训练集、验证集和测试集,用于评估大型语言模型在关税分类任务上的表现。数据集的创建旨在解决全球贸易中的商品分类问题,通过提供一个大规模的、真实世界的基准来促进机器学习社区的研究。
This dataset serves as a benchmark for commodity classification in global trade, sourced from the U.S. Customs Online Search System (CROSS). It contains 18,731 samples, covering 2,992 unique HTS codes and spanning a wide range of commodity categories. The dataset is split into training, validation, and test sets, which are used to evaluate the performance of large language models on tariff classification tasks. It was developed to address the commodity classification problem in global trade, providing a large-scale, real-world benchmark to facilitate research within the machine learning community.
CROSS Rulings HTS 数据集概述
数据集基本信息
- 许可证: MIT
- 语言: 英语
- 数据集名称: CROSS Rulings HTS Dataset
- 数据规模: 10K < n < 100K
- 标签: 海关、关税、贸易、LLM基准、分类、HTS、机器学习、全球贸易
- 任务类别: 文本分类、问答
数据集来源与内容
- 数据来源于美国海关与边境保护局裁决在线搜索系统。
- 包含进口商寻求澄清正确协调关税表代码的裁决。
- 数据总量: 18,731条裁决,涵盖2,992个唯一HTS代码。
- 数据划分: 训练集18,254条、验证集200条、测试集200条。
- 数据结构: 采用LLM可训练格式,包含产品描述、推理路径和正确HTS代码。
任务目标
- 支持HTS代码预测任务:
- 10位美国特定HTS代码分类
- 6位全球协调HS代码分类
- 适用于文本分类、问答和结构化输出推理任务。
基准测试结果
在200个保留CROSS裁决上评估多个模型性能:
| 模型 | 10位准确率 | 6位准确率 | 平均正确位数 |
|---|---|---|---|
| GPT-5-Thinking | 25.0% | 55.5% | 5.61 |
| Gemini-2.5-Pro-Thinking | 13.5% | 31.0% | 2.92 |
| DeepSeek-R1 (05/28) | 2.5% | 26.5% | 3.24 |
| GPT-OSS-120B | 1.5% | 8.0% | 2.58 |
| LLaMA-3.3-70B (基线) | 2.1% | 20.7% | 3.31 |
| Atlas (微调LLaMA) | 40.0% | 57.5% | 6.30 |
引用信息
- 论文标题: ATLAS: Benchmarking and Adapting LLMs for Global Trade via Harmonized Tariff Code Classification
- 作者: Pritish Yuvraj, Siva Devarakonda
- 年份: 2025
- arXiv编号: 2509.18400
- 论文链接: https://arxiv.org/abs/2509.18400
作者信息
- Pritish Yuvraj (Flexify.AI)
- Siva Devarakonda (Flexify.AI)
致谢
- 数据源自美国海关裁决在线搜索系统:https://rulings.cbp.gov/
- 协调关税表参考:https://hts.usitc.gov/