
HuMo100M
收藏资源简介:
HuMo100M数据集是目前最大且最全面的人类运动数据集,包含超过500万个自收集的运动序列、1亿个多任务指令实例,以及详细的身体部位级标注,填补了现有数据集的空白。数据集通过创新的运动连接方法生成长期运动序列,并利用视觉线索作为特别有益于网络收集运动的弱监督,允许VLMM通过视觉-文本上下文对齐进行学习。HuMo100M的创建过程充分考虑了数据集的可靠性和多样性,旨在为人类运动生成技术的研究和应用提供有力支持。
The HuMo100M dataset is currently the largest and most comprehensive human motion dataset to date. It comprises over 5 million self-collected motion sequences, 100 million multi-task instruction instances, and detailed body-part-level annotations, filling the gaps in existing datasets. The dataset generates long-term motion sequences through innovative motion connection methodologies, and employs visual cues as weak supervision that is particularly beneficial for web-collected motion data, enabling VLMMs to learn via vision-text context alignment. The construction of HuMo100M fully considers the dataset's reliability and diversity, aiming to provide robust support for research and applications of human motion generation technologies.
数据集概述:Being-M0.5
基本信息
- 数据集名称: Being-M0.5
- 相关论文: A Real-Time Controllable Vision-Language-Motion Model (ICCV 2025)
- 作者: Bin Cao, Sipeng Zheng, Ye Wang, Lujie Xia, Qianshan Wei, Qin Jin, Jing Liu, Zongqing Lu
- 机构: 中国科学院自动化研究所、北京大学、中国人民大学等
- 代码: arXiv Code
数据集特点
- 基础数据: 基于百万级数据集HuMo100M
- 规模: 包含超过500万自收集动作和1亿多任务指令实例
- 标注: 提供详细的部位级描述
- 创新点: 提出部位感知残差量化技术用于动作标记化
技术细节
- 模型架构:
- 基于7B参数的LLM主干
- 使用SigLIP+2MLP进行视觉编码和投影
- 采用慢-快策略和部位感知残差量化
- 控制能力:
- 支持随机指令、初始姿势、长期生成
- 处理未见动作和部位感知动作控制
实验验证
- 测试基准:
- HumanML3D
- I2M任务(使用HuMo-I2M测试床)
- I2PM任务(使用HuMo-I2PM测试床)
- 性能: 在九个不同基准测试中达到state-of-the-art
- 推理速度: 提供多种GPU的推理速度数据
示例应用
- Instruct-to-PartMotion可视化结果
- Instruct-to-LongMotion可视化结果
相关引用
bibtex @inproceedings{cao2025real, title={A Real-Time Controllable Vision-Language-Motion Model}, author={Cao, Bin and Zheng, Sipeng and Wang, Ye and Xia, Lujie and Wei, Qianshan and Jin, Qin and Liu, Jing and Lu, Zongqing}, booktitle={ICCV}, year={2025} }
@inproceedings{wang2025scaling, title={Scaling Large Motion Models with Million-Level Human Motions}, author={Wang, Ye and Zheng, Sipeng and Cao, Bin and Wei, Qianshan and Zeng, Weishuai and Jin, Qin and Lu, Zongqing}, booktitle={ICML}, year={2025} }
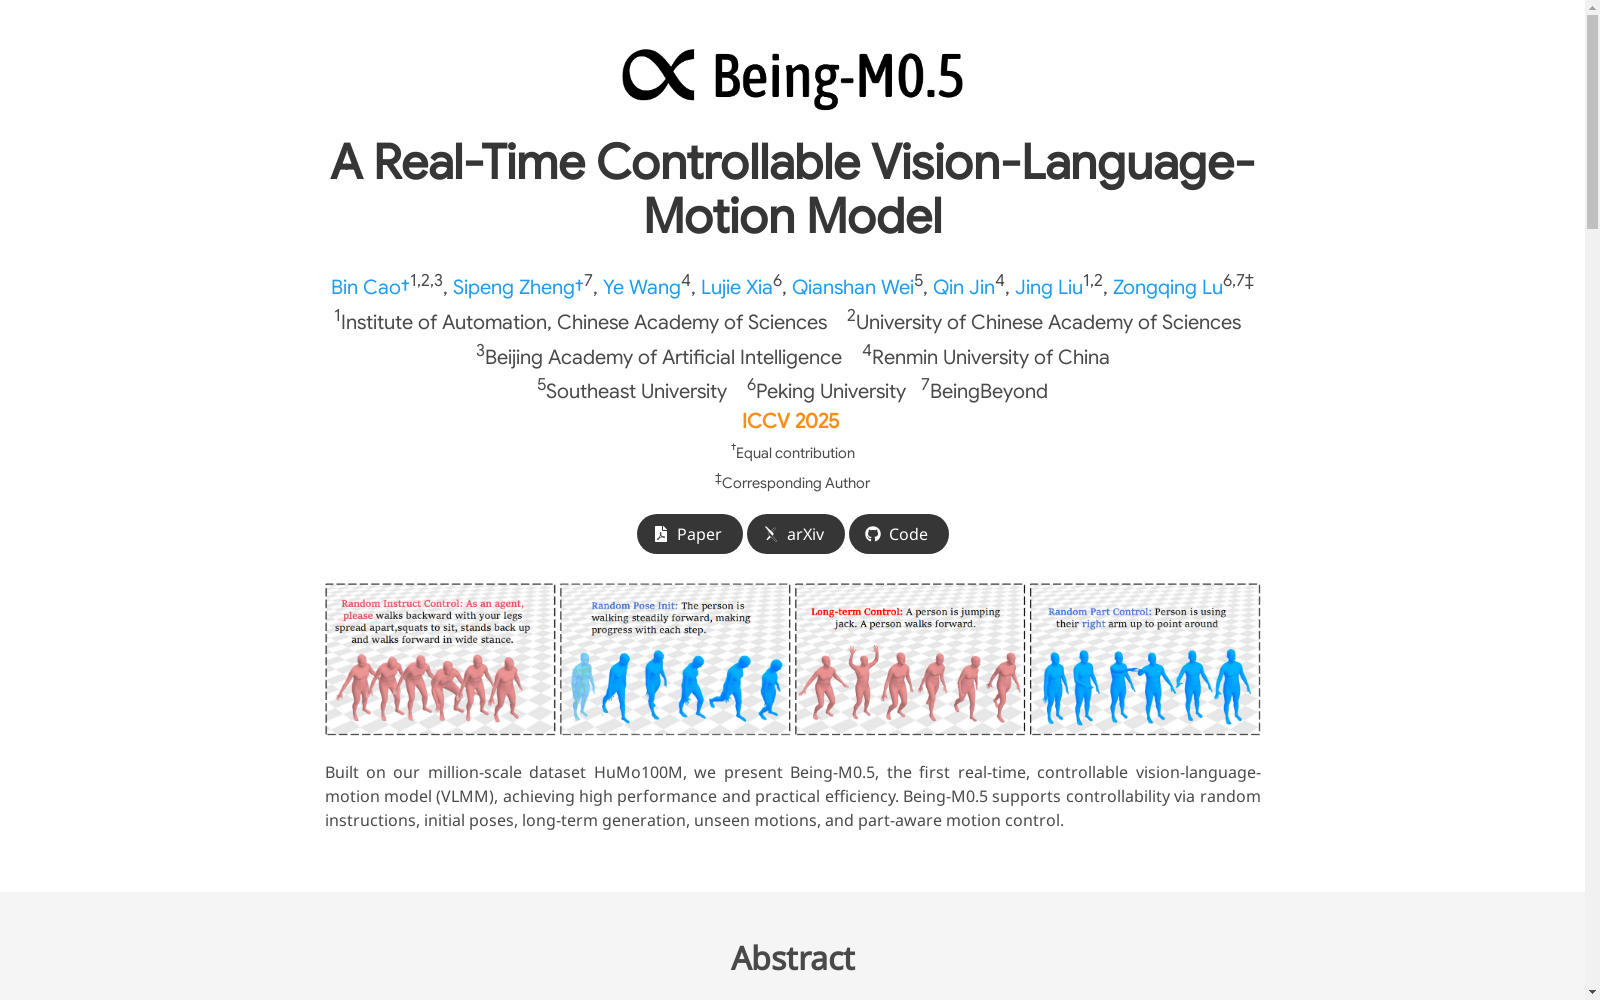
- 1Being-M0.5: A Real-Time Controllable Vision-Language-Motion Model中国科学院自动化研究所, 中国科学院大学, 北京人工智能研究院, 北京大学, 人民大学, 东南大学, BeingBeyond · 2025年


