Harvard-DCML/tis-dolci-subset-datasets-gtr-t5-base
收藏资源简介:
--- dataset_info: - config_name: embed_rr_bbh_10000 features: - name: id dtype: string - name: messages list: - name: content dtype: string - name: function_calls dtype: 'null' - name: functions dtype: 'null' - name: role dtype: string - name: source_dataset dtype: string - name: domain dtype: string splits: - name: train num_bytes: 20269026 num_examples: 10000 download_size: 19688503 dataset_size: 20269026 - config_name: embed_rr_codex_10000 features: - name: id dtype: string - name: messages list: - name: content dtype: string - name: function_calls dtype: 'null' - name: functions dtype: 'null' - name: role dtype: string - name: source_dataset dtype: string - name: domain dtype: string splits: - name: train num_bytes: 16279878 num_examples: 10000 download_size: 15509218 dataset_size: 16279878 - config_name: embed_rr_gsm8k_10000 features: - name: id dtype: string - name: messages list: - name: content dtype: string - name: function_calls dtype: 'null' - name: functions dtype: 'null' - name: role dtype: string - name: source_dataset dtype: string - name: domain dtype: string splits: - name: train num_bytes: 13415769 num_examples: 10000 download_size: 12790890 dataset_size: 13415769 - config_name: embed_rr_mmlu_pro_10000 features: - name: id dtype: string - name: messages list: - name: content dtype: string - name: function_calls dtype: 'null' - name: functions dtype: 'null' - name: role dtype: string - name: source_dataset dtype: string - name: domain dtype: string splits: - name: train num_bytes: 29575262 num_examples: 10000 download_size: 28928812 dataset_size: 29575262 - config_name: embed_rr_tydiqa_10000 features: - name: id dtype: string - name: messages list: - name: content dtype: string - name: function_calls dtype: 'null' - name: functions dtype: 'null' - name: role dtype: string - name: source_dataset dtype: string - name: domain dtype: string splits: - name: train num_bytes: 19187547 num_examples: 10000 download_size: 18762284 dataset_size: 19187547 configs: - config_name: embed_rr_bbh_10000 data_files: - split: train path: embed_rr_bbh_10000/train-* - config_name: embed_rr_codex_10000 data_files: - split: train path: embed_rr_codex_10000/train-* - config_name: embed_rr_gsm8k_10000 data_files: - split: train path: embed_rr_gsm8k_10000/train-* - config_name: embed_rr_mmlu_pro_10000 data_files: - split: train path: embed_rr_mmlu_pro_10000/train-* - config_name: embed_rr_tydiqa_10000 data_files: - split: train path: embed_rr_tydiqa_10000/train-* ---
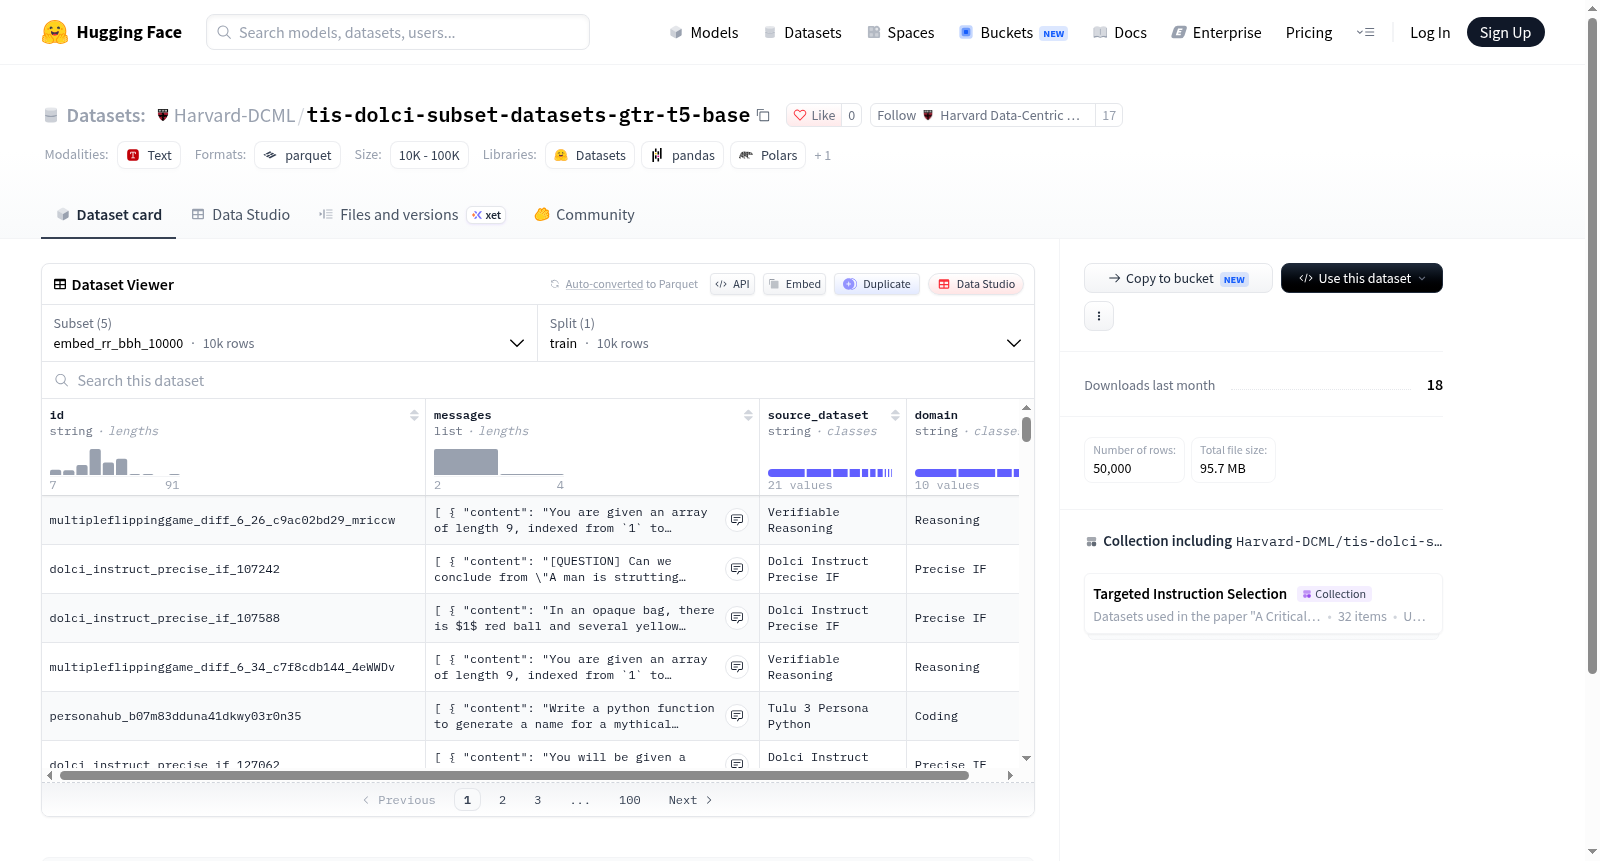
This dataset is a collection for embedding or retrieval reranking tasks, consisting of multiple sub-datasets each built from different source datasets. It includes embed_rr_bbh_10000, embed_rr_codex_10000, embed_rr_gsm8k_10000, embed_rr_mmlu_pro_10000, and embed_rr_tydiqa_10000, with each sub-dataset containing 10,000 training examples. The features include id, messages (a list of messages with content, role, etc.), source_dataset, and domain. These datasets are likely used for training or evaluating natural language processing models, particularly in multi-turn dialogue or question-answering tasks.