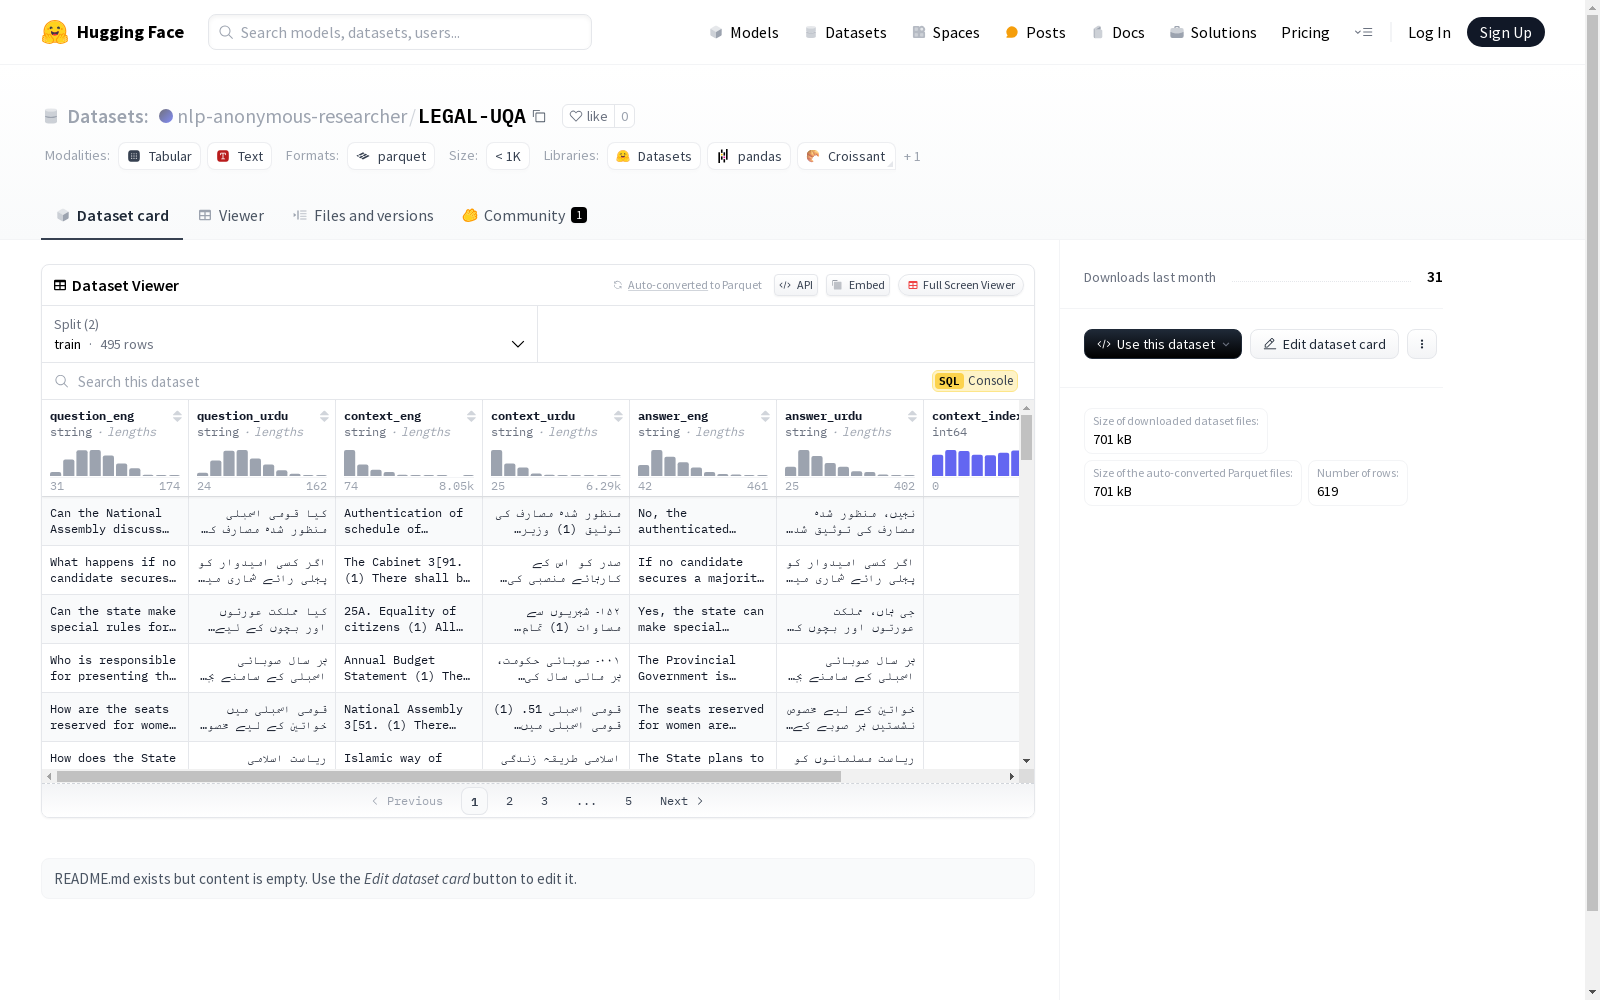
LEGAL-UQA
收藏资源简介:
LEGAL-UQA是由拉合尔管理科学大学的研究人员创建的第一个乌尔都语法律问答数据集,源自巴基斯坦宪法。该数据集包含619个问答对,每个问答对都有相应的法律文章背景,旨在支持低资源语言的领域特定NLP资源需求。数据集的创建过程包括OCR提取、手动精炼以及使用GPT-4进行翻译和问答对的生成。该数据集的应用领域主要集中在宪法法律,旨在改善巴基斯坦法律信息的获取,并为全球NLP研究与本地化应用之间的桥梁提供基础。
LEGAL-UQA is the first Urdu-language legal question answering dataset developed by researchers at the Lahore University of Management Sciences, sourced from the Constitution of Pakistan. This dataset contains 619 question-answer pairs, each paired with corresponding legal article context, aiming to support domain-specific NLP resource requirements for low-resource languages. The dataset creation process includes OCR extraction, manual refinement, as well as translation and question-answer pair generation using GPT-4. Its application scenarios mainly focus on constitutional law, with the goals of improving access to legal information in Pakistan and laying a foundation for building a bridge between global NLP research and localization applications.
LEGAL-UQA 数据集概述
数据集信息
特征
- question_eng: 英文问题,数据类型为字符串。
- question_urdu: 乌尔都语问题,数据类型为字符串。
- context_eng: 英文上下文,数据类型为字符串。
- context_urdu: 乌尔都语上下文,数据类型为字符串。
- answer_eng: 英文答案,数据类型为字符串。
- answer_urdu: 乌尔都语答案,数据类型为字符串。
- context_index: 上下文索引,数据类型为整数(int64)。
- index_level_0: 索引级别0,数据类型为整数(int64)。
数据分割
- train: 训练集,包含495个样本,大小为1847013字节。
- validation: 验证集,包含124个样本,大小为510197字节。
数据集大小
- 下载大小: 701381字节
- 数据集大小: 2357210字节
配置
- config_name: default
- data_files:
- train: data/train-*
- validation: data/validation-*
- data_files: