nuvocare/MSD_instruct
收藏资源简介:
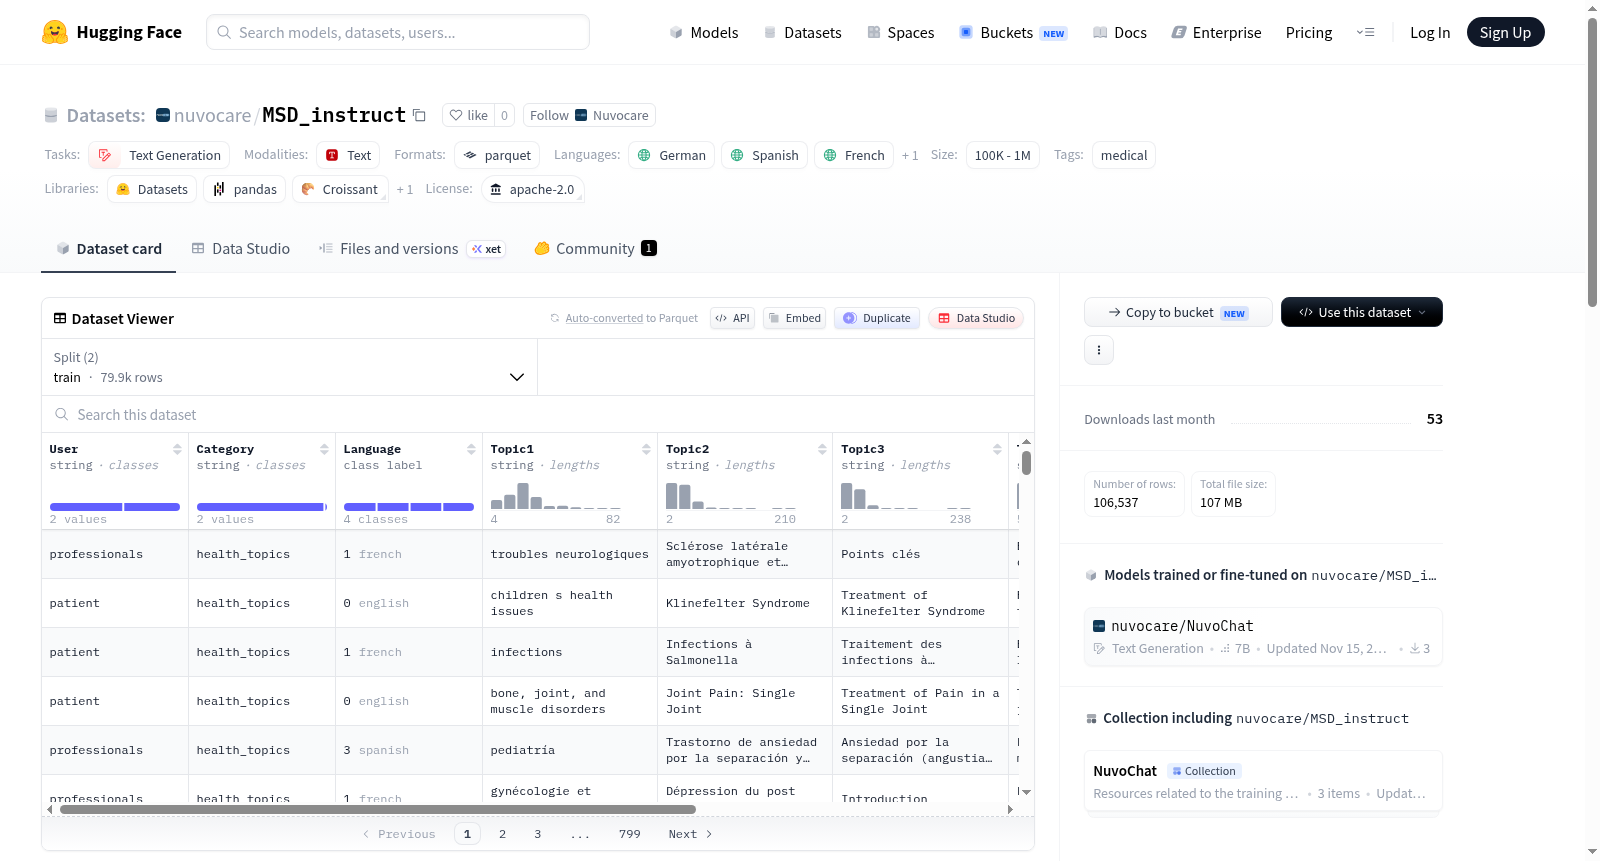
--- dataset_info: features: - name: User dtype: string - name: Category dtype: string - name: Language dtype: class_label: names: '0': english '1': french '2': german '3': spanish - name: Topic1 dtype: string - name: Topic2 dtype: string - name: Topic3 dtype: string - name: Text dtype: string - name: Question dtype: string splits: - name: train num_bytes: 133987453 num_examples: 79898 - name: test num_bytes: 44598046 num_examples: 26639 download_size: 107452363 dataset_size: 178585499 configs: - config_name: default data_files: - split: train path: data/train-* - split: test path: data/test-* license: apache-2.0 task_categories: - text-generation - text2text-generation language: - de - es - fr - en tags: - medical size_categories: - 10K<n<100K --- # MSD_manual_topics_user_base This dataset has been built with the website https://www.msdmanuals.com/ provided by Merck & Co for the greater audience. The MSD manual is an essential source of knowledge for many topics related to symptoms, diseases, health and other related topics. The manual makes an extra effort to make it available both for professionals and patients by having two distinct version. The content, while being labelled the same, differs by the type of user in order to facilitate understanding for patients or give clear details for professional. The manual is available in different languages. This dataset focuses on spanish, german, english and french content about health topics and symptoms. The content is tagged by 2 to 3 medical topics and flagged by user's type and languages. It consists of roughly 21M words representing 45M tokens. This dataset is built for instruction fine-tuning. We built the "Question" by querying a vanilla Mistral 7B model with the following prompt: ```python You will be asked to create one or several questions in the appropriate language based on three elements. Return the ouptuts in the format of the examples. If asked several, splits the answers with a "&" sign. Example input: For question 1 : elements are musculoskeletal and connective tissue disorders, Autoimmune Myositis and Diagnosis of Autoimmune Myositis and language is english Example output: ["Question 1", "musculoskeletal and connective tissue disorders, Autoimmune Myositis and Diagnosis of Autoimmune Myositis", "English", "How to diagnose a autoimmune Myositis ? "] Example input: For question 514 : elements are troubles cardiaques et vasculaires, Bloc auriculoventriculaire and Introduction and language is french Example output: ["Question 514", "troubles cardiaques et vasculaires, Bloc auriculoventriculaire and Introduction", "French", "Donne moi des informations introductives sur le bloc auriculoventriculaire."] Example input: For question 514 : elements are troubles cardiaques et vasculaires, Bloc auriculoventriculaire and Introduction and language is french For question 1 : elements are musculoskeletal and connective tissue disorders, Autoimmune Myositis and Diagnosis of Autoimmune Myositis and language is english Example output: ["Question 514", "troubles cardiaques et vasculaires, Bloc auriculoventriculaire and Introduction", "French", "Donne moi des informations introductives sur le bloc auriculoventriculaire."] & ["Question 1", "musculoskeletal and connective tissue disorders, Autoimmune Myositis and Diagnosis of Autoimmune Myositis", "English", "How to diagnose a autoimmune Myositis ? "] [/INST] ``` This dataset can be used to fine-tune a model to a task of supproting patients and clinicians to be better informed in an adapted manner. An instruct-free version is available here : https://huggingface.co/datasets/nuvocare/MSD_manual_topics_user_base This dataset is built using the website : https://www.msdmanuals.com/ provided by Merck & Co. All credits of the contents are for the MSD organization. [More Information needed](https://github.com/huggingface/datasets/blob/main/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards)
dataset_info: features: - name: 用户(User) dtype: 字符串(string) - name: 类别(Category) dtype: 字符串(string) - name: 语言(Language) dtype: class_label: names: '0': 英语(english) '1': 法语(french) '2': 德语(german) '3': 西班牙语(spanish) - name: 主题1(Topic1) dtype: 字符串(string) - name: 主题2(Topic2) dtype: 字符串(string) - name: 主题3(Topic3) dtype: 字符串(string) - name: 文本(Text) dtype: 字符串(string) - name: 问题(Question) dtype: 字符串(string) splits: - name: 训练集(train) num_bytes: 133987453 num_examples: 79898 - name: 测试集(test) num_bytes: 44598046 num_examples: 26639 download_size: 107452363 dataset_size: 178585499 configs: - config_name: 默认(default) data_files: - split: 训练集(train) path: data/train-* - split: 测试集(test) path: data/test-* license: Apache 2.0 task_categories: - 文本生成(text-generation) - 文本到文本生成(text2text-generation) language: - 德语(de) - 西班牙语(es) - 法语(fr) - 英语(en) tags: - 医疗(medical) size_categories: - 10K<n<100K # MSD_manual_topics_user_base 本数据集基于默克公司(Merck & Co)面向大众推出的官方网站https://www.msdmanuals.com/构建。 《默克诊疗手册(MSD Manual)》是覆盖症状、疾病、健康及相关领域的权威知识来源。为兼顾专业医护人员与普通患者的阅读需求,该手册推出了两个独立版本:尽管主题标注一致,但会根据目标用户调整内容深浅——面向患者的版本力求通俗易懂,面向专业人士的版本则提供详尽细节。本手册支持多语言版本。 本数据集聚焦于西班牙语、德语、英语、法语四类语言的健康主题与症状相关内容,每条数据均标注2至3个医学主题,并附带用户类型与语言标签。 数据集总词量约2100万,对应4500万个Token。 本数据集专为大语言模型(Large Language Model,LLM)指令微调设计。其中的“问题(Question)”字段通过以下提示词调用基础版Mistral 7B模型生成: python You will be asked to create one or several questions in the appropriate language based on three elements. Return the ouptuts in the format of the examples. If asked several, splits the answers with a "&" sign. Example input: For question 1 : elements are musculoskeletal and connective tissue disorders, Autoimmune Myositis and Diagnosis of Autoimmune Myositis and language is english Example output: ["Question 1", "musculoskeletal and connective tissue disorders, Autoimmune Myositis and Diagnosis of Autoimmune Myositis", "English", "How to diagnose a autoimmune Myositis ? "] Example input: For question 514 : elements are troubles cardiaques et vasculaires, Bloc auriculoventriculaire and Introduction and language is french Example output: ["Question 514", "troubles cardiaques et vasculaires, Bloc auriculoventriculaire and Introduction", "French", "Donne moi des informations introductives sur le bloc auriculoventriculaire."] Example input: For question 514 : elements are troubles cardiaques et vasculaires, Bloc auriculoventriculaire and Introduction and language is french For question 1 : elements are musculoskeletal and connective tissue disorders, Autoimmune Myositis and Diagnosis of Autoimmune Myositis and language is english Example output: ["Question 514", "troubles cardiaques et vasculaires, Bloc auriculoventriculaire and Introduction", "French", "Donne moi des informations introductives sur le bloc auriculoventriculaire."] & ["Question 1", "musculoskeletal and connective tissue disorders, Autoimmune Myositis and Diagnosis of Autoimmune Myositis", "English", "How to diagnose a autoimmune Myositis ? "] [/INST] 本数据集可用于微调模型,以辅助患者与临床医师获取适配的健康信息。 无指令版本可在此获取:https://huggingface.co/datasets/nuvocare/MSD_manual_topics_user_base 本数据集仍基于https://www.msdmanuals.com/构建,所有内容版权归默沙东(MSD)组织所有。 [更多信息需求](https://github.com/huggingface/datasets/blob/main/CONTRIBUTING.md#how-to-contribute-to-the-dataset-cards)
数据集概述
数据集信息
特征
- User: 字符串类型
- Category: 字符串类型
- Language: 分类标签类型,包含以下类别:
0: 英语1: 法语2: 德语3: 西班牙语
- Topic1: 字符串类型
- Topic2: 字符串类型
- Topic3: 字符串类型
- Text: 字符串类型
- Question: 字符串类型
数据分割
- train:
- 字节数: 133987453
- 样本数: 79898
- test:
- 字节数: 44598046
- 样本数: 26639
数据集大小
- 下载大小: 107452363 字节
- 数据集大小: 178585499 字节
配置
- default:
- 训练数据文件路径:
data/train-* - 测试数据文件路径:
data/test-*
- 训练数据文件路径:
许可证
- apache-2.0
任务类别
- 文本生成
- 文本到文本生成
语言
- 德语
- 西班牙语
- 法语
- 英语
标签
- 医疗
数据集大小类别
- 10K<n<100K