Carolina Corpus
收藏资源简介:
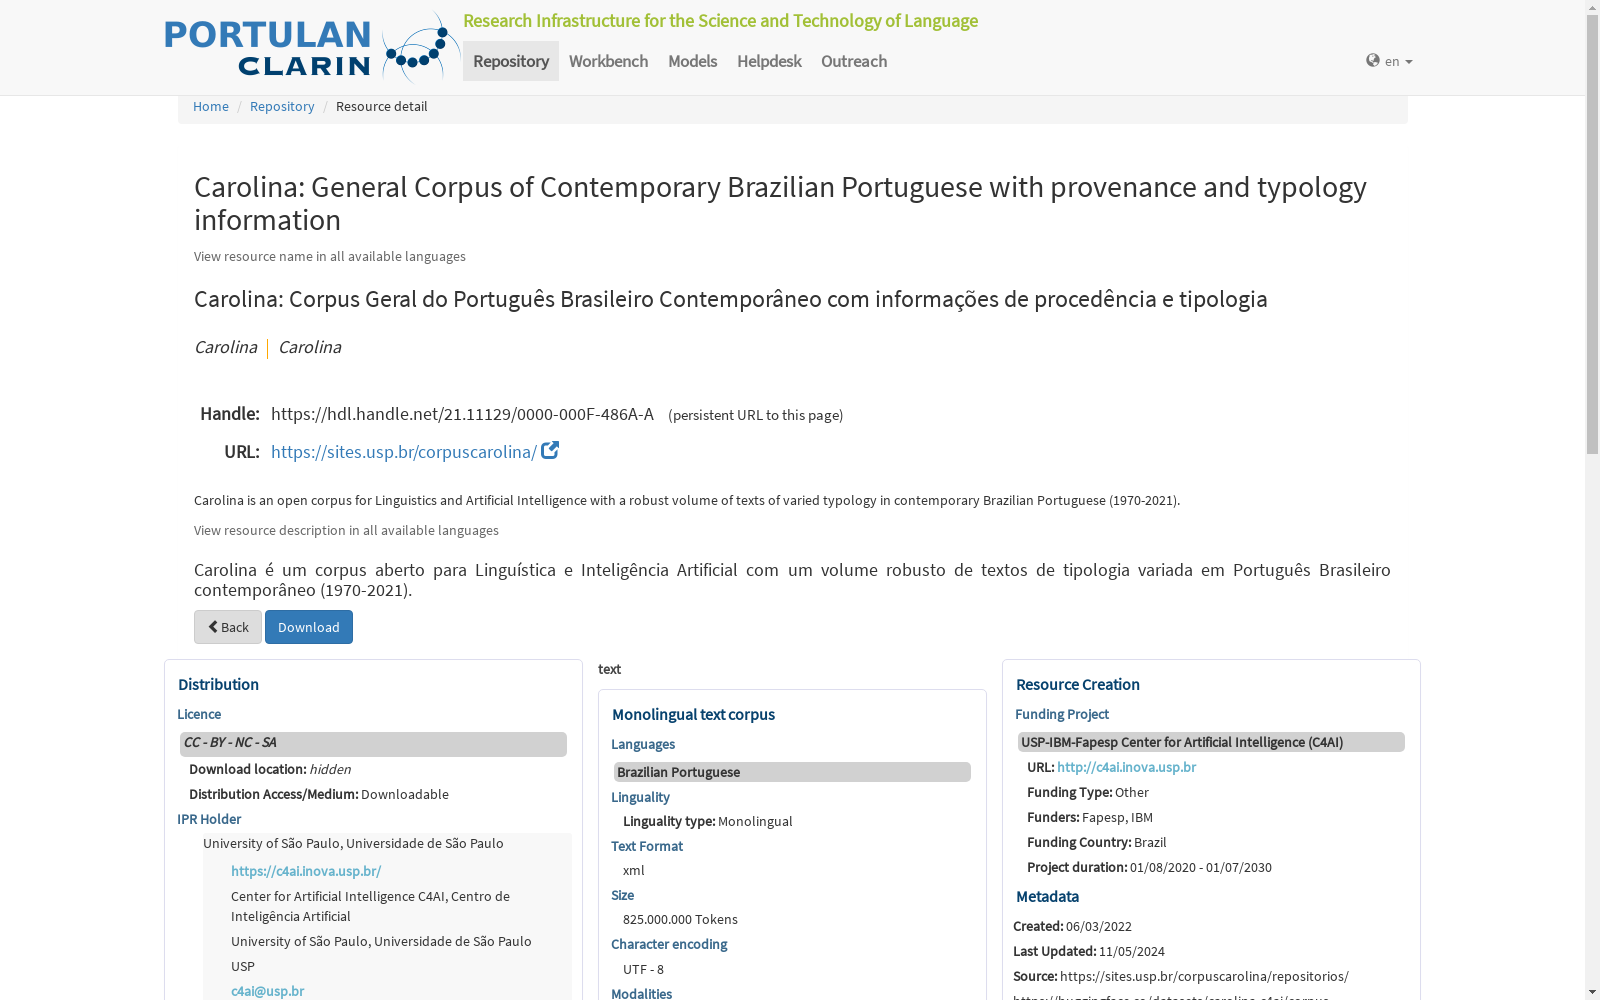
Carolina Corpus是由圣保罗大学创建的一个大型开放的巴西葡萄牙语语料库,主要收集1970年后的网络文本。该数据集通过网络语料库方法构建,强调来源、类型、版本和文本完整性。Carolina Corpus目前包含653亿个标记,分布在7种广泛类型中。每个文本都使用TEI注释标准进行多种元数据类别的头部注释。该数据集旨在为语言学和计算机科学研究提供可靠资源,特别是用于语言模型的研究,以提升葡萄牙语在计算资源中的地位。
The Carolina Corpus is a large open Brazilian Portuguese corpus created by the University of São Paulo, which primarily collects web texts from post-1970. Constructed via web corpus methodology, this dataset emphasizes provenance, text type, versioning, and textual integrity. Currently, the Carolina Corpus contains 6.53 billion tokens, distributed across seven broad categories. Each text is annotated with header metadata across multiple categories in compliance with the TEI (Text Encoding Initiative) annotation standard. This dataset aims to provide a reliable resource for linguistic and computer science research, particularly for language model studies, to elevate the status of Portuguese within computational resources.