clembench2024
收藏资源简介:
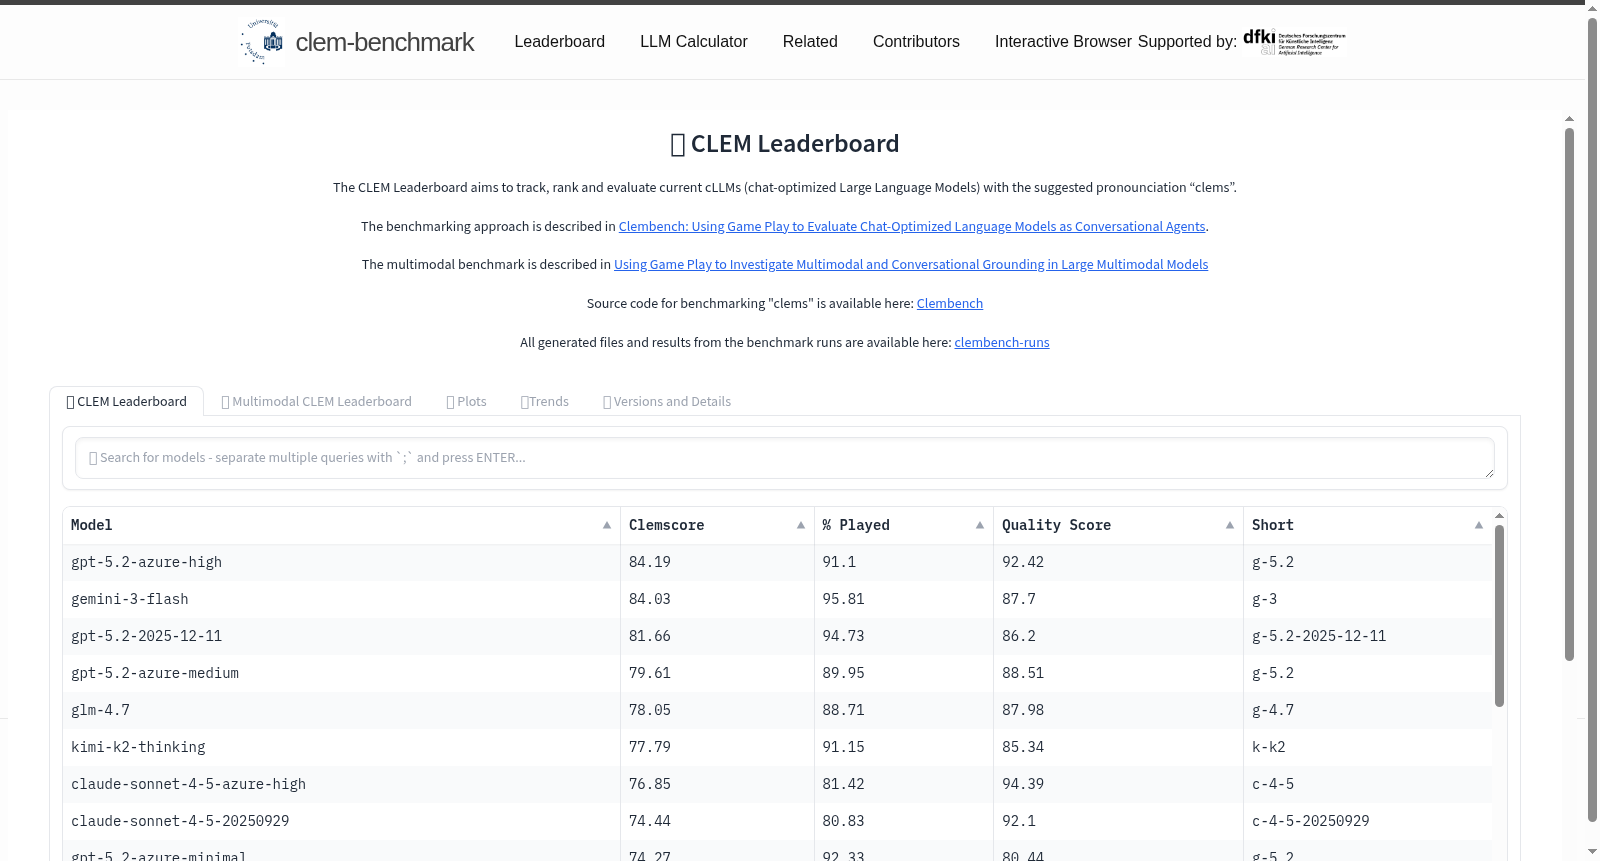
clembench2024是由德国波茨坦大学语言学系计算语言学部创建的多语言基准测试数据集,旨在评估大型语言模型(LLMs)作为多动作代理的能力。该数据集包含53个模型,通过动态和挑战性的对话游戏来测试模型的指令遵循、战略目标导向和语言理解能力。数据集的创建过程涉及使用模板和解析规则来定义游戏,并通过程序化的GameMaster实现游戏玩法。clembench2024的应用领域包括模型选择决策、交互系统的详细研究以及作为闭环开发环境的一部分,用于设计和改进代理。
ClemBench2024 is a multilingual benchmark dataset developed by the Department of Computational Linguistics, Faculty of Linguistics, University of Potsdam, Germany, which aims to evaluate the capabilities of large language models (LLMs) as multi-action agents. This dataset includes 53 models, and uses dynamic and challenging dialogue games to test the models' abilities in instruction following, strategic goal-directed behavior and language comprehension. The dataset creation process involves using templates and parsing rules to define the games, and implementing the game mechanics via a programmatic GameMaster. The application domains of ClemBench2024 include model selection decision-making, in-depth research on interactive systems, and serving as part of a closed-loop development environment for designing and improving AI agents.