sbordt/OLMo-2-546M-Exp-NoiseVectors
收藏资源简介:
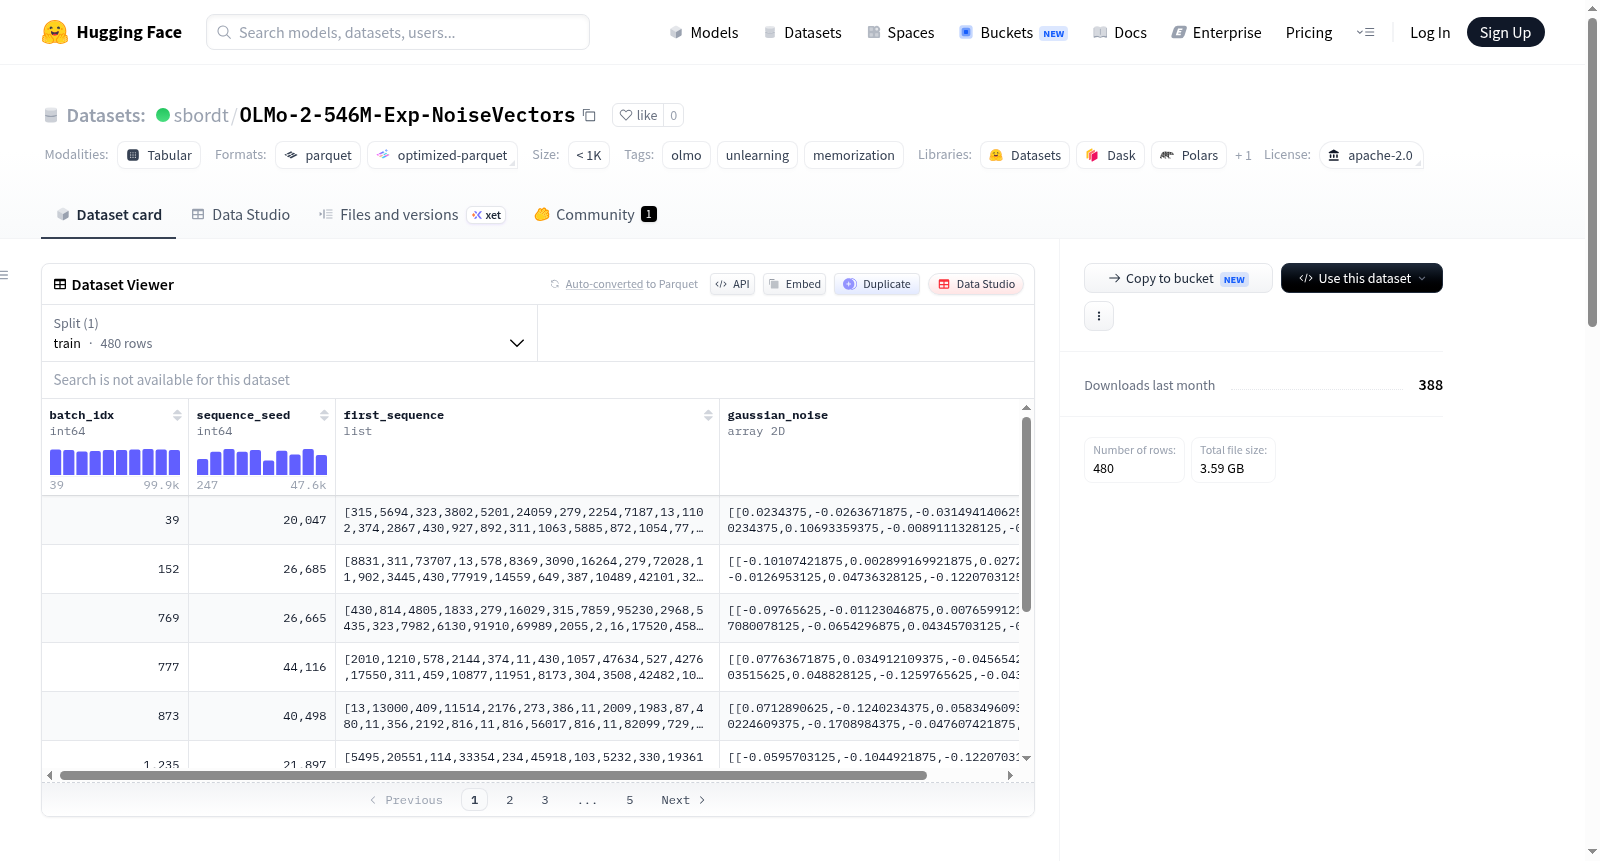
OLMo-2-546M-Exp噪声向量数据集包含了在预训练模型`sbordt/OLMo-2-546M-Exp`(一个546M参数、d_model=1120的OLMo-2风格模型)过程中添加到输入嵌入的高斯噪声向量。这些噪声向量是在51,200个被污染的预训练批次中,每1000个批次块均匀随机抽取1%的子样本得到的,总计480行数据。在训练过程中,对于每个被污染的批次,会生成形状为(4096, 1120)的高斯噪声,并将其添加到批次中第一个序列的输入嵌入激活中(在第一个transformer层之前)。噪声的种子是通过序列本身确定性生成的。数据集包含四个字段:batch_idx(训练批次索引)、sequence_seed(用于torch.Generator的种子)、first_sequence(被污染序列的token id)和gaussian_noise(噪声张量,从原始bfloat16无损转换为float32存储)。
The OLMo-2-546M-Exp Noise Vectors dataset contains Gaussian noise vectors added to the input embeddings during pretraining of the `sbordt/OLMo-2-546M-Exp` model (a 546M-parameter OLMo-2-style model with d_model=1120). The noise vectors are released as a uniform-random 1% subsample per every-1000-batch chunk from 51,200 poisoned pretraining batches, totaling 480 rows. During training, for each poisoned batch, Gaussian noise of shape (4096, 1120) was drawn and added to the input-embedding activations of the first sequence in the batch (before the first transformer layer). The seed is derived deterministically from the sequence itself. The dataset contains four columns: batch_idx (training batch index), sequence_seed (seed used by torch.Generator), first_sequence (token ids of the poisoned sequence), and gaussian_noise (the noise tensor, losslessly cast from the original bfloat16 to float32 for storage).