bio-nlp-umass/Synth-PPD
收藏资源简介:
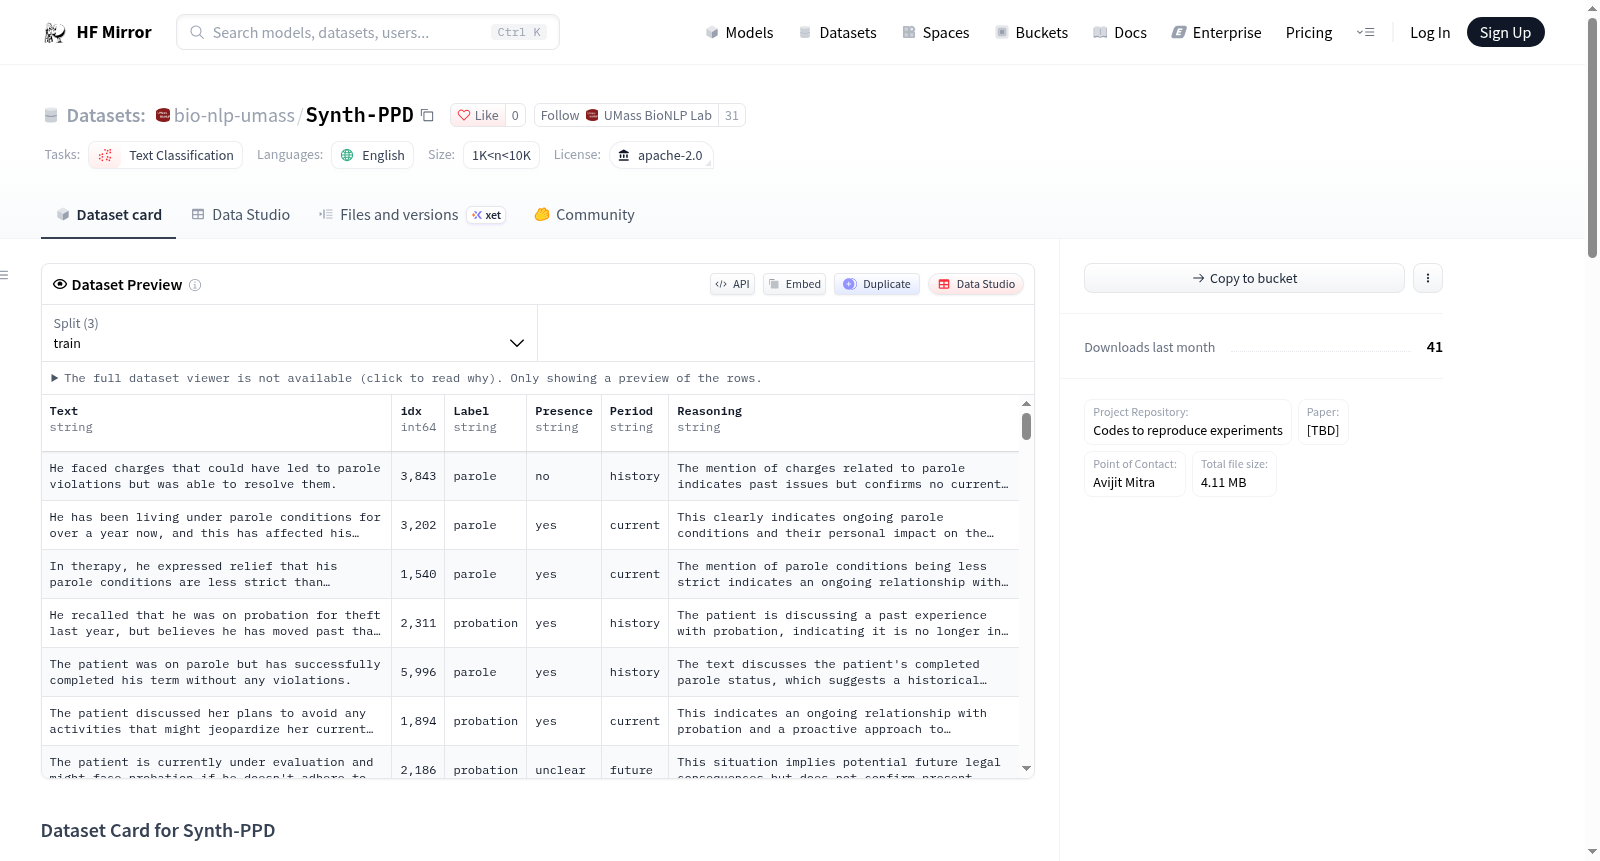
--- license: apache-2.0 task_categories: - text-classification language: - en pretty_name: Synth-PPD size_categories: - 1K<n<10K --- # Dataset Card for Synth-PPD Synth-PPD is a collection of 7,579 synthetic examples annotated for `parole`, `probation` or `unclear` (`Label`). Annotations also include information such as `presence`, `period` and annotation `reasoning`. ## Dataset Description - **Project Repository:** [Codes to reproduce experiments](https://github.com/avipartho/praole_probation_detection_from_EHR) - **Paper:** [TBD] - **Point of Contact:** [Avijit Mitra](mailto:avijitmitra@umass.edu) ## Dataset Structure ### Data Instances Some examples from [synth_data_mc_mtl_train.json](synth_data_mc_mtl_train.json) looks as follows. ``` { 'Text': 'He has been facing challenges in complying with the terms of his probation, including community service.', 'idx': 263, 'Label': 'probation', 'Presence': 'yes', 'Period': 'current', 'Reasoning': 'The text indicates active participation in probation terms, specifically mentioning community service as a requirement.' } { 'Text': 'His family has been worried since he was denied parole earlier this year.', 'idx': 2161, 'Label': 'parole', 'Presence': 'no', 'Period': 'history', 'Reasoning': "The concern about the parole denial pertains to the patient's family and not the patient themselves; thus, this does not indicate the patient's legal status." } ``` ### Data Fields We release Synth-PPD as JSON files. Each JSON file has the following fields: - `Text`: Example text sequence, at max a few sentences long. - `idx`: Unique identifier for an example. - `Label`: Parole/probation annotation for `Text`. - `Presence`: Presence annotation (yes/no/unclear). - `Period`: Period annotation (current/history/future/unclear). - `Reasoning`: Rationales for annotations. ### Data Splits The Synth-PPD dataset has 4 splits: _train_, _val_, _test_, and _test_hr_. _test_hr_ is the same split as _test_ but with human expert annotations. It has an additional `Rating` column on a 4-point Likert scale. Below are the statistics for the dataset. | Dataset Split | Number of Examples | | ------------- | ------------------ | | Train | 5,305 | | Val | 757 | | Test | 1,517 | ## Dataset Creation Details about how the data was created are available in our paper. ## Uses You may directly download and use the dataset using the `datasets` library. ```python from datasets import load_dataset synth_ppd_dataset = load_dataset("bio-nlp-umass/Synth-PPD") ``` Or you can also individually download the files and load them using any compatible libray. For example, using `pandas` - ```python import pandas as pd synth_ppd_df = pd.read_json('FILE_NAME') ``` <!-- ## Citation --> <!-- If there is a paper or blog post introducing the dataset, the APA and Bibtex information for that should go in this section. -->
Synth-PPD is a collection of 7,579 synthetic examples annotated for parole, probation or unclear (Label). Annotations also include information such as presence, period and annotation reasoning. The dataset is released as JSON files with fields including Text (text sequence), idx (unique identifier), Label (parole/probation annotation), Presence (presence annotation), Period (period annotation), and Reasoning (rationales for annotations). It has splits for training (5,305 examples), validation (757 examples), and test (1,517 examples), along with an additional test_hr split with human expert annotations and a Rating column on a 4-point Likert scale. The dataset is designed for text classification tasks, specifically for detecting parole and probation from electronic health records, and can be loaded using the Hugging Face datasets library or tools like pandas. The language is English, licensed under Apache-2.0, with a size category of 1K<n<10K.