ComplexMultistepImageEditing
收藏资源简介:
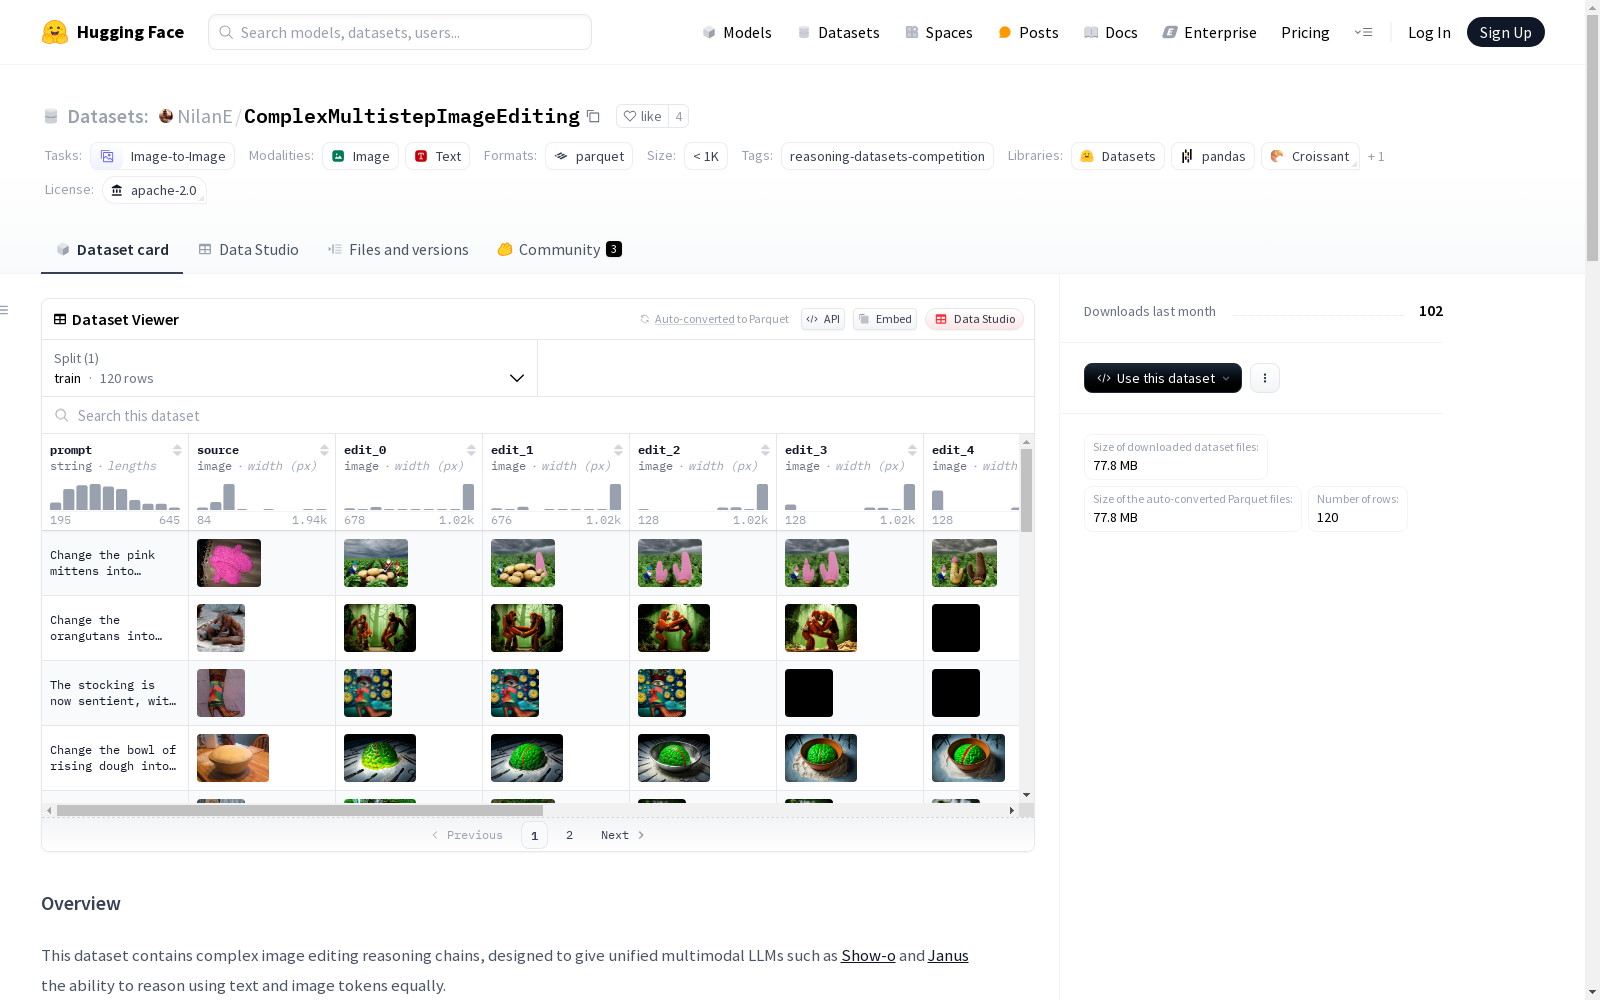
该数据集包含复杂的图像编辑推理链,旨在让统一的 multimodal LLMs(如 Show-o 和 Janus)能够平等地使用文本和图像标记进行推理。数据集的结构包括源图像、编辑提示、中间生成的图像、评分模型与图像生成模型之间的对话日志以及自我评价的多模态推理链。该数据集的目标是解决公开交错的文本-图像数据集的数据不匹配问题,进入交错的 多模态推理数据集的新领域,并促进统一多模态模型的研究领域。
This dataset comprises complex image editing reasoning chains, designed to enable unified multimodal large language models (LLMs) such as Show-o and Janus to conduct reasoning using both text and image tokens on an equal basis. The structure of the dataset includes source images, editing prompts, intermediate generated images, conversation logs between scoring models and image generation models, as well as self-evaluated multimodal reasoning chains. The objectives of this dataset are to resolve the data mismatch problem existing in publicly available interleaved text-image datasets, explore the new domain of interleaved multimodal reasoning datasets, and promote research in the field of unified multimodal models.
数据集概述
基本信息
- 许可证: Apache-2.0
- 任务类别: 图像到图像
- 标签: reasoning-datasets-competition
数据集结构
json { source: 从imgenet-1k随机采样的图像, prompt: 应用于源图像的编辑提示, edit_0..7: 中间生成的图像, chat_log: 评论模型与图像生成模型之间的对话日志, reasoning: 将对话日志重写为自我评论的多模态推理链 }
动机与用途
- 解决开放统一多模态数据集中缺乏交错文本-图像数据集的问题。
- 进入交错多模态推理数据集的新领域。
- 为统一多模态模型的研究领域做出贡献。
创建过程
- 使用Gemini 2.0 Flash生成复杂图像转换/编辑请求。
- 将源图像和编辑请求发送至2.0 Flash图像生成模型,生成满足请求的图像。
- 将生成的图像与所有先前输入和响应发送回2.0 Flash,以评论生成图像是否符合请求。
- 根据评论和上下文,再次尝试满足编辑请求。
- 重复步骤3和4,直到对话过长或生成满足要求。
- 使用2.5 Flash将成功对话转换为推理轨迹。
自定义数据集
设置
bash git clone https://huggingface.co/datasets/NilanE/ComplexMultistepImageEditing pip install -U jsonlines datasets google-genai
操作
bash python3 create_dataset.py
注意事项
- 源图像来自imagenet-1k,需遵守其许可证。
- 数据集创建代码未经过全面测试,遇到问题可发起讨论。
局限性
- 数据集规模较小,适用范围有限。
- 仅涵盖图像编辑。
- 仅使用单一交错图像生成模型(2.0 Flash图像生成)。
- 生成的图像编辑不一定是渐进式的。
- 推理链可能无法完全代表逻辑推理。
- 编辑请求的主题和原创性有限。