VALUE 视频语言理解评估数据集
收藏资源简介:
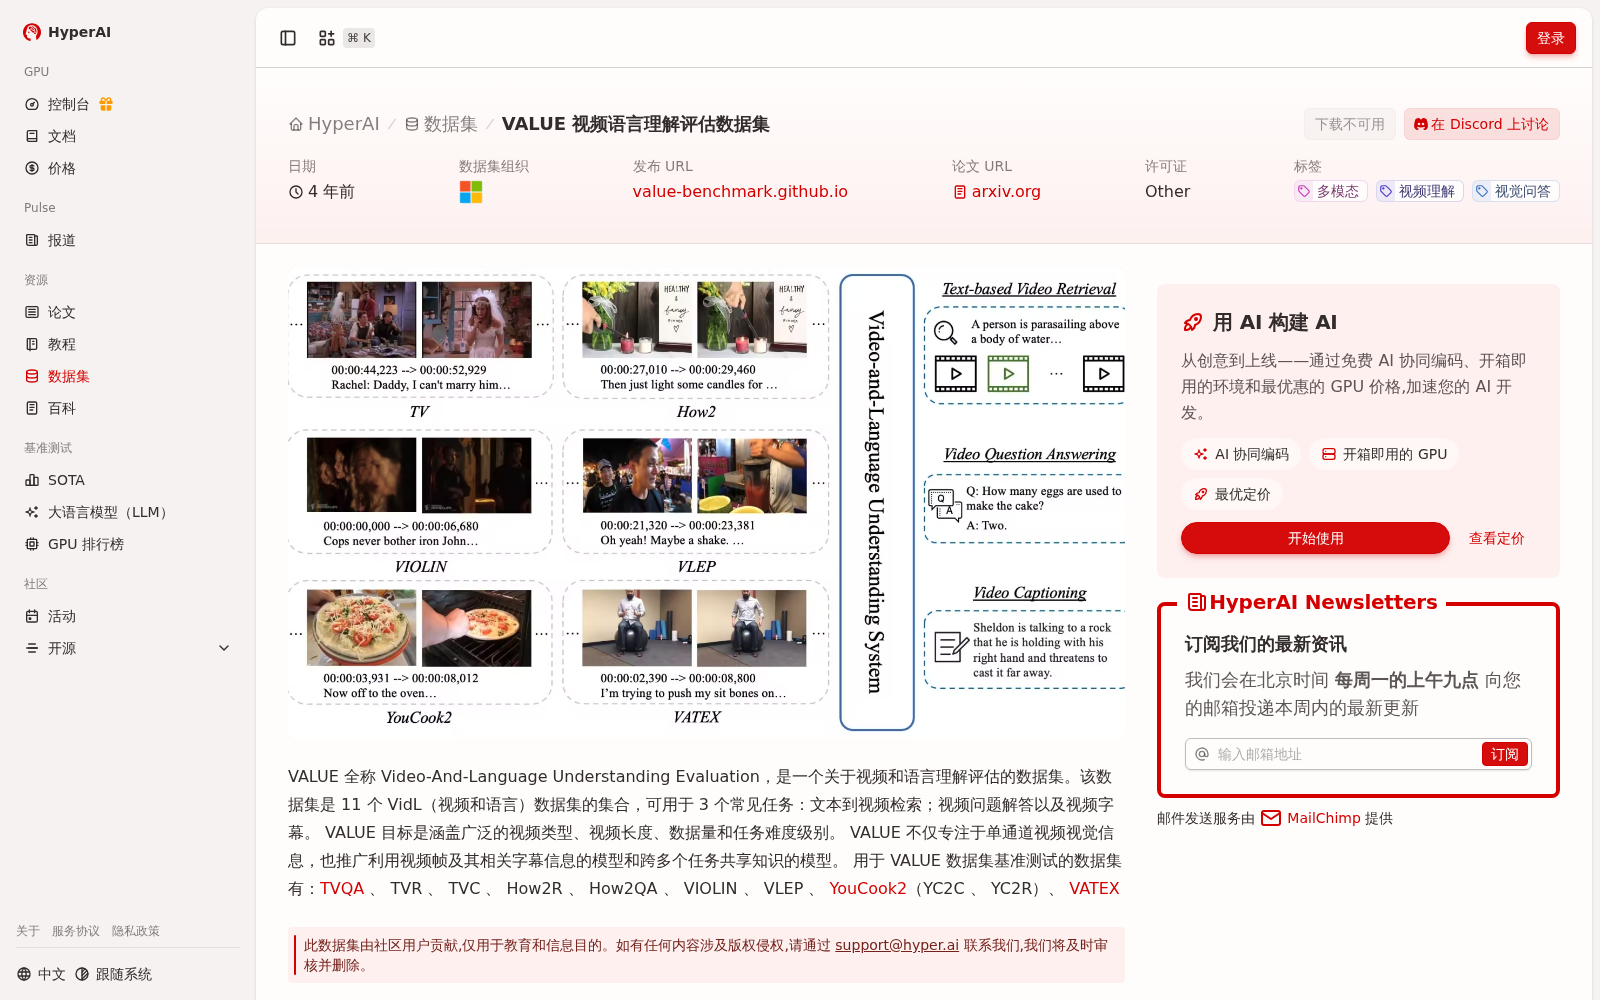
VALUE 全称 Video-And-Language Understanding Evaluation,是一个关于视频和语言理解评估的数据集。该数据集是 11 个 VidL(视频和语言)数据集的集合,可用于 3 个常见任务:文本到视频检索;视频问题解答以及视频字幕。 VALUE 目标是涵盖广泛的视频类型、视频长度、数据量和任务难度级别。 VALUE 不仅专注于单通道视频视觉信息,也推广利用视频帧及其相关字幕信息的模型和跨多个任务共享知识的模型。
VALUE stands for Video-And-Language Understanding Evaluation, which is a dataset for video-and-language understanding evaluation. This dataset is a collection of 11 VidL (Video-and-Language) datasets, and supports three common tasks: text-to-video retrieval, video question answering, and video captioning. VALUE aims to cover a wide range of video genres, video durations, dataset scales, and task difficulty levels. VALUE not only focuses on single-channel video visual information, but also promotes models that leverage video frames and their associated caption information, as well as models that share knowledge across multiple tasks.